Unlimited OCR 2 is here, and it's open source. 📖 ✨ Longer documents...

Baidu Inc.@Baidu_Inc
13 views
Oct 27, 2026
~1 min read
Advertisement
1
Unlimited OCR 2 is here, and it's open source. 📖 ✨
Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references.
Here's what it delivers:
- Document parsing at virtually any length, within a finite context window
- Nearly constant per-step decoding latency and memory footprint as documents grow longer
- State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages
Check out the model here ↓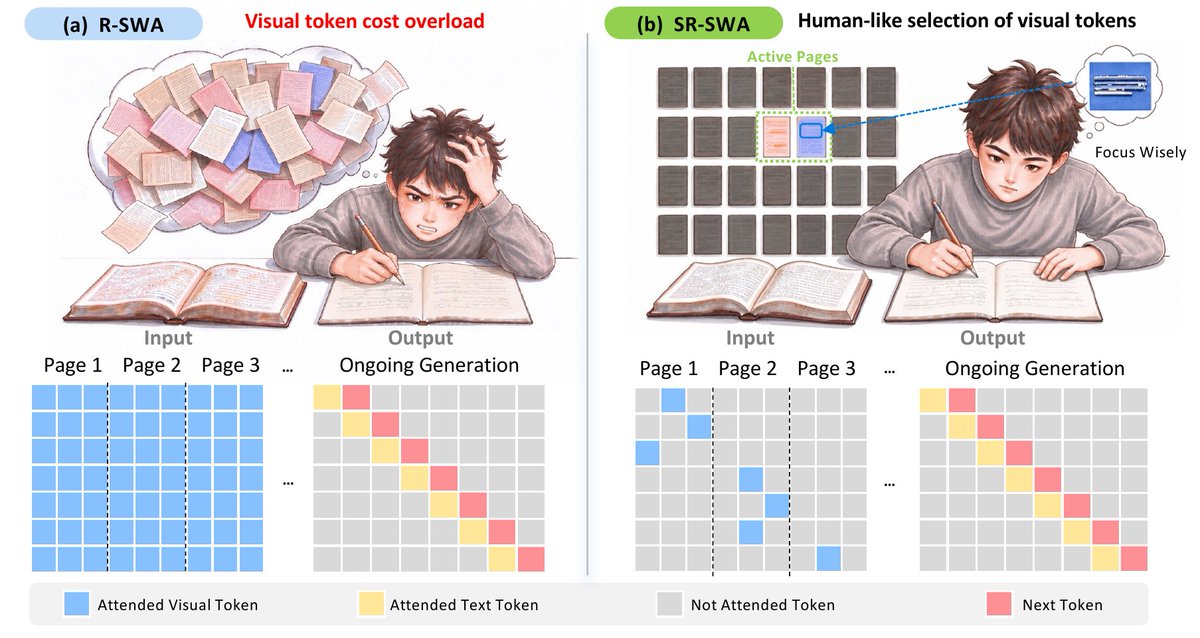

Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references.
Here's what it delivers:
- Document parsing at virtually any length, within a finite context window
- Nearly constant per-step decoding latency and memory footprint as documents grow longer
- State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages
Check out the model here ↓
2