Training large models with RL typically runs on a fixed homogeneous...

Modal@modal
7 views
Oct 14, 2026
~1 min read
Advertisement
1
Training large models with RL typically runs on a fixed homogeneous cluster of the latest accelerators for numerical stability and faster throughput. This throws away inference optimization work done for other vendors and generations, limits the capacity you can utilize, and is unnecessarily expensive.
So we trained a model on agentic coding tasks using fully asynchronous RL and mixed-precision, mixed-accelerator samplers. With off-policy correction, training stayed stable through convergence, on par with homogeneous samplers, at a lower cost.
So we trained a model on agentic coding tasks using fully asynchronous RL and mixed-precision, mixed-accelerator samplers. With off-policy correction, training stayed stable through convergence, on par with homogeneous samplers, at a lower cost.
0:12
2
We use Miles from @radixark as the RL framework, with @sgl_project samplers and a Megatron-LM trainer that updates the policy in BF16 on B200 GPUs. There are two setups:
1. Mixed samplers that span six kinds of accelerators and three precisions (BF16, FP8 and NVFP4).
2. Homogeneous samplers that run only on B200s with BF16 weights and a BF16 KV cache.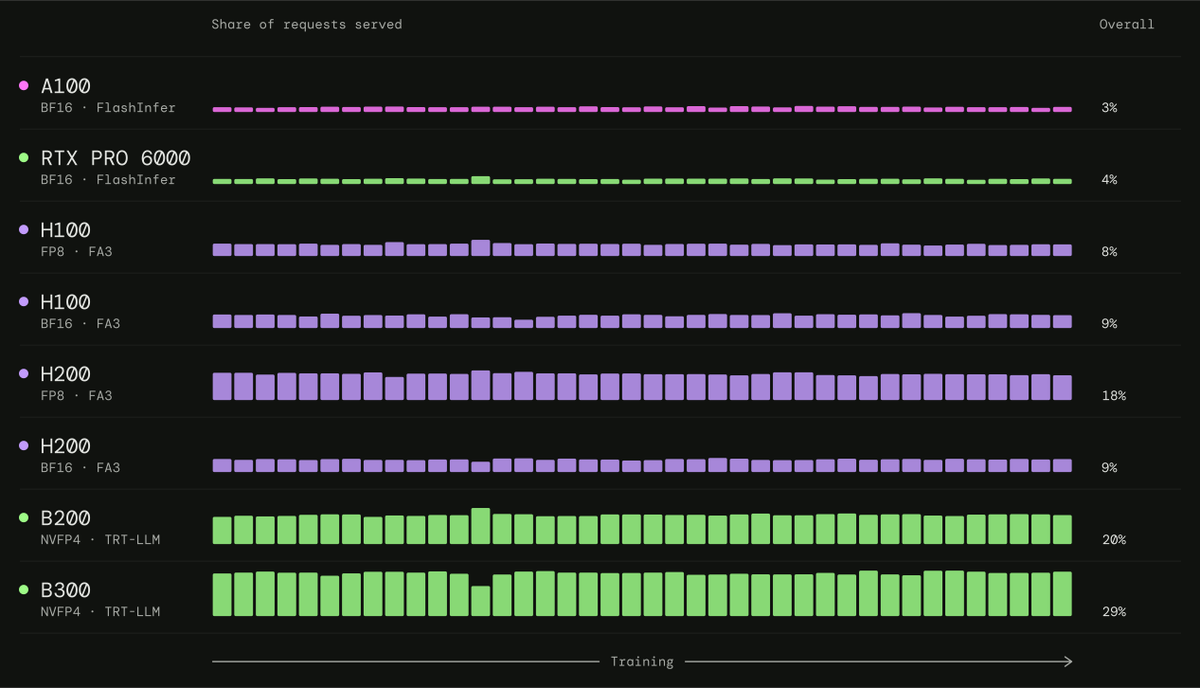
1. Mixed samplers that span six kinds of accelerators and three precisions (BF16, FP8 and NVFP4).
2. Homogeneous samplers that run only on B200s with BF16 weights and a BF16 KV cache.
3
Starting from standard GRPO, we apply off-policy correction consisting of masked importance sampling, score centering, and top-p sampling with mask replay. As a result, training on the mixed samplers becomes stable, as evaluated on SWE-bench Pro V2.

4
Despite a 4.7× larger sampler–trainer KL on average, it matches the performance of homogeneous samplers while being 15% cheaper. Note that this configuration was not heavily optimized for cost efficiency, so further gains are readily available.

5
Why not true on-policy RL? Full alignment of the sampler with the trainer is expensive. So why not align only certain aspects? Although the magnitude of the mismatch is lowered, it still continues to grow. Off-policy correction fixes this growth, which we argue matters more.

6
Read the full post: modal.com/blog/toward-rl…
