What does RL learn from 10 assembly tasks in a row, with sparse...

Mateo Guaman Castro@mateoguaman
9 views
Oct 14, 2026
~2 min read
Advertisement
1
What does RL learn from 10 assembly tasks in a row, with sparse reward only at the very end of all 10 tasks? Traditionally, absolutely nothing!
That’s 1,125 actions over 45 seconds. Even if a random policy somehow nails each task 1% of the time, chaining all 10 happens with probability 10⁻²⁰. Worse odds than winning Powerball twice in a row.
Excited to share AlphaNIST, a single policy which achieves 98.2% success rate across all tasks, and is able to solve 10 assemblies in a row under sparse reward! Check out our website: alpha-nist.github.io.
More details in @octi_zhang ‘s thread, and some extra comments of my own below! 🧵
0:10
Octi Zhang@octi_zhang
(1/6) From @GoogleDeepmind’s AlphaGo to AlphaZero, we saw machines find moves that reached beyond what we’d imagined for them. No one taught them those strategies. They emerged from reinforcement learning: playing, failing, and trying again under a single binary task reward for success or failure. Inspired by them, we couldn’t help but wonder: what might a robot discover if we gave it that same freedom to learn?
That question led us to AlphaNIST. Starting tabula rasa, with that same binary reward plus only a simple control cost, a single policy solves all 20 @NIST assembly tasks at a 98.2% success rate in simulation. More surprising still, AlphaNIST can complete 10 different tasks in a row, receiving that reward only once, after all 10 are done.
Just as AlphaGo’s strategies surprised its creators, AlphaNIST discovered dexterous strategies we couldn’t have come up with ourselves.
Paper: arxiv.org/abs/2610.13354
Website: alpha-nist.github.io
2
The fix: don’t explore from scratch. OmniReset resets episodes into states along the whole task, so reward is always within reach. SGS samples tasks by success rate, so rollouts go where the gradient signal is. We were already able to train a few of the NIST tasks in SGS, but we continued to push these ideas further.
One of the most interesting results is that training a single policy for all tasks outperforms training task-specific specialists, showing us signs of positive transfer!
One of the most interesting results is that training a single policy for all tasks outperforms training task-specific specialists, showing us signs of positive transfer!
3
There were many improvements between SGS and AlphaNIST, including using Newton instead of PhysX for a massive boost in performance, improving our reset distributions, our robot controller parameters, our observations and network architecture, and most importantly, introducing a unified multi-task formulation.
One that I am most surprised by is how all of these improvements stacked to allow us to train with this reward function. That’s it! Four very general terms, with the bulk of the gradient signal as a sparse task reward. In fact, there is only a single coefficient to tune for the entire “cost” of this reward function!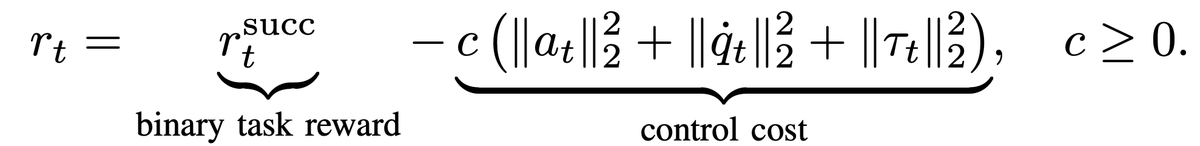
One that I am most surprised by is how all of these improvements stacked to allow us to train with this reward function. That’s it! Four very general terms, with the bulk of the gradient signal as a sparse task reward. In fact, there is only a single coefficient to tune for the entire “cost” of this reward function!
4
We are now able to train a policy which solves all 20 NIST tasks with just 64K parallel environments, although it does take 3x as long as our SGS experiments. We’ll happily take the tradeoff! And we see the same trend that we saw in SGS: as we are able to solve harder and harder problems, SGS still makes better use of compute to achieve higher success rates in a shorter time. Check them all out here below!
1:43
5
This was amazing collaboration between @NVIDIARobotics and @uwcse, which allowed us to push our academic ideas further and at higher scale. Amazing work by @octi_zhang, @Iretiayo, @rosario_scaling, @patrickhyin, Tobias Widmer, @milesmacklin, Chris Amevor, @dylanturpin, @DirkVanGelder, Jan Carius, @ankurhandos, @gavrielstate, Yunrong Guo, and Yashraj Narang. And of course, this work pays homage to the AlphaGo/AlphaZero results from @GoogleDeepMind , which continue to be a huge source of inspiration for us.
