When constructing models of the world, we aim for good...

Christopher W. Lynn@ChrisWLynn
7 views
May 17, 2025
~1 min read
Advertisement
1
When constructing models of the world, we aim for good compressions: models that are as accurate as possible with as few details as possible. But which details should we include in a model?
An answer lies in the "minimax entropy" principle 👇
arxiv.org/abs/2505.01607
An answer lies in the "minimax entropy" principle 👇
arxiv.org/abs/2505.01607
2
Information theory makes these intuitions concrete: Each model gives us an encoding of the data, and the shortest code provides the best compression of the data. This is the minimum description length (MDL) principle
3
Starting only with MDL, we show that the optimal details provide as much information about the data as possible while remaining maximally random with regard to all unobserved details
This "minimax entropy" principle was proposed 25 years ago but remains largely unexplored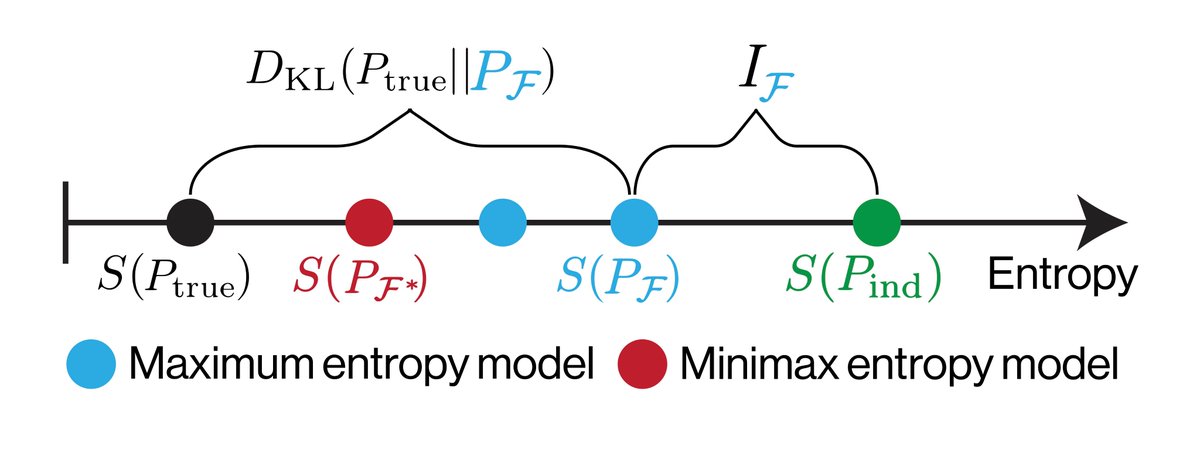
This "minimax entropy" principle was proposed 25 years ago but remains largely unexplored
4
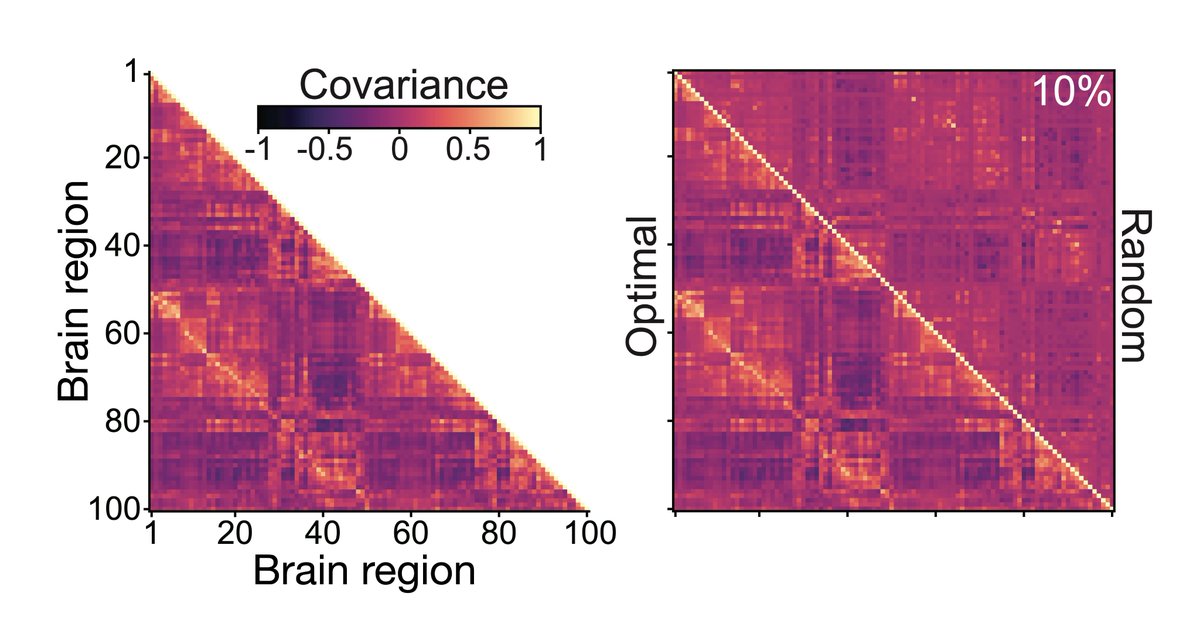
We review emerging applications, which range from neuroscience and biology to machine learning and engineering...
5
...but these applications are limited by our ability to solve difficult statistical physics problems! We thus need new creative methods in order to construct optimal compressions of complex systems.
6
Huge shoutout to my student David Carcamo for leading this paper, and Nick Weaver and Purushottam Dixit for invaluable contributions! ❤️