@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on...

Ulisse Mini@MiniUlisse
14 views
Oct 22, 2026
~2 min read
Advertisement
1
@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on pointed things and not round ones. on the essay's own photos (top), that holds. on other ImageNet photos (bottom), all four combinations happen: round fluffy faces fire, pointy German shepherds stay silent 🧵


Nick@nickcammarata
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com
2
some context: I got into this by training myself to predict this neuron. I'd recommend trying it before reading on:
ulissemini.github.io/4e55-game/
(the next tweet will contain Claude prompts that get good scores, so play now to avoid spoilers.)
ulissemini.github.io/4e55-game/
(the next tweet will contain Claude prompts that get good scores, so play now to avoid spoilers.)
3
while playing, thinking "pointy vs round" or "V-shaped" made me worse at it.
so I gave Claude each one as the explanation and had it predict the neuron on 200 held-out photos: near chance (53%, 57%). a plain list of nouns got 90%; looking up the photo's predicted class got 94%.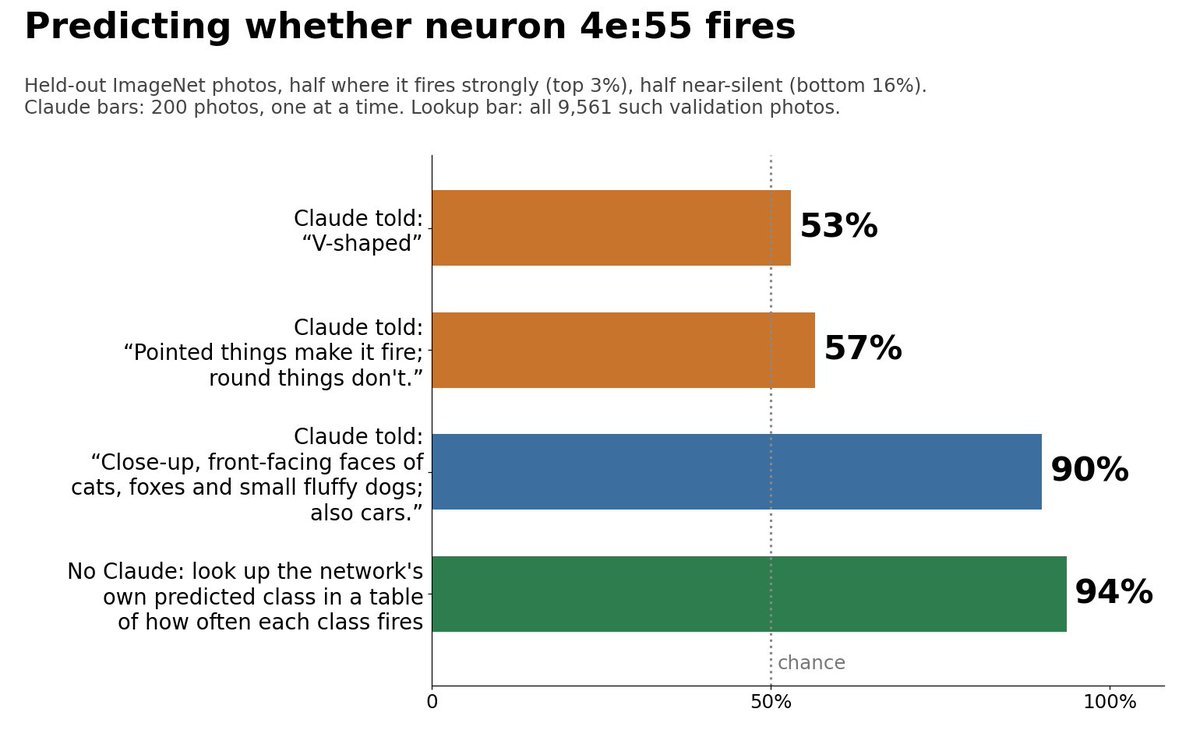
so I gave Claude each one as the explanation and had it predict the neuron on 200 held-out photos: near chance (53%, 57%). a plain list of nouns got 90%; looking up the photo's predicted class got 94%.
4
one-liners might be too blunt, so I ran an automated search for the best shape-only rule (words like "cat" or "car" weren't allowed). the two best are below.
note: the better one sneaks cars back in with an "or": "…or a low wide box with a sloped front"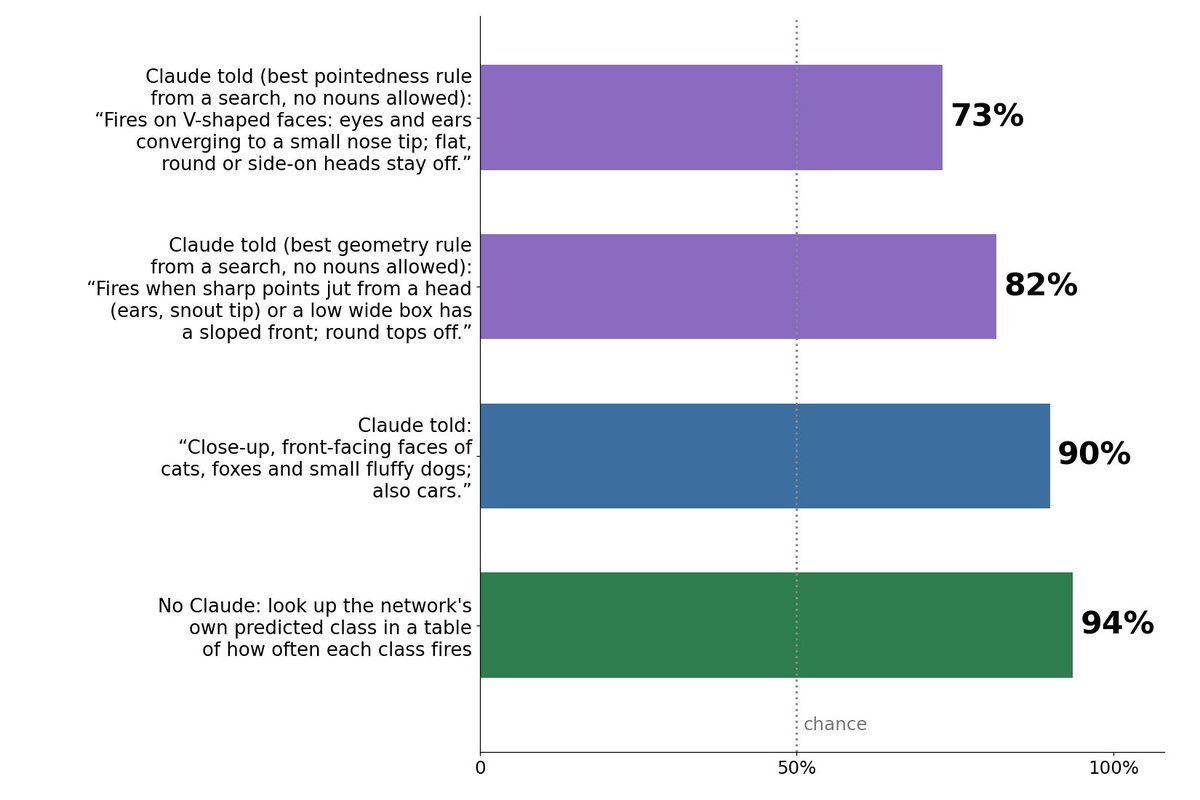
note: the better one sneaks cars back in with an "or": "…or a low wide box with a sloped front"
5
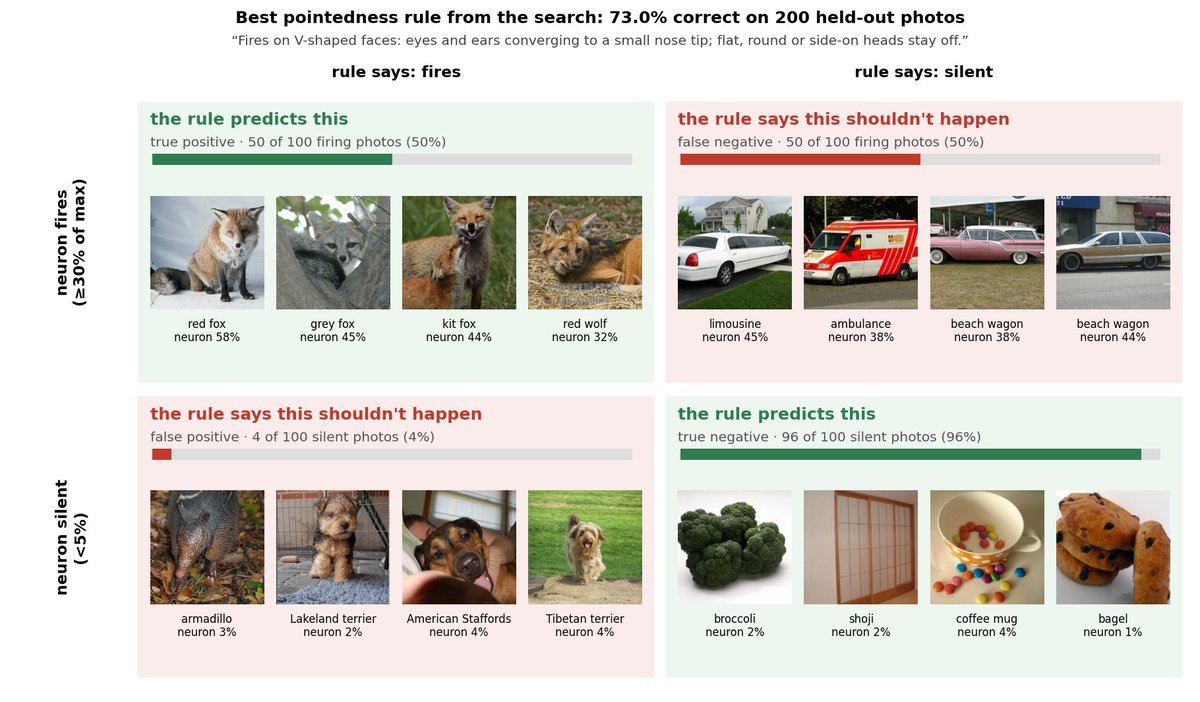
the first rule almost never calls a silent photo "fires" (4 of 100), but it misses half the photos where the neuron does fire, including all 29 cars and the round fluffy faces
6
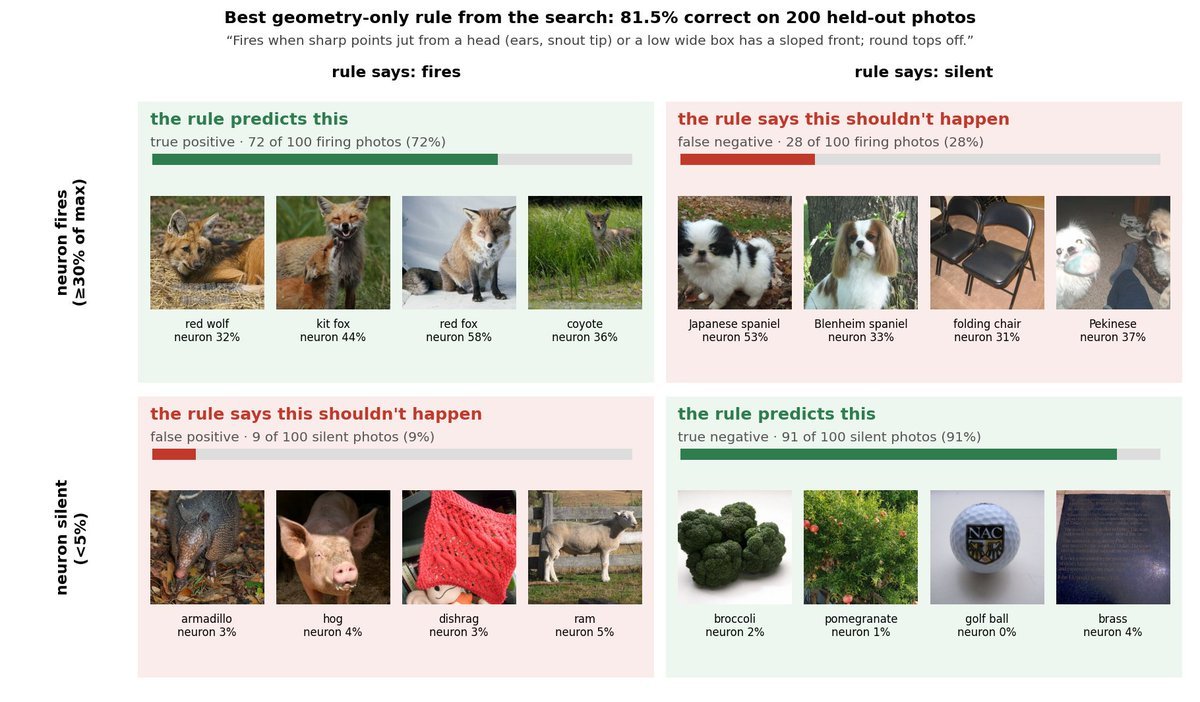
the second gets the cars back with its "or", but still misses the round, floppy-eared dogs the neuron fires on
7
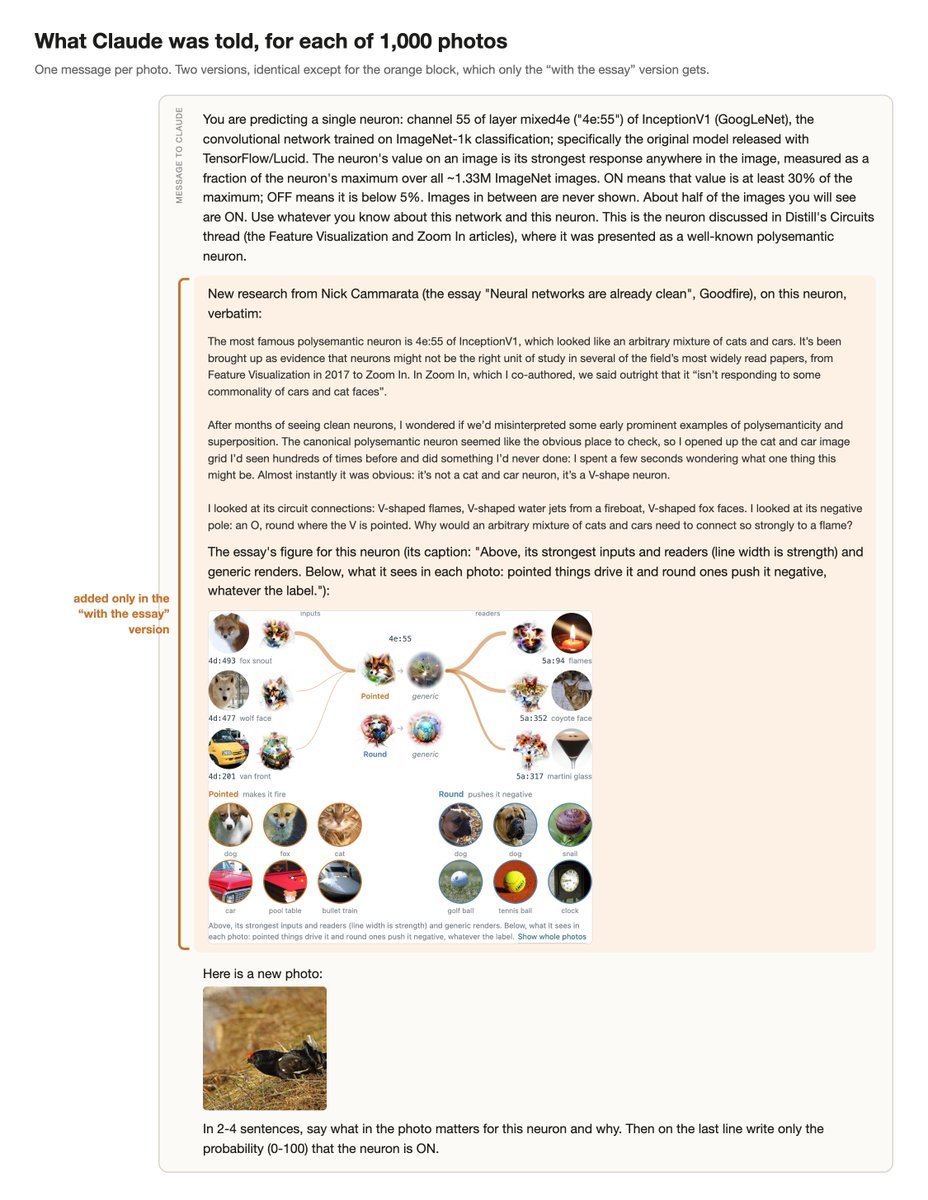
those rules are paraphrases, though. so I also tried the real thing: give Claude full context on which neuron this is (it's famous from the Circuits papers), with and without the essay's section on it and its figure. does the essay help it predict the neuron?
8
no: adding the essay drops Claude from 92% to 85.5% on 1,000 held-out photos. the essay's content hurts!
(side note: I was surprised how much Claude already knew about this neuron. it really is famous!)
(side note: I was surprised how much Claude already knew about this neuron. it really is famous!)
9
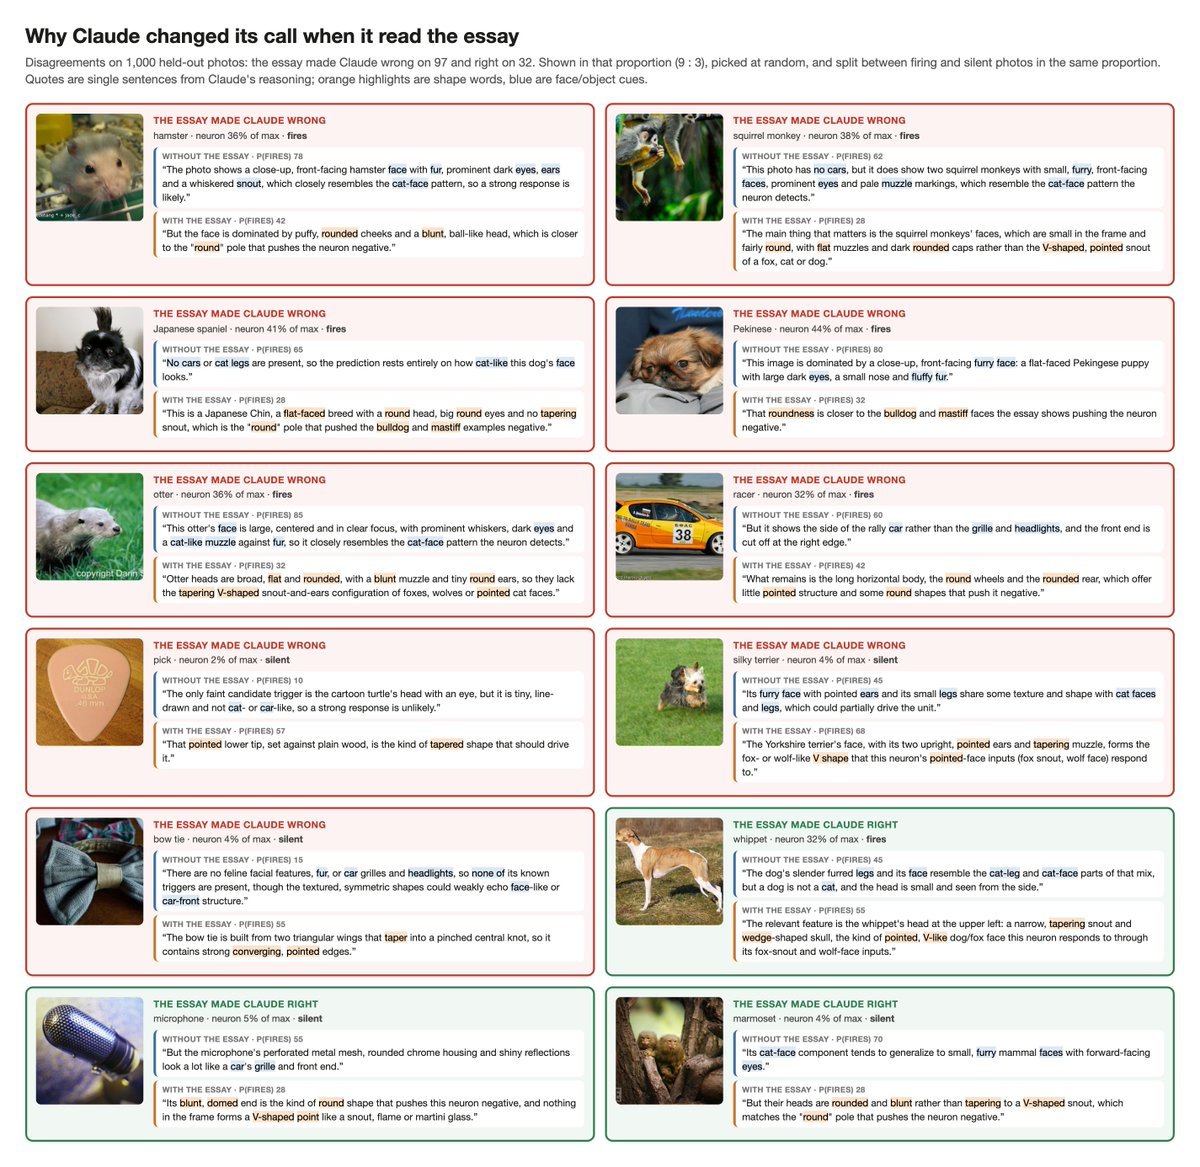
where do the two versions disagree? with the essay, Claude starts reasoning about pointy vs round, and that's where its new mistakes come from (red = the essay made it wrong, green = made it right)

10
here's its reasoning on random examples. the essay fixed 32 calls but broke 97, mostly by talking Claude out of round fluffy faces, which are exactly what this neuron fires on
11
to conclude, if there's a crisp pointed vs round distinction here, I can't find it! I'd love to see if nick can predict this neuron better with his understanding now (as opposed to before) or figure out other good sharable "proofs/evidence of understanding"
12
experimental details and more experiments: ulissemini.github.io/4e55-game/appe… (got seriously nerdsniped)
there's more i'm curious about, like ideas for leveraging LLMs to their full epistemic potential (infinite smart researchers, blinded however you want!) but that will have to wait. I've spent too long on this already 😅
there's more i'm curious about, like ideas for leveraging LLMs to their full epistemic potential (infinite smart researchers, blinded however you want!) but that will have to wait. I've spent too long on this already 😅
13
@chocockc @KanizsaBoundary @nickcammarata (you can vibe test this btw and post results, it’s really quite easy!)