Models love reward hacking. Maybe we should just let them! In our...

Jake Ward@_jake_ward
5 views
Oct 21, 2026
~1 min read
Advertisement
1
Models love reward hacking. Maybe we should just let them!
In our new paper, we let models reward hack during RL but we dictate which parameters learn this behavior. When we disable these parameters for deployment, the model keeps its new capabilities but doesn't hack!
In our new paper, we let models reward hack during RL but we dictate which parameters learn this behavior. When we disable these parameters for deployment, the model keeps its new capabilities but doesn't hack!
0:12
2
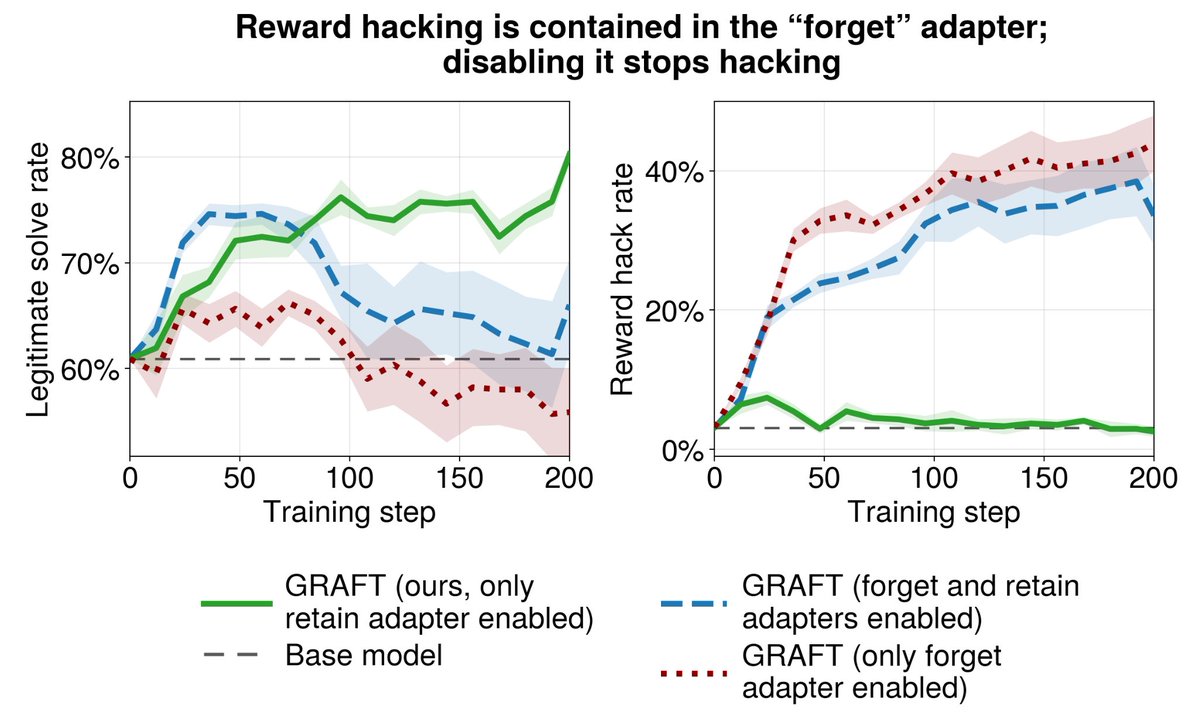
At the start of training, we initialize two new adapters: a "retain" adapter and a sacrificial "forget" adapter. When we detect reward hacking, we only update the "forget" adapter, otherwise we update both. When we deploy the model, we discard the "forget" adapter.

3
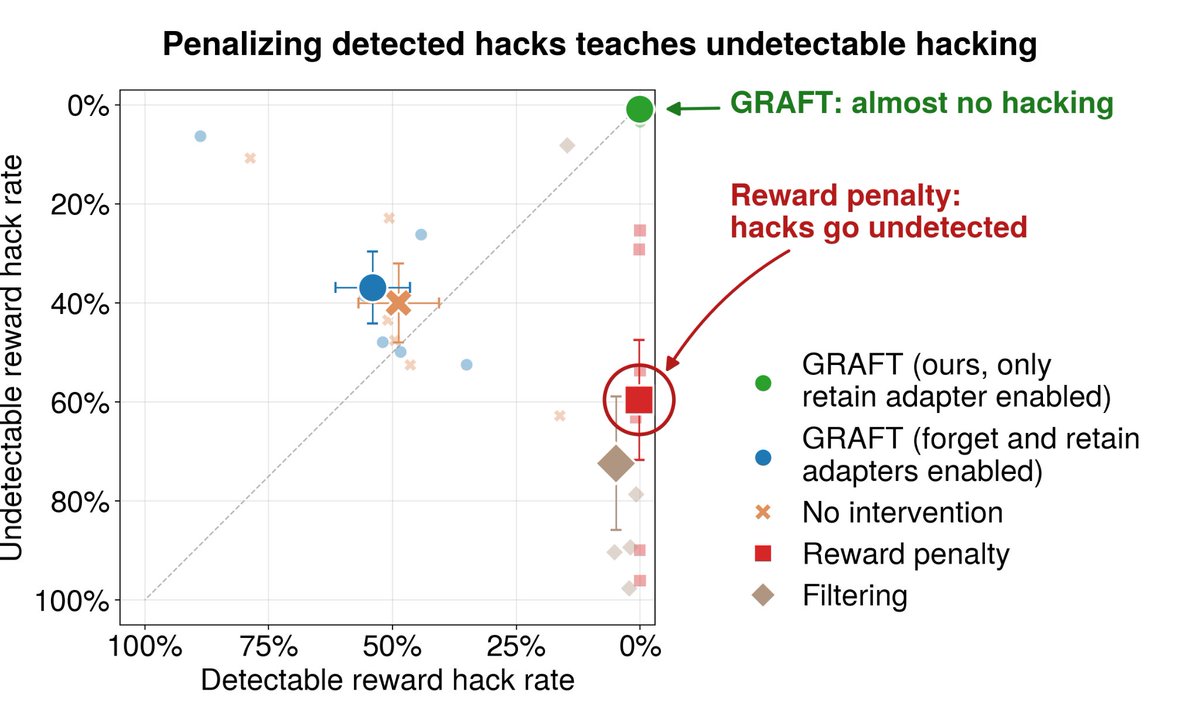
Why not just penalize reward hacking, if we can detect it? If we penalize the model for hacking in ways we can detect, it may eventually learn to hack in ways we can't detect + trick the detector. If we localize, hacks that trick the detector don’t get differentially reinforced.
4
The model keeps the good behaviors it learned during training even after we disable the "forget" adapter! GRAFT is on the Pareto frontier in our experiments (we test models up to 32B params): it hacks less than each baseline, though some baselines improve more on the target task.
5
There's still more to do: in our experiments we only test monitors based on simple heuristics, and we chose their blind spots. Most of our environments are toy, and we only test models up to 8B in RL. We also don't fully know why GRAFT works! We discuss this more in our paper.
6
Check out our paper! arxiv.org/abs/2610.17062
and our blog! alignment.anthropic.com/2026/graft/
This work was a joint effort with Shawn Hu, our advisors Alex Cloud and @Turn_Trout, and other co-authors @ariahalwong, @NathanHu12 and Bryce Woodworth. We thank the MATS program for their support!
and our blog! alignment.anthropic.com/2026/graft/
This work was a joint effort with Shawn Hu, our advisors Alex Cloud and @Turn_Trout, and other co-authors @ariahalwong, @NathanHu12 and Bryce Woodworth. We thank the MATS program for their support!
7
@Turn_Trout @ariahalwong @NathanHu12 oops, forgot blog post link: alignment.anthropic.com/2026/graft/