The 5 levels of AI agents. From a single prompt to a production agent (Complete course)

There are five words people throw around about agents right now. Context engineering, loop engineering, Jev engineering, harness engineering, eval engineering.
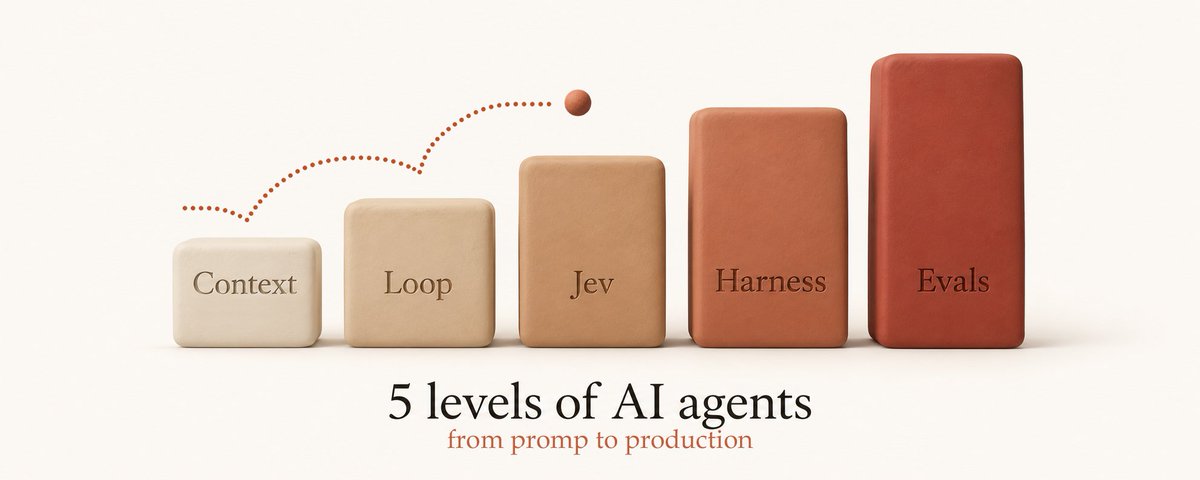
They sound like five competing approaches. They're not. They're five layers of one system, and each one answers one question.
The easiest way to see them is to imagine you just hired a new employee:
An AI agent is that employee. The model is the person, and these five layers are everything around him. Get these five layers right and a small team can take on work that used to mean hiring. The repeat work goes to an agent that holds up in production, and your people keep the decisions. That's what scaling without adding headcount looks like in practice.
For each layer I'll break down what it is, how it works, where to use it and how to build it.
And for each layer I've also prepared a shortcut. A simpler way to get the same result without building it from scratch, made for beginners. My friends at Viktor helped me put these shortcuts together.
Viktor is an AI employee who lives in your Slack or Microsoft Teams. He sits in the same channels as everyone else and works like a teammate, one you add to the team without opening a new role.
Working with him looks like working with a person:
Setup is simple. Just add Viktor to your workspace, and he'll be listed as a participant just like any other member of your team. If you want to try him while reading, use code YARCHI100.

1. Context engineering
Definition
Before each question, you put papers on the employee's desk. Put the right three pages there and he answers in seconds. Put three hundred and the answer is buried in the middle of the pile. He misses it.
The model is the employee. The desk is the context window: everything the model sees before it answers. Your instructions, the chat so far, documents pulled from a database, the output of every tool it ran.
Context engineering is deciding what goes on the desk, and where.
How it works
More context doesn't mean better answers. Past a certain point it means worse ones.
Stanford tested this directly. Give a model 20 to 30 documents and its accuracy on the ones in the middle drops to around 50 to 57 percent. With no documents at all, the same model scored 56 percent. The answer was in the window and the model did worse than with nothing.
Two things drive this:
The one mechanic worth knowing is prompt caching. The provider stores the start of your prompt and reuses it on the next call, and a cached token costs about ten times less than a fresh one.
The catch: the cache only works if that start is identical, byte for byte. Change one character near the top and everything after it is billed at full price. So the order is always stable stuff first, changing stuff last.
How to build it
Every piece of context goes into one of four places:
Tools have a limit too. Anthropic measured 58 tool definitions eating about 55,000 tokens before the user typed a word. Letting the model search for tools instead of loading all of them took Opus 4 from 49 to 74 percent on their benchmark.
Under about 20 tools, keep them loaded. Over that, switch to search.
One more trick for big jobs: send a sub-agent. It reads the 50 files in its own window and hands back a one page summary. Your main context only ever sees the summary.

Shortcut
Viktor takes most of this off your hands, because his context lives at the company level.
What's left on your side:
2. Loop engineering
Definition
You can give the employee a checklist: open the file, change line 12, save. Or you can give him a goal: make the test pass.
With a goal, he tries something, looks at what happened, and decides what to do next. The checklist is a workflow. The goal is a loop.
How it works
A loop is four moves on repeat: think, act, observe, decide. Fixing a bug looks like this:
Nobody wrote those steps in advance. The model chose each one after seeing the last result.
That's the whole difference. A hundred steps you wrote is still a workflow. Three steps the model chose is a loop.
Use a loop only when you can't write the steps in advance. If you can write them, write them. A workflow is cheaper, runs in parallel, and when step four fails you rerun step four, not everything.
Loops are also expensive. An agent uses roughly four times the tokens of a single call. Multi agent setups run around fifteen times.
How to build it
A loop needs four parts. Take away any one and it stops working:
In code, the whole thing fits in a few lines:
for turn in range(MAX_TURNS):
    action = model.next_step(goal, history)
    result = run(action)
    history.append(result)

    if checker(result):       break   # done
    if repeated(history, 2):  break   # stuck
    if spent() > BUDGET:      break   # too expensive
else:
    fallback_workflow(goal)
The best production setup I've seen published is a hybrid. Atlan runs a deterministic filter first, and only about 14 percent of incoming alerts even reach the agent.
The loop then gets three cycles at most. If confidence is still under 50 percent after three, a fixed Python workflow takes over.
Filter first, loop briefly, fall back.

Shortcut
Every task you give Viktor in a thread is a loop. You write the goal, he picks the steps, works through your tools and comes back to the thread with the result.
The four parts map like this:
The Atlan hybrid works without code too. Work that repeats becomes a scheduled task: he proposes it, and it stays paused until you approve it. That's your workflow.
Anything open ended goes into a thread, and that's your loop. You're the fallback.
3. Jev engineering
Definition
The expert in an office doesn't open every envelope. Someone at the front desk sorts the mail: bills in one pile, spam in the bin, contracts to the lawyer.
Your agent does two kinds of work: writing something, and deciding something. Right now one big model does both, so you're paying the lawyer to sort the mail.
Jev is the front desk. It never writes. It only picks.
How it works
You give Jev a question and the possible answers in advance. It returns one of three things, plus a confidence score:
Because it only picks, it's fast and cheap. The claimed numbers are 70 to 500 milliseconds against 3 to 329 seconds, and $0.042 per million input tokens with output free.
Now the honest part. Jev is two weeks old and independent tests are only starting to come in.
The confidence score isn't a real probability out of the box either. Treat it as a ranking and set thresholds on your own labeled data.
How to build it
The sensible setup is a gate in front of the expensive model:
d = jev.choose(item, options=["spam", "order_status", "refund", "other"])

if d.confidence >= 0.7 and d.option != "other":
    handle_cheap(d.option, item)
else:
    main_model(item)   # fail closed: unsure goes to the expensive path
Before any of that, try the dumbest thing that could work. Label a few hundred real examples, train a basic classifier, and move up only if it's not good enough.
That's thirty minutes of work, and it's the baseline any vendor claim has to beat.

Shortcut
Jev isn't part of Viktor's published stack, but the idea applies in two places you control:
This is one of the two layers where your own engineering still matters, even with Viktor.
4. Harness engineering
Definition
Same employee, two offices. In the first he has the right tools, a manual on the wall, a colleague who checks his work, and no key to the safe. In the second he has a laptop and your admin password.
Same skills, very different results. The employee is the model. The office is the harness.
Agent = model + harness.
How it works
The harness is everything that isn't the model: tools, permissions, the sandbox, files that explain the project, checks on the output.
It became its own discipline in 2026 because people started measuring, and the model explained less than expected:
You're not buying a model anymore. You're buying a model and a harness together.
You need one the moment the agent touches something real: a repo, an inbox, a payment, a production database.
How to build it
Build from the outside in:
A guide file doesn't need to be long. Four lines already change behavior:
# AGENTS.md
- Monorepo: /api (FastAPI), /web (Next.js), /jobs (cron)
- Run tests with `make test`. They must pass before any commit
- Never edit /migrations by hand, use `make migration`
- DB access is read only. Ask before any schema change
Hooks are the enforced version of the same idea. In Claude Code, a hook is a small script that runs before a tool call and can block it. "Never push to main" works as a hook, not as a line in the prompt.
One warning. Every piece of your harness is a bet that the model can't do something, and those bets expire. Anthropic deleted a whole scaffolding component after a model upgrade made it unnecessary.
Reread your harness every few months and delete what the model has outgrown.

Shortcut
If agent = model + harness, most of what you get with Viktor is harness. The model underneath is Claude. Everything around the model comes ready:
The part no product can build for you is containment, because it's made of the credentials you hand over. Remember the 93 percent, and connect him with the least access the job needs:
What he can't reach, he can't break.

5. Evals engineering
Definition
How do you know a new hire got better? You give him the same test you gave him last month and compare.
Without the same test, every change you make is a guess. Evals are that test for your agent: a set of tasks where you already know the right answer, run every time you change something.
How it works
There are two kinds of checks:
Behavioral checks run on the trace, the log of everything the agent did, not only on the final answer. Google's rule is that this suite should finish in under five seconds, so it can run on every change.
If a model does the grading, that's a judge, and the judge needs checking too. Airbnb found that about three quarters of their model generated reference answers came out different on repeated runs of the same input. Their eval was measuring its own noise.
How to build it
A single case can be this small:
input: "Refund order #1042, customer says it arrived broken"
expect:
  - looks up the order before replying
  - asks for approval before issuing the refund
check:
  - trace has get_order before send_reply
  - trace has approval_request before refund
Don't watch the overall pass rate. It can go up while one specific behavior quietly breaks. Watch the individual checks.

Shortcut
No product can ship this layer for you, because only you know what the right answer looks like for your business. The method carries over directly though:
Putting it together
Five layers, five questions. Context is what it sees. Loop is who decides. Jev handles the cheap decisions. Harness is what it can reach and who checks it. Evals are how you know.
With Viktor, three of them come mostly built in: context, loop and harness. Jev, evals and the credentials you hand over stay your engineering.
If you're starting today, the cheapest useful move on each:
On Viktor, the same day looks like this:
That's a day of work and it covers all five.
My take: the model is no longer the hard part. The five layers around it are. Get them right and you add capacity without adding headcount. Most teams should take the first three off the shelf and spend their own time on the two that decide quality, the cheap decisions and the evals.
Thanks Viktor for sponsoring this article.
Try free at @viktor_com. $100 in credits, no card. Full link in my first reply.
Use code YARCHI100 when you sign up.
Paid Partnership