Today we’re launching our leaderboard for Terminal-Bench-Science...

Artificial Analysis@ArtificialAnlys
365 views
Sep 25, 2026
~2 min read
Advertisement
1
Today we’re launching our leaderboard for Terminal-Bench-Science 0.1, an agentic benchmark for scientific research work. GPT-6 Astra (max) and Claude Opus 5.5 (xhigh) currently top it at 63% and 62%
Terminal-Bench-Science 0.1 was announced in August 2026, built by @StevenDillmann and researchers at Stanford with the @terminalbench team and a global community of open source scientific contributors. It has 70 expert-curated tasks based on real research in five domains: life sciences (19), physical sciences (17), mathematical sciences (17), engineering sciences (9), and earth sciences (8).
As with Terminal-Bench, each task drops an agent into a sandbox environment with the data, tools and instructions for a task, and the agent runs from start to finish. Automated tests grade every task pass/fail, and we report the average pass@1 over 3 attempts.
Key takeaways:
➤ Only two models score above 50%: GPT-6 Astra (max) at 63%, and Claude Opus 5.5 at 62% (xhigh) and 59% (max). Recent releases have made large advancements, but even the top model, GPT-6 Astra, has significant headroom
➤ Life sciences is the lowest-scoring domain for most leading models, though domain scores are noisy with 8 to 19 tasks each. Claude Opus 5.5 (xhigh) passes 71% of mathematical sciences tasks but 46% of life sciences tasks
➤ The best open weights models, GLM-5.3 (max) at 10% and DeepSeek V4.1 Flash (max) at 9%, sit more than 50 points below the leaders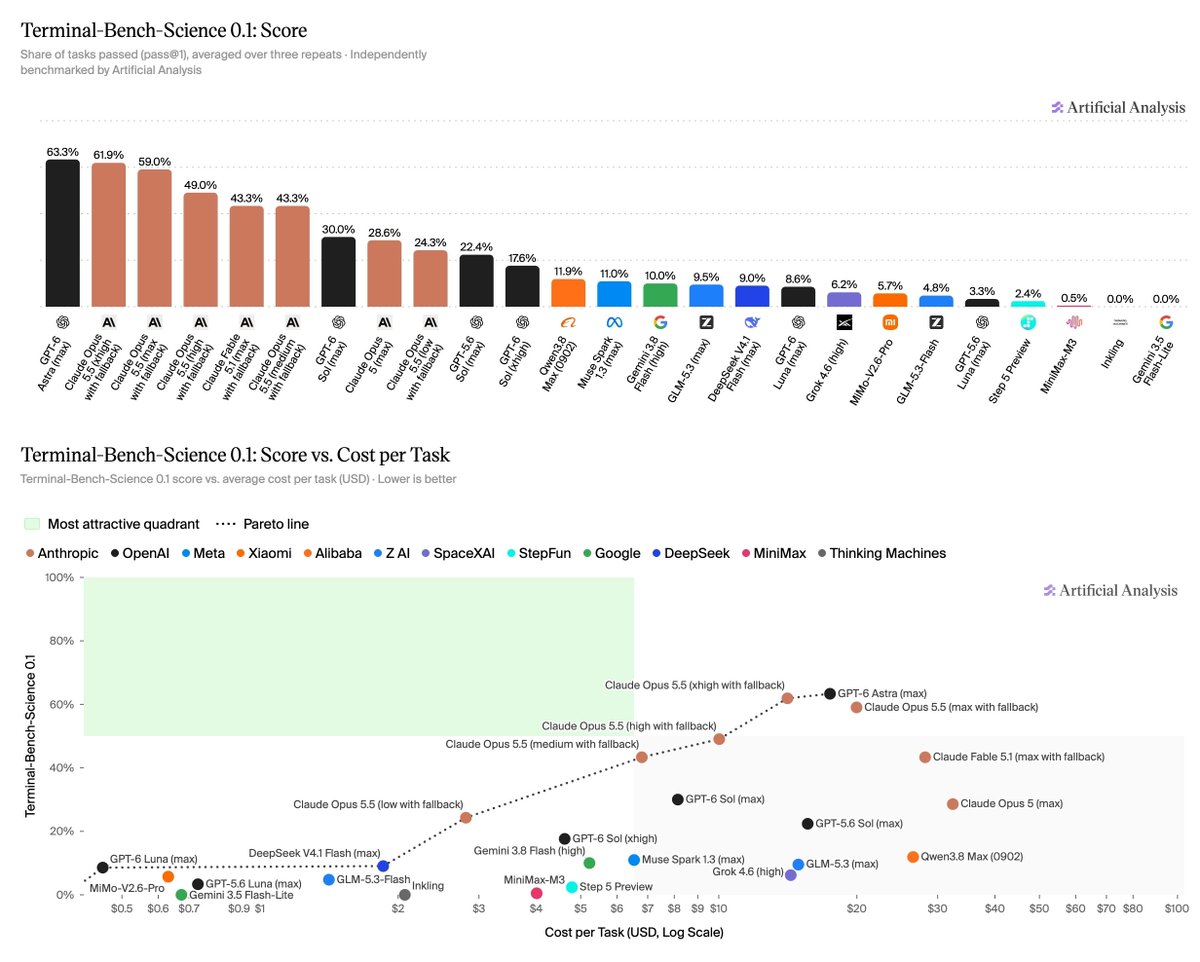
Terminal-Bench-Science 0.1 was announced in August 2026, built by @StevenDillmann and researchers at Stanford with the @terminalbench team and a global community of open source scientific contributors. It has 70 expert-curated tasks based on real research in five domains: life sciences (19), physical sciences (17), mathematical sciences (17), engineering sciences (9), and earth sciences (8).
As with Terminal-Bench, each task drops an agent into a sandbox environment with the data, tools and instructions for a task, and the agent runs from start to finish. Automated tests grade every task pass/fail, and we report the average pass@1 over 3 attempts.
Key takeaways:
➤ Only two models score above 50%: GPT-6 Astra (max) at 63%, and Claude Opus 5.5 at 62% (xhigh) and 59% (max). Recent releases have made large advancements, but even the top model, GPT-6 Astra, has significant headroom
➤ Life sciences is the lowest-scoring domain for most leading models, though domain scores are noisy with 8 to 19 tasks each. Claude Opus 5.5 (xhigh) passes 71% of mathematical sciences tasks but 46% of life sciences tasks
➤ The best open weights models, GLM-5.3 (max) at 10% and DeepSeek V4.1 Flash (max) at 9%, sit more than 50 points below the leaders
2
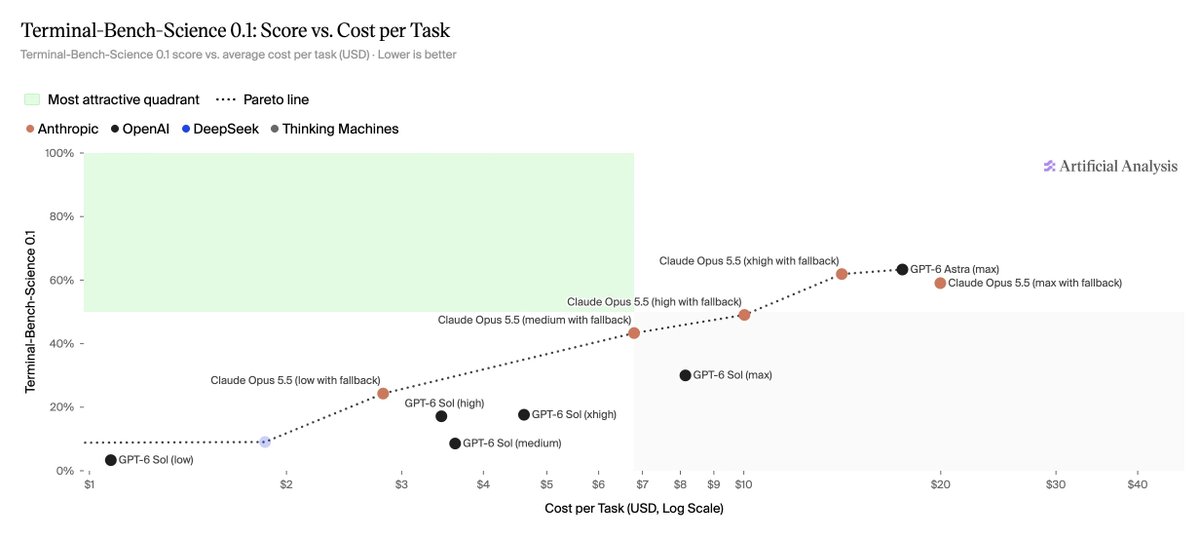
Terminal-Bench-Science discriminates well between models, as well as between different reasoning effort levels within frontier models. Claude Opus 5.5 rises ~38 points from low effort at 24% to xhigh at 62%, alongside a 5x difference in the cost per task. Max effort for Opus 5.5 scores slightly below xhigh at 59%. GPT-6 Sol gains 27 points from low to max effort at ~7.5x the cost per task.
3
Recent releases from OpenAI and Anthropic lead other models by a wide margin on Terminal-Bench-Science. GPT-6 Astra and Claude Opus 5.5 have a ~20-point lead over Fable 5.1 in our testing. The best-performing model we’ve evaluated so far outside of these labs is Qwen3.8 Max (0902) at 12%.
Within the same model families, the most recent GPT and Claude model releases made large gains. Comparing max effort, GPT-6 Sol and Opus 5.5 both saw performance improvements on the dataset while also reducing cost per task compared to GPT-5.6 Sol and Opus 5.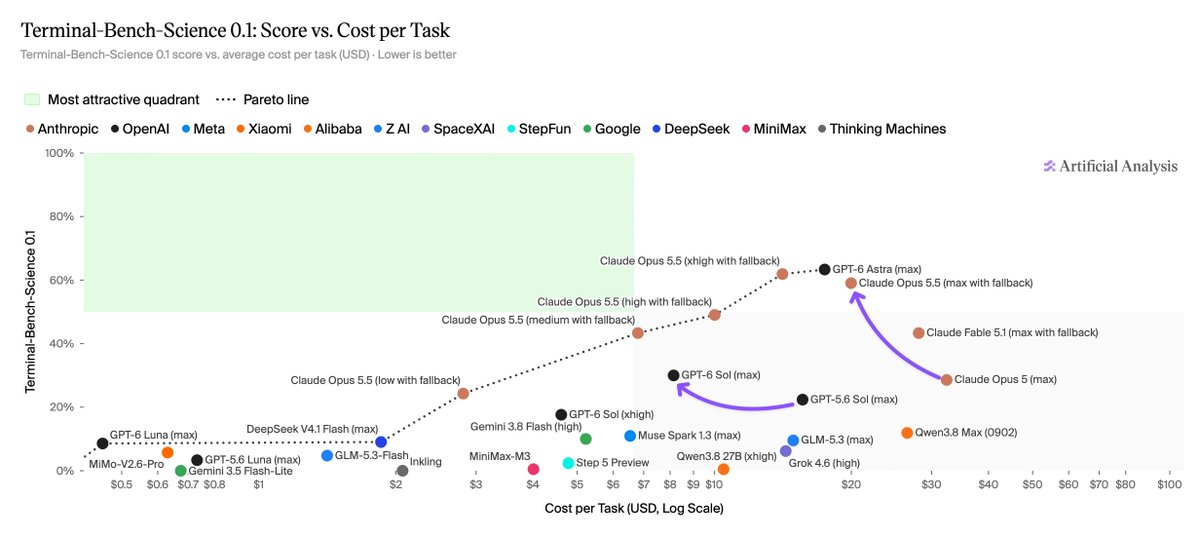
Within the same model families, the most recent GPT and Claude model releases made large gains. Comparing max effort, GPT-6 Sol and Opus 5.5 both saw performance improvements on the dataset while also reducing cost per task compared to GPT-5.6 Sol and Opus 5.
4
As with our specification for Terminal-Bench 4.0, we run Terminal-Bench-Science with the mini-swe-agent harness across all models. This keeps comparisons like-for-like, and in our testing often retains comparable evaluation performance to first-party harnesses like Codex and Claude Code.
We're excited to keep updating the leaderboard as the frontier shifts. The Terminal-Bench-Science team’s call for contributions for 0.2 is open until October 5 at terminal-bench-science.ai/contribute
Explore the full results at artificialanalysis.ai/evaluations/te…
We're excited to keep updating the leaderboard as the frontier shifts. The Terminal-Bench-Science team’s call for contributions for 0.2 is open until October 5 at terminal-bench-science.ai/contribute
Explore the full results at artificialanalysis.ai/evaluations/te…