Can LLMs self-evolve into general-purpose tool-calling agents...

Emre Can Acikgoz@emrecanacikgoz
23 views
Mar 04, 2026
~3 min read
Advertisement
1
Can LLMs self-evolve into general-purpose tool-calling agents without any external data?
Yes. Introducing "Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data"! ♾️
Initialized from the same LLM, Tool-R0 co-evolves a Generator and Solver through self-play RL; training general-purpose tool-calling agents entirely from scratch with zero data.
(1/n)
Yes. Introducing "Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data"! ♾️
Initialized from the same LLM, Tool-R0 co-evolves a Generator and Solver through self-play RL; training general-purpose tool-calling agents entirely from scratch with zero data.
(1/n)
2
Problem: Post-training for tool-calling agents depends on carefully constructed task–solution pairs and substantial human supervision, which creates a fundamental obstacle to open-ended self-evolution toward ideal superintelligent systems.
Unlike prior self-play works in LLMs that focus on abstract reasoning or single-tool QA, Tool-R0 targets general-purpose tool-calling across diverse domains with arbitrary API schemas.
(2/n)
Unlike prior self-play works in LLMs that focus on abstract reasoning or single-tool QA, Tool-R0 targets general-purpose tool-calling across diverse domains with arbitrary API schemas.
(2/n)
3
How does Tool-R0 work?
We initialize one base LLM into two different roles, but train separately:
- Generator: Synthesizes challenging tool-calling tasks (user query, tool menu, gold calls) targeted at the Solver's competence frontier.
- Solver: Learns to solve them with structured reasoning and accurate tool calls similar to our previous work ToolRL (NeurIPS 2025, openreview.net/pdf?id=eOLdGbX…).
Together, they co-evolve through complementary reward signals by creating a iterative self-evolving cycle.
(3/n)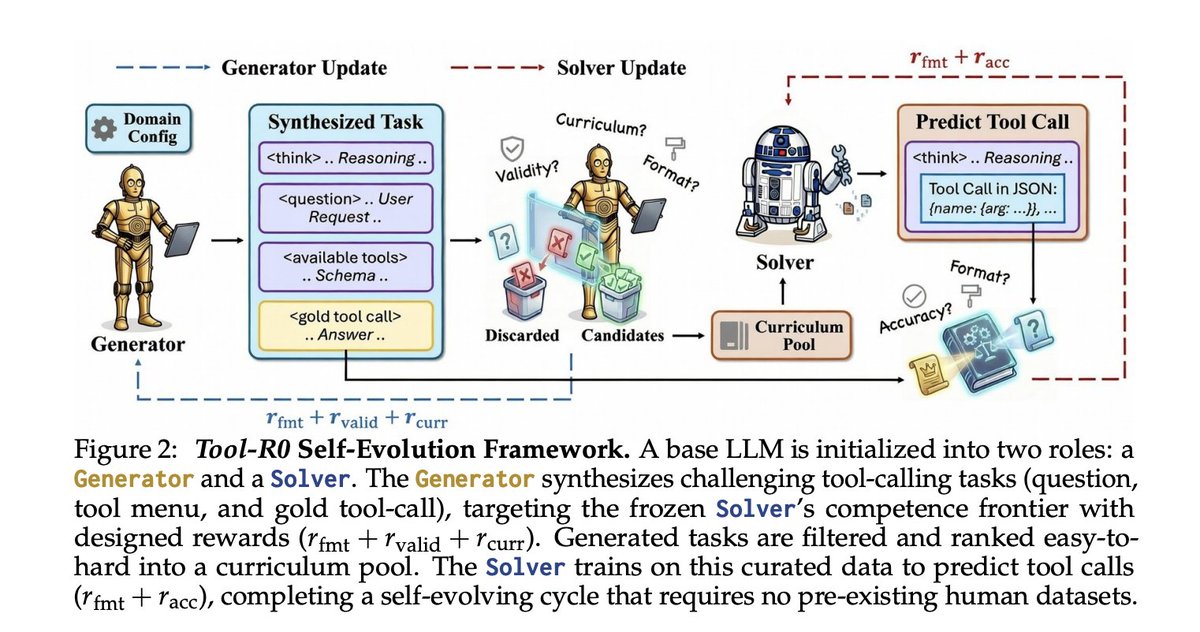
We initialize one base LLM into two different roles, but train separately:
- Generator: Synthesizes challenging tool-calling tasks (user query, tool menu, gold calls) targeted at the Solver's competence frontier.
- Solver: Learns to solve them with structured reasoning and accurate tool calls similar to our previous work ToolRL (NeurIPS 2025, openreview.net/pdf?id=eOLdGbX…).
Together, they co-evolve through complementary reward signals by creating a iterative self-evolving cycle.
(3/n)
4
The key idea for a stable learning is: don’t reward “hard” tasks but reward tasks at the competence frontier.
We design a smooth difficulty-guided band-pass reward so the Generator proposes tasks that are: (i) not trivial, (ii) not impossible, (iii) just beyond current ability. A curriculum that is “hard enough to teach and easy enough to verify”.
(4/n)
We design a smooth difficulty-guided band-pass reward so the Generator proposes tasks that are: (i) not trivial, (ii) not impossible, (iii) just beyond current ability. A curriculum that is “hard enough to teach and easy enough to verify”.
(4/n)
5
What makes this particularly promising is that: (1) despite using zero curated data, it yields almost a two-fold improvement over the base model averaged across five different tool-calling agent benchmarks. (2) It even surpasses fully supervised baselines trained on tens of thousands more expert-labeled data!
(5/n)
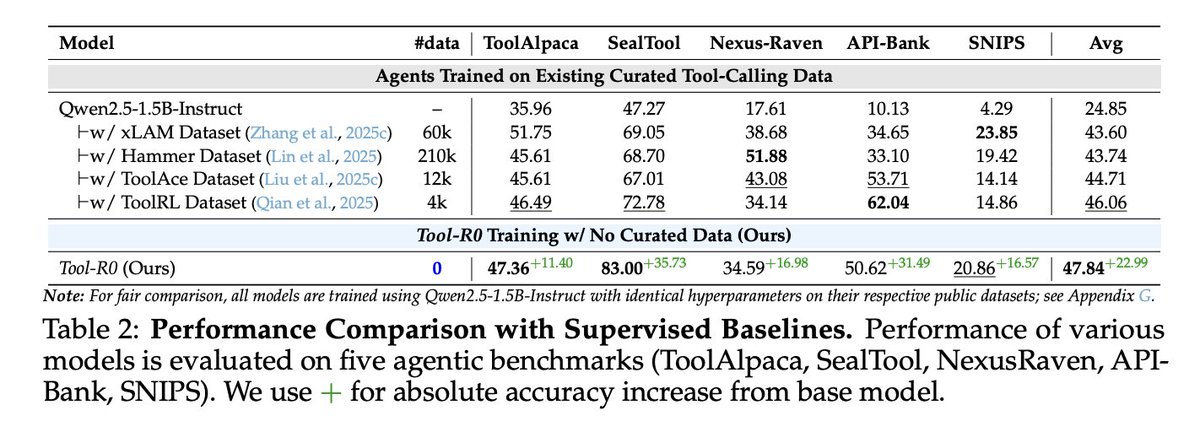
(5/n)
6
But why? We computed pairwise similarity between training corpora and test benchmarks. Curated datasets are inherently biased to specific question formats and complexity. Tool-R0's self-generated curriculum achieves the highest average similarity AND the most uniform coverage across all benchmarks, without ever seeing test data.
This suggests that models can synthesize training distributions better matched to their own weaknesses than fixed human-curated dataset.
(6/n)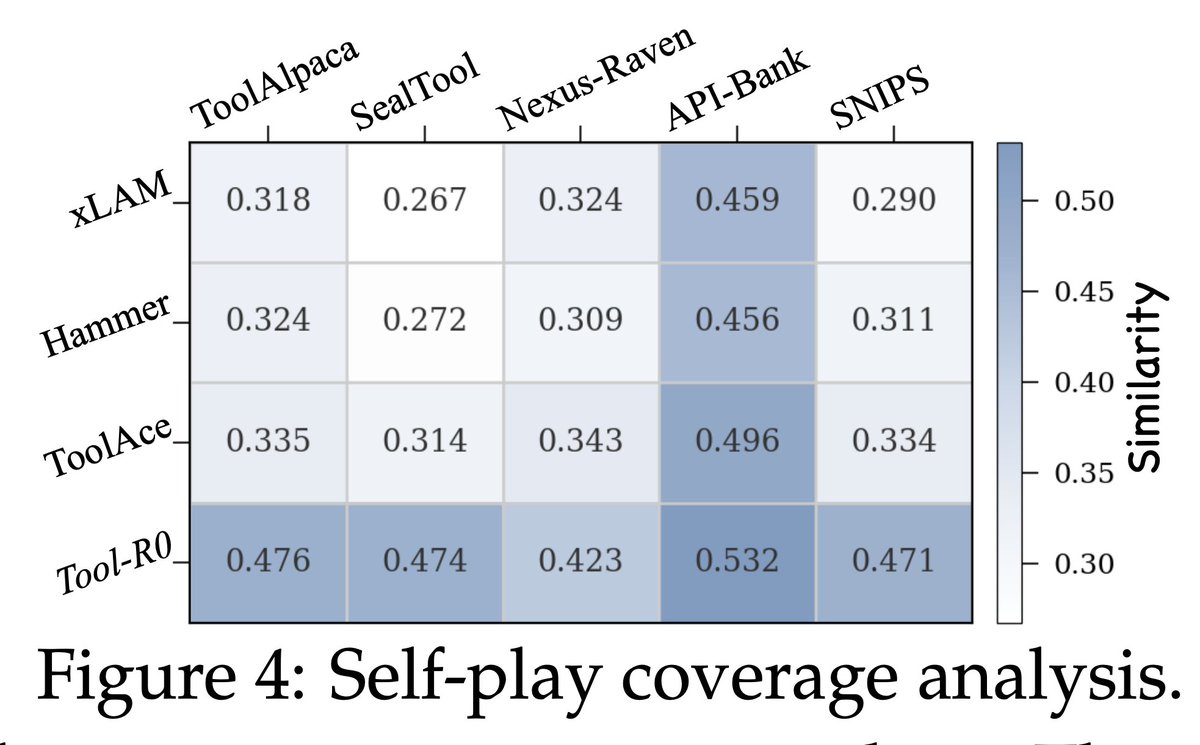
This suggests that models can synthesize training distributions better matched to their own weaknesses than fixed human-curated dataset.
(6/n)
7
Some additional key findings: (1) Role separation is essential when both roles operate over high-entropy action spaces with different reward objectives. (2) Active co-evolution with difficulty-aware rewards drives learning. (3) Smooth Gaussian difficulty rewards matter for stable learning and outperform hard cutoffs.
There are many more interesting studies regarding self-play dynamics in paper for interested readers.
(7/n)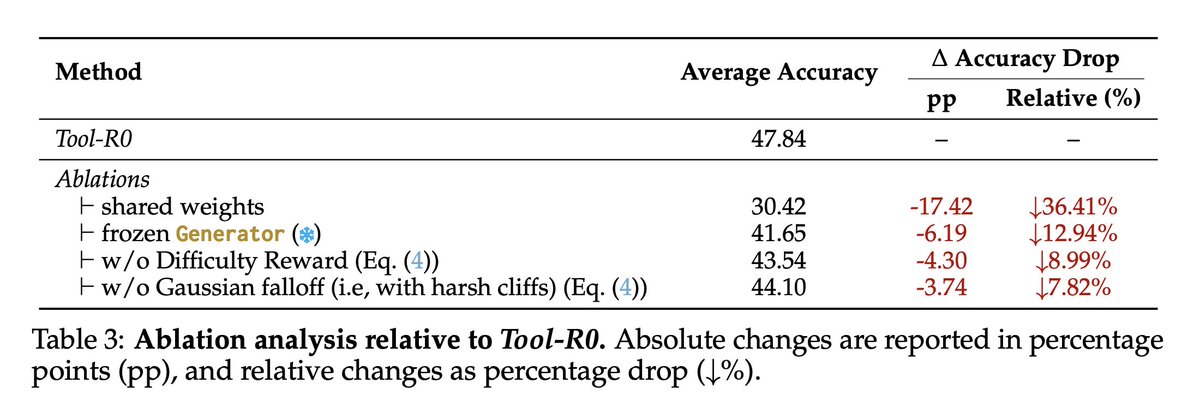
There are many more interesting studies regarding self-play dynamics in paper for interested readers.
(7/n)
8
Bonus: Similar to previous works in abstract reasoning, we also observed that Tool-R0 serves as an effective mid-training stage. Running self-play as continued pre-training builds a stronger initialization for post-training, outperforming models trained with expert human data alone.
Ref: (1) arxiv.org/pdf/2503.20783, (2) arxiv.org/pdf/2506.20512, (3) arxiv.org/pdf/2508.05004
(8/n)
Ref: (1) arxiv.org/pdf/2503.20783, (2) arxiv.org/pdf/2506.20512, (3) arxiv.org/pdf/2508.05004
(8/n)
9
Motivated by the absolute zero paradigm (@_AndrewZhao, arxiv.org/abs/2505.03335), Tool-R0 is a step toward general agentic self-play with LLMs. We strongly believe in the potential of self-play in agentic learning; it isn't just for games or abstract reasoning. By designing environments with the right verifiable signals, even LLMs with weak priors can teach themselves strong tool-use skills from no curated datasets.
We're especially excited about long-horizon human-in-the-loop co-evolution as the next frontier.
(9/n)
We're especially excited about long-horizon human-in-the-loop co-evolution as the next frontier.
(9/n)
10
Tool-R0 is part of “The Lifelong Agent Project” (lifelongagent.github.io/Project-Lifelo…), driven by one goal only: building generalizable agents that can continuously learn, align, and evolve—regardless of any environment/domain/task.
There's a long road ahead, but as we keep solving scalability bottlenecks; we'll get there, one step at a time. Feel free to send me an email if you have any questions.
(10/n)
There's a long road ahead, but as we keep solving scalability bottlenecks; we'll get there, one step at a time. Feel free to send me an email if you have any questions.
(10/n)
11
Huge thanks to incredible team effort @qiancheng1231, @jonashuebotter, @hengjinlp, @dilekhakkanitur, @tur_gokhan!
Useful Links:
📄 Paper: arxiv.org/pdf/2602.21320
🌐 Project Page: emrecanacikgoz.github.io/Tool-R0
💻 Code: github.com/emrecanacikgoz…
🤗 Models: huggingface.co/collections/em…
📈 Logs: api.wandb.ai/links/acikgoz2…
♾️ Project Lifelong Agent: lifelongagent.github.io/Project-Lifelo…
Keywords: #NLP #LLMs #Agents #LLMAgents #SelfEvolvingLLMs #Tools
(n/n)
Useful Links:
📄 Paper: arxiv.org/pdf/2602.21320
🌐 Project Page: emrecanacikgoz.github.io/Tool-R0
💻 Code: github.com/emrecanacikgoz…
🤗 Models: huggingface.co/collections/em…
📈 Logs: api.wandb.ai/links/acikgoz2…
♾️ Project Lifelong Agent: lifelongagent.github.io/Project-Lifelo…
Keywords: #NLP #LLMs #Agents #LLMAgents #SelfEvolvingLLMs #Tools
(n/n)