(1/N) Pencil Puzzle Bench is out! 51 LLMs tested on pencil puzzles...

Justin Waugh@JustinWaugh
48 views
Mar 12, 2026
~1 min read
Advertisement
1
(1/N) Pencil Puzzle Bench is out!
51 LLMs tested on pencil puzzles (multi-step, logical reasoning, verifiable at each step)
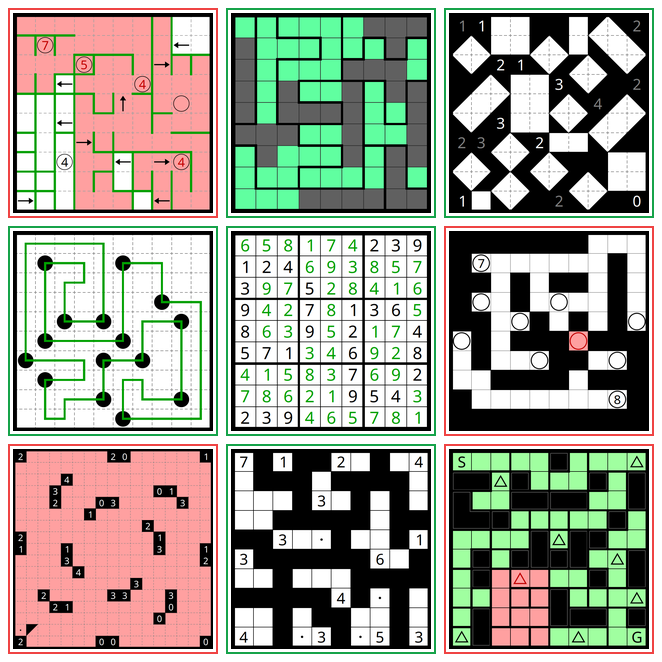
Dataset: 62k unique puzzles, 94 types.
Evaluation: covers 300 puzzles across 20 types
Best score: GPT 5.2@xhigh 56%, half the puzzles are still unsolved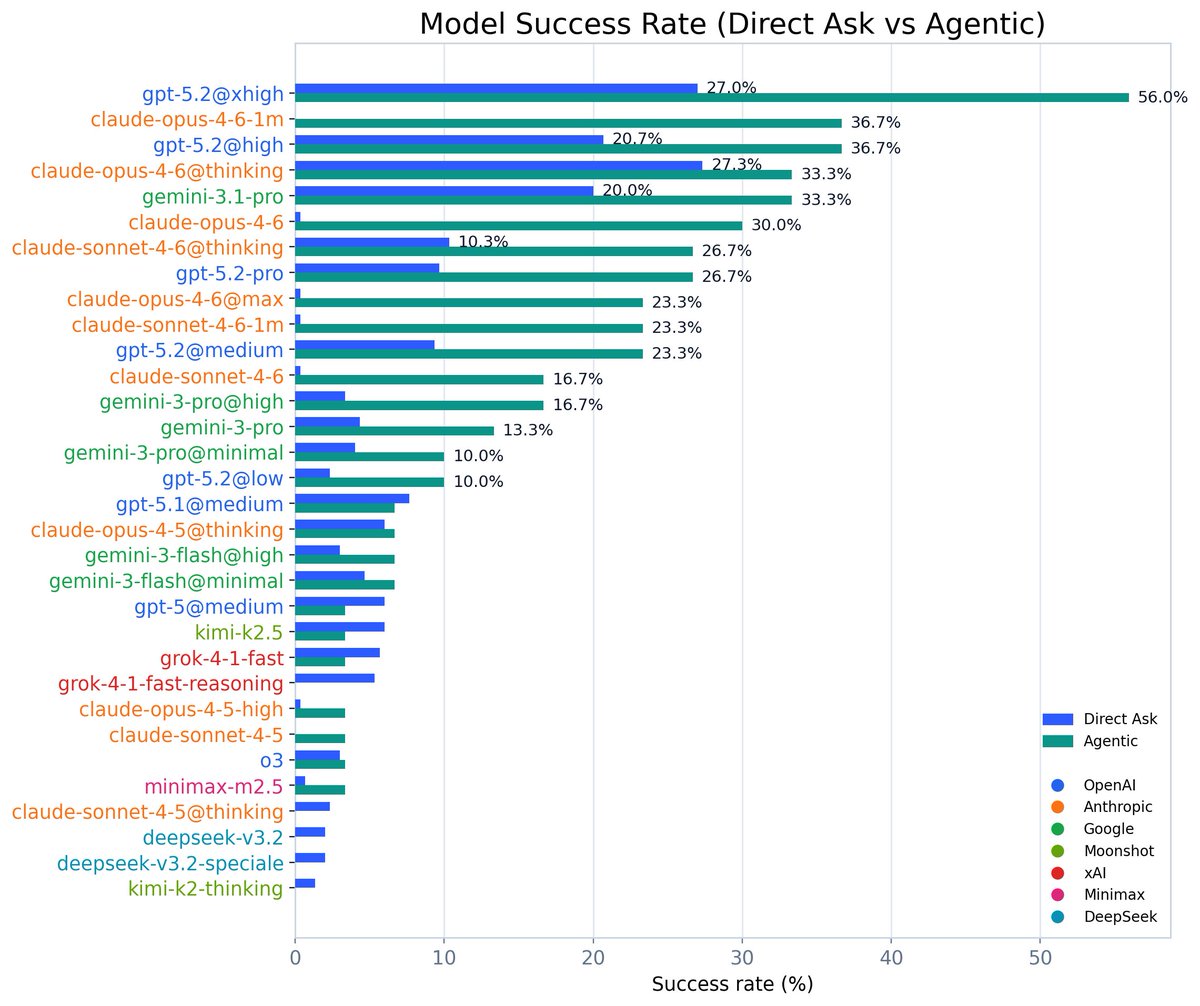
51 LLMs tested on pencil puzzles (multi-step, logical reasoning, verifiable at each step)
Dataset: 62k unique puzzles, 94 types.
Evaluation: covers 300 puzzles across 20 types
Best score: GPT 5.2@xhigh 56%, half the puzzles are still unsolved
2
(2/N) Play every puzzle yourself: ppbench.com
Replay AI solve's step-by-step, and see how you compare to frontier models solving these puzzles.
Here's Claude Sonnet 4.5 on a LITS puzzle: 214 tool calls, 62 resets before cracking it.
Replay AI solve's step-by-step, and see how you compare to frontier models solving these puzzles.
Here's Claude Sonnet 4.5 on a LITS puzzle: 214 tool calls, 62 resets before cracking it.
0:56
3
(3/N) Two eval modes: single-shot (json output with solution) and agentic (iterate with verifier feedback).
Reasoning depth and agentic iteration are distinct axes of scaling.
Challenging enough that even the provider infra fails (>60 minute thinking decodes)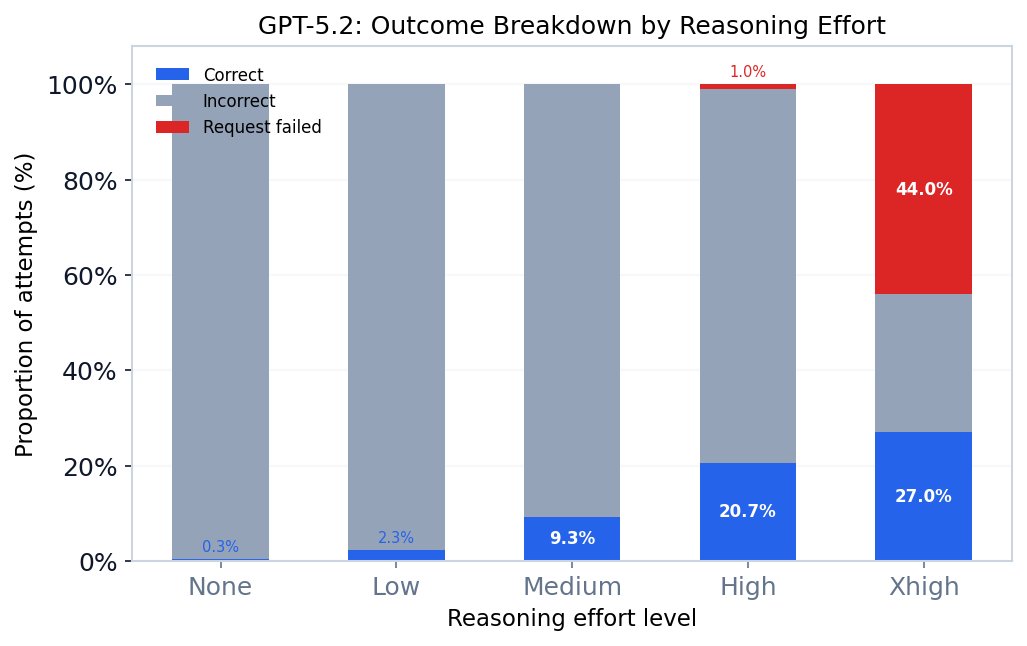
Reasoning depth and agentic iteration are distinct axes of scaling.
Challenging enough that even the provider infra fails (>60 minute thinking decodes)
4
(4/N) These are hard puzzles (can take hours for humans to solve)
Agentic attempts took a median of 29 turns over 17 minutes, and the longest took ~1,200 turns and 14.3 hours.
Cost per success varries by 67,000x across models.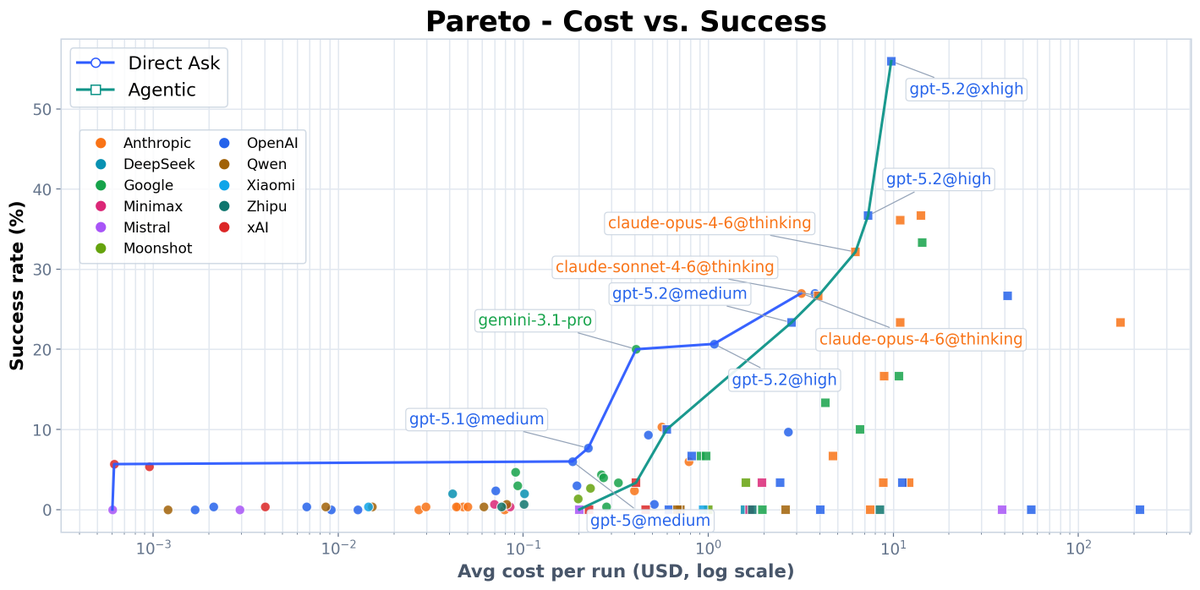
Agentic attempts took a median of 29 turns over 17 minutes, and the longest took ~1,200 turns and 14.3 hours.
Cost per success varries by 67,000x across models.
5
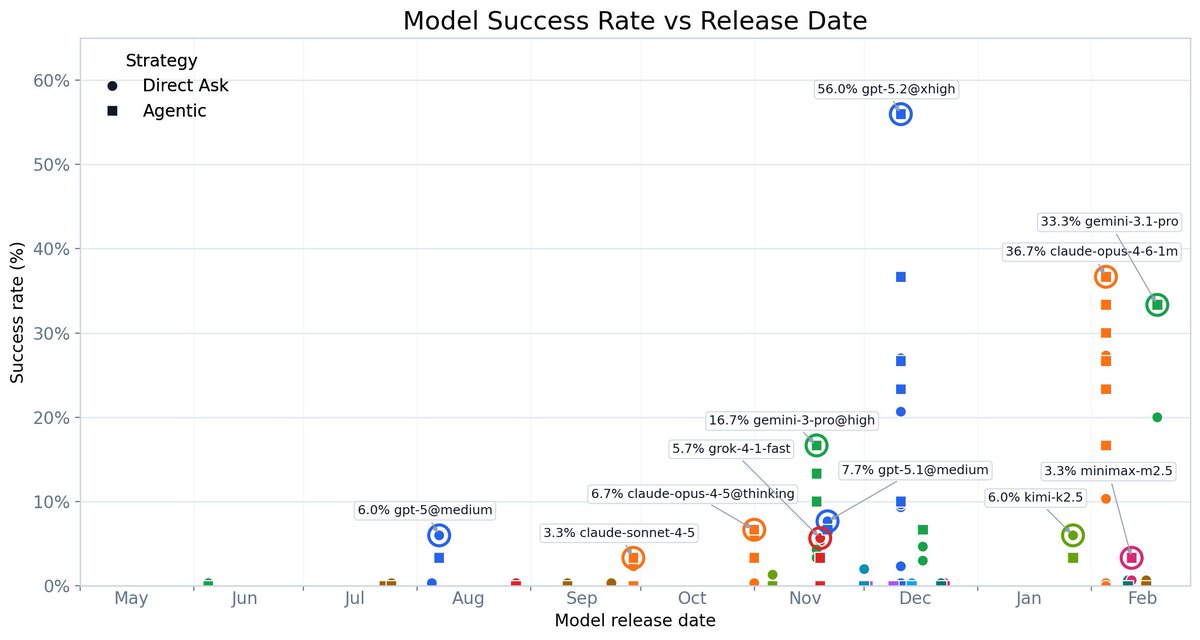
(5/N) This benchmark captures the recent surge in capability in November / December 2025, where very rapidly we got 3 new models that crossed 10% (gemini-3-pro, gpt-5.2 and claude-4.6)
6
(6/N) Best model per provider: the gap between US closed-source labs and open-weight alternatives is stark.
Top 3 (OpenAI, Anthropic, Google) all clear 33%. Best Chinese open-weight model: 6%.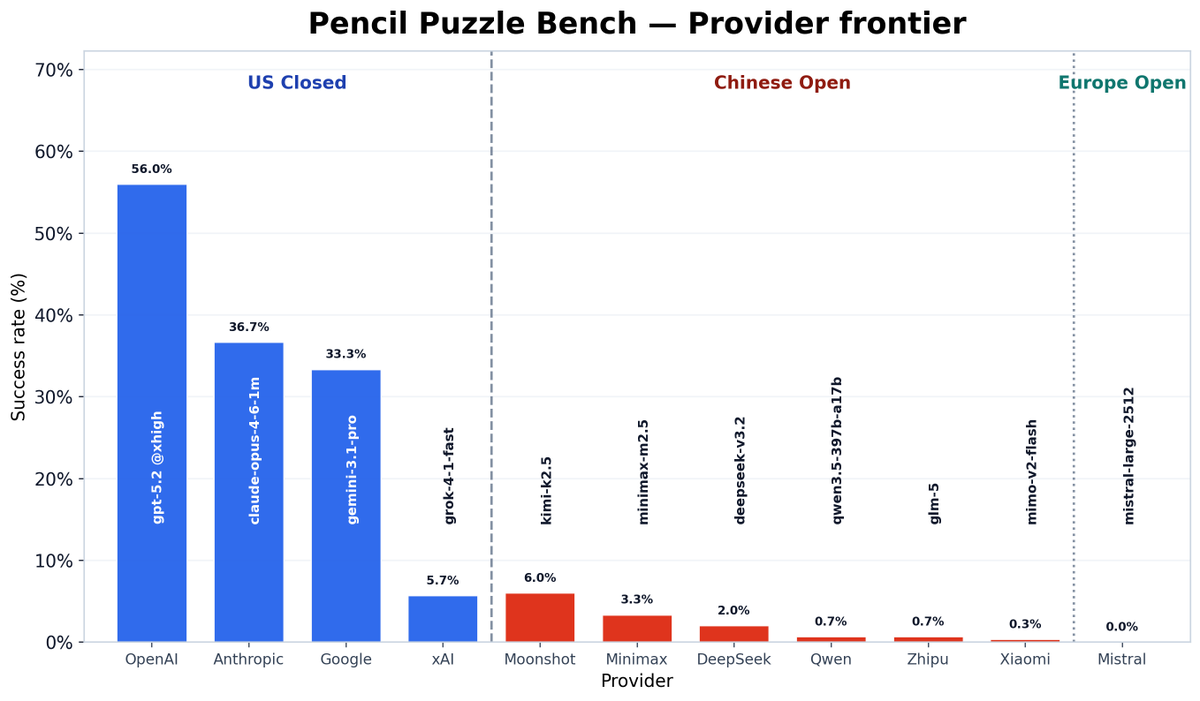
Top 3 (OpenAI, Anthropic, Google) all clear 33%. Best Chinese open-weight model: 6%.
7
Paper: arxiv.org/pdf/2603.02119
Dataset: huggingface.co/datasets/bluec…
Blog: approximatelabs.com/pencil_puzzle_…
Play puzzles yourself + see the leaderboard: ppbench.com
Dataset: huggingface.co/datasets/bluec…
Blog: approximatelabs.com/pencil_puzzle_…
Play puzzles yourself + see the leaderboard: ppbench.com