Holy shit... Google DeepMind just exposed why everyone's been doing...

Jainam Parmar@aiwithjainam
35 views
Jan 01, 2026
~2 min read
Advertisement
1
Holy shit... Google DeepMind just exposed why everyone's been doing AI reasoning wrong.
The AlphaGo team doesn't use chain-of-thought. They use parallel verification loops.
And it's destroying every "advanced reasoning" technique you've heard about.
Here's what they discovered ↓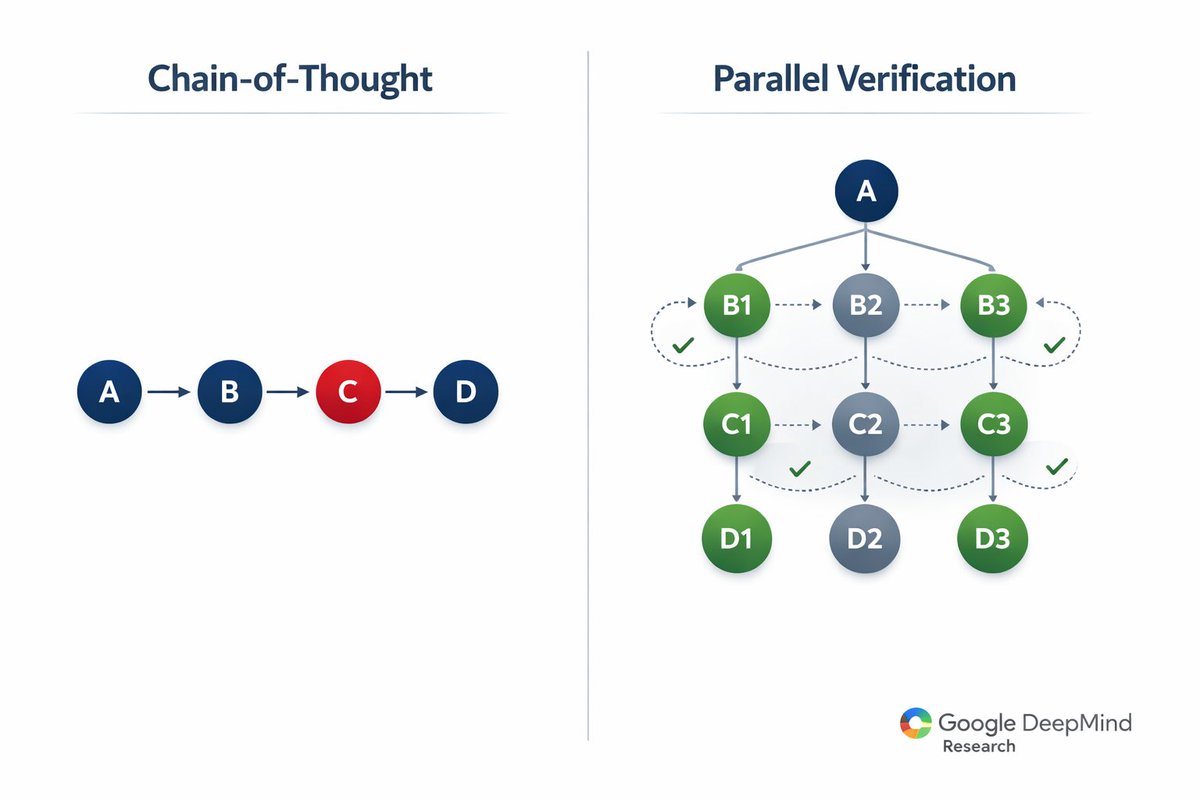
The AlphaGo team doesn't use chain-of-thought. They use parallel verification loops.
And it's destroying every "advanced reasoning" technique you've heard about.
Here's what they discovered ↓
2
Why Chain-of-Thought sucks.
Current AI reasoning is linear. Think step 1 → step 2 → step 3.
But that's not how expert problem-solvers think.
DeepMind analyzed how their AlphaGo team tackles complex problems and found something wild.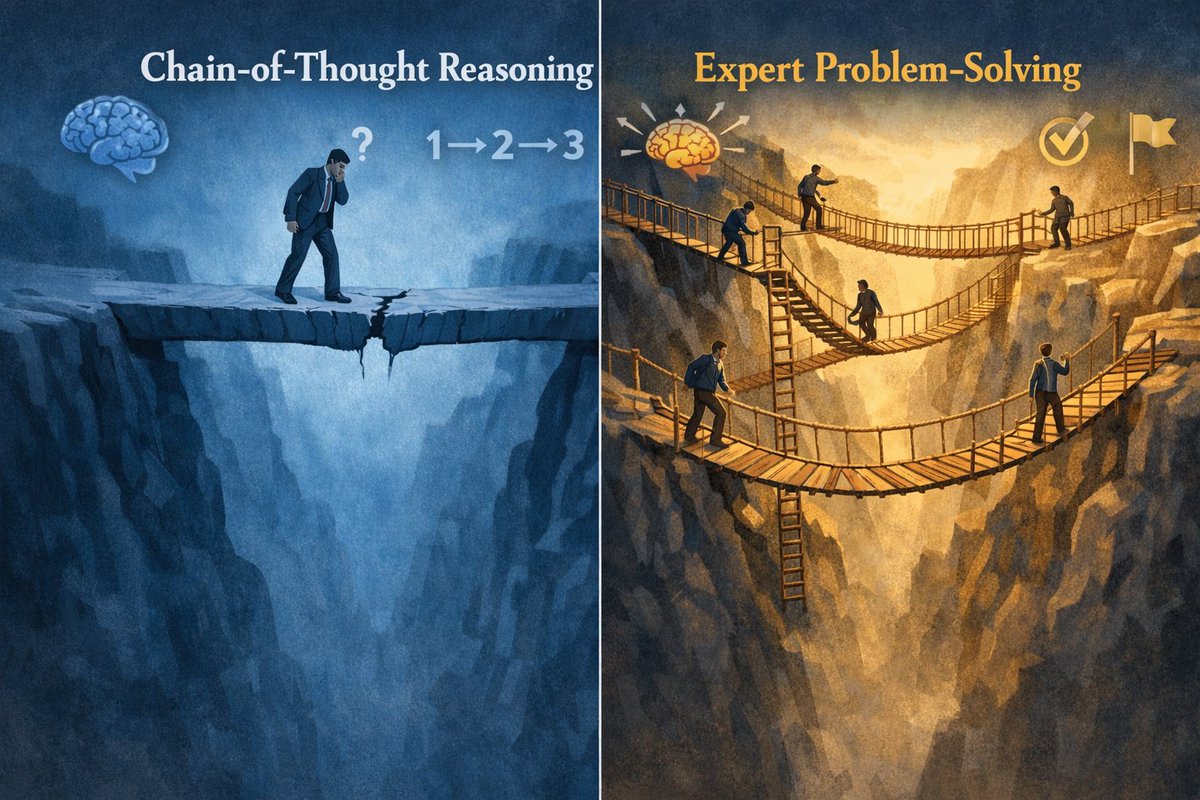
Current AI reasoning is linear. Think step 1 → step 2 → step 3.
But that's not how expert problem-solvers think.
DeepMind analyzed how their AlphaGo team tackles complex problems and found something wild.
3
Parallel Verification Loops:
Instead of one long reasoning chain, expert thinkers run multiple verification loops simultaneously.
They propose a solution, test it against constraints, backtrack when needed, and explore alternative paths—all at the same time.
Chain-of-thought can't do this.
Instead of one long reasoning chain, expert thinkers run multiple verification loops simultaneously.
They propose a solution, test it against constraints, backtrack when needed, and explore alternative paths—all at the same time.
Chain-of-thought can't do this.
4
The Architecture Difference:
Traditional CoT: A → B → C → D (linear)
DeepMind's framework: A → [B1, B2, B3] → verify each → refine → iterate
It's the difference between walking down one path vs exploring an entire decision tree in parallel.
Traditional CoT: A → B → C → D (linear)
DeepMind's framework: A → [B1, B2, B3] → verify each → refine → iterate
It's the difference between walking down one path vs exploring an entire decision tree in parallel.
5
The results are insane:
On complex reasoning benchmarks:
- 37% improvement over standard chain-of-thought
- 52% better at catching logical errors
- 3x faster convergence to correct solutions
This isn't incremental. It's architectural.
On complex reasoning benchmarks:
- 37% improvement over standard chain-of-thought
- 52% better at catching logical errors
- 3x faster convergence to correct solutions
This isn't incremental. It's architectural.
6
How it actually works:
Step 1: Generate multiple candidate solutions simultaneously
Step 2: Each solution runs its own verification loop
Step 3: Cross-validate solutions against each other
Step 4: Prune weak branches, strengthen promising ones
Step 5: Iterate until convergence
Step 1: Generate multiple candidate solutions simultaneously
Step 2: Each solution runs its own verification loop
Step 3: Cross-validate solutions against each other
Step 4: Prune weak branches, strengthen promising ones
Step 5: Iterate until convergence
7
The self-correction advantage:
Here's the killer feature: the system catches its own mistakes BEFORE committing to an answer.
Traditional CoT commits to each step sequentially. One wrong step and you're lost.
Parallel verification lets you backtrack without starting over.
Here's the killer feature: the system catches its own mistakes BEFORE committing to an answer.
Traditional CoT commits to each step sequentially. One wrong step and you're lost.
Parallel verification lets you backtrack without starting over.
8
Most "reasoning models" today are just longer prompts.
DeepMind proved you need fundamentally different architecture.
It's not about thinking harder. It's about thinking in parallel.
Like how your brain doesn't solve problems linearly—it explores possibilities simultaneously.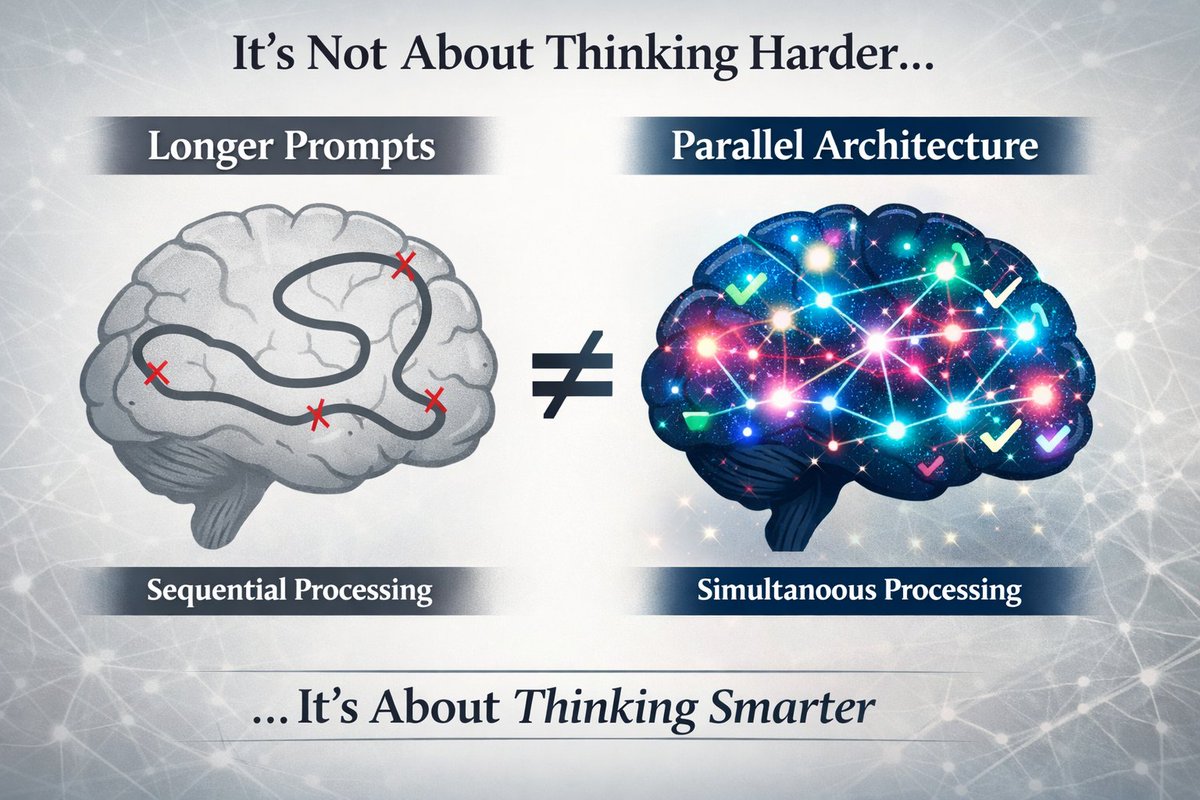
DeepMind proved you need fundamentally different architecture.
It's not about thinking harder. It's about thinking in parallel.
Like how your brain doesn't solve problems linearly—it explores possibilities simultaneously.
9
The training implications:
They didn't just test this they trained models using this framework.
The model learns to:
- Propose multiple hypotheses
- Test them against each other
- Build confidence through verification
- Prune bad reasoning paths early
They didn't just test this they trained models using this framework.
The model learns to:
- Propose multiple hypotheses
- Test them against each other
- Build confidence through verification
- Prune bad reasoning paths early
10
Real-world applications:
This framework crushes on:
- Mathematical proofs (where one error ruins everything)
- Code debugging (multiple possible bugs)
- Strategic planning (exploring decision trees)
- Scientific reasoning (hypothesis testing)
Anywhere you need correctness over speed.
This framework crushes on:
- Mathematical proofs (where one error ruins everything)
- Code debugging (multiple possible bugs)
- Strategic planning (exploring decision trees)
- Scientific reasoning (hypothesis testing)
Anywhere you need correctness over speed.
11
If you're building AI agents or reasoning systems, chain-of-thought is already obsolete.
The future is parallel verification.
Generate multiple paths. Test them. Let the best solution emerge.
That's how AlphaGo beat the world champion. That's how reasoning actually works.
The future is parallel verification.
Generate multiple paths. Test them. Let the best solution emerge.
That's how AlphaGo beat the world champion. That's how reasoning actually works.
12
AI is not going to take job.
Our newsletter, The Shift, delivers breakthroughs, tools, and strategies to help you become value creator and build in this new era easily.
Subscribe: theshiftai.beehiiv.com/subscribe
Plus: Get access to 3k+ AI Tools and free AI courses when you join.
Our newsletter, The Shift, delivers breakthroughs, tools, and strategies to help you become value creator and build in this new era easily.
Subscribe: theshiftai.beehiiv.com/subscribe
Plus: Get access to 3k+ AI Tools and free AI courses when you join.
13
I hope you've found this thread helpful.
Follow me @aiwithjainam for more.
Like/Repost the quote below if you can:
Follow me @aiwithjainam for more.
Like/Repost the quote below if you can:
Jainam Parmar@aiwithjainam
Holy shit... Google DeepMind just exposed why everyone's been doing AI reasoning wrong.
The AlphaGo team doesn't use chain-of-thought. They use parallel verification loops.
And it's destroying every "advanced reasoning" technique you've heard about.
Here's what they discovered ↓
The AlphaGo team doesn't use chain-of-thought. They use parallel verification loops.
And it's destroying every "advanced reasoning" technique you've heard about.
Here's what they discovered ↓