@__paleologo's "Elements of Quantitative Investing" has a chapter...

sysls@systematicls
193 views
Nov 27, 2025
~6 min read
Advertisement
1
@__paleologo's "Elements of Quantitative Investing" has a chapter that's prompted a lot of questions from people I've recommended the book to.
Section 4.3: Alpha Spanned vs Alpha Orthogonal.
Most people skim it and think it's about portfolio construction. It's not. It's actually "roughly" a no-arbitrage argument about what kind of alpha can even exist.
For you to understand it, you need to understand that there is a "setup" and THEN the argument.
The set-up allowed Gappy to make the argument.
-----
The setup is simple. Factor model:
r = α + Bf + ε
Your alpha vector α can be split into two pieces:
a) The part that lives in the factor subspace (spanned) b) The part perpendicular to it (orthogonal).
α = α_spanned + α_orthogonal
Orthogonal alpha comes with idiosyncratic risk - uncorrelated across stocks. Spanned alpha comes with systematic risk - correlated, it's factor exposure.
So why bother decomposing alpha at all? Why not just call it "alpha" and move on? Because spanned and orthogonal alpha are completely different animals:
------
Alpha Spanned:
- Systematic risk (doesn't diversify)
- Sharpe doesn't scale with n
- Can exist at scale (it's factor premia)
- Replicable with factor ETFs
Alpha Orthogonal:
- Idiosyncratic risk (diversifies)
- Sharpe scales with √n
- Cannot persist at scale (gets arbed)
- Not replicable (your actual edge)
If you don't decompose, you don't know which one you have. You might think you're special when you're just long momentum.
Four reasons this decomposition matters:
1. Understanding what's even possible
Most "alpha" is probably spanned. Factor premia dressed up. True orthogonal alpha is rare, small, and temporary. The √n argument proves it can't exist at scale. Don't waste years looking for something that can't persist.
2. Understanding what you're giving up
When you factor-neutralize, you zero out alpha spanned. But factor premia are real money. You're deliberately throwing away expected returns.
Should you? Depends:
- Are those premia compensating you for risk you want to bear?
- Do you have edge in factor timing?
- What's your mandate?
The decomposition forces you to make this choice consciously, not accidentally.
3. Understanding where your returns actually come from
Even if your portfolio is factor-neutral, you want to know: is my signal capturing orthogonal alpha, or is it just noise after you strip out the factor stuff?
If your raw alpha is 80% spanned and you neutralize it, you might be left with nothing. Better to know this before you trade.
4. The indeterminacy problem
Alpha spanned is mathematically indistinguishable from factor expected returns. You cannot tell them apart. The model r = α + Bf can be rewritten as r = α_orth + B(f + λ). The spanned part gets absorbed into factor means.
So when someone claims "I found alpha," the decomposition asks: is this actually alpha, or just factor timing? Are you skilled, or are you just long value when value worked?
------
Here's the argument and the insight.
Idiosyncratic risk diversifies. Systematic risk doesn't. So when you build a portfolio of orthogonal alpha bets, the risk shrinks as you add stocks, but the expected return doesn't. Sharpe goes up.
Paleologo proves a bound:
SR ≥ √n × (avg orthogonal alpha) / (max idio vol)
Now watch what happens as n gets large.
If average orthogonal alpha per stock stays positive... and max idiosyncratic volatility is bounded... then Sharpe goes to infinity as n -> ∞.
Infinite Sharpe is impossible. Something has to break. [This is the "rough" no arbitrage argument]
If the factor model is right and idio vol is bounded, then orthogonal alpha must be vanishing. It can't stay positive on average across thousands of stocks. If it did, someone would build a diversified portfolio, print infinite Sharpe, and arb it away.
Translation: Pure alpha - returns perpendicular to all systematic factors - cannot persist at scale. The market won't allow it.
------
This implies:
Factor premia (spanned): Real, persistent, but not special. Anyone can harvest them with ETFs. The edge is in implementation, risk management, transaction costs, operational alpha. It's a scale game.
True alpha (orthogonal): Rare, small, fleeting. The √n argument guarantees it gets arbed away. The edge is finding it before others do and harvesting it quickly. Then moving on.
Section 4.3: Alpha Spanned vs Alpha Orthogonal.
Most people skim it and think it's about portfolio construction. It's not. It's actually "roughly" a no-arbitrage argument about what kind of alpha can even exist.
For you to understand it, you need to understand that there is a "setup" and THEN the argument.
The set-up allowed Gappy to make the argument.
-----
The setup is simple. Factor model:
r = α + Bf + ε
Your alpha vector α can be split into two pieces:
a) The part that lives in the factor subspace (spanned) b) The part perpendicular to it (orthogonal).
α = α_spanned + α_orthogonal
Orthogonal alpha comes with idiosyncratic risk - uncorrelated across stocks. Spanned alpha comes with systematic risk - correlated, it's factor exposure.
So why bother decomposing alpha at all? Why not just call it "alpha" and move on? Because spanned and orthogonal alpha are completely different animals:
------
Alpha Spanned:
- Systematic risk (doesn't diversify)
- Sharpe doesn't scale with n
- Can exist at scale (it's factor premia)
- Replicable with factor ETFs
Alpha Orthogonal:
- Idiosyncratic risk (diversifies)
- Sharpe scales with √n
- Cannot persist at scale (gets arbed)
- Not replicable (your actual edge)
If you don't decompose, you don't know which one you have. You might think you're special when you're just long momentum.
Four reasons this decomposition matters:
1. Understanding what's even possible
Most "alpha" is probably spanned. Factor premia dressed up. True orthogonal alpha is rare, small, and temporary. The √n argument proves it can't exist at scale. Don't waste years looking for something that can't persist.
2. Understanding what you're giving up
When you factor-neutralize, you zero out alpha spanned. But factor premia are real money. You're deliberately throwing away expected returns.
Should you? Depends:
- Are those premia compensating you for risk you want to bear?
- Do you have edge in factor timing?
- What's your mandate?
The decomposition forces you to make this choice consciously, not accidentally.
3. Understanding where your returns actually come from
Even if your portfolio is factor-neutral, you want to know: is my signal capturing orthogonal alpha, or is it just noise after you strip out the factor stuff?
If your raw alpha is 80% spanned and you neutralize it, you might be left with nothing. Better to know this before you trade.
4. The indeterminacy problem
Alpha spanned is mathematically indistinguishable from factor expected returns. You cannot tell them apart. The model r = α + Bf can be rewritten as r = α_orth + B(f + λ). The spanned part gets absorbed into factor means.
So when someone claims "I found alpha," the decomposition asks: is this actually alpha, or just factor timing? Are you skilled, or are you just long value when value worked?
------
Here's the argument and the insight.
Idiosyncratic risk diversifies. Systematic risk doesn't. So when you build a portfolio of orthogonal alpha bets, the risk shrinks as you add stocks, but the expected return doesn't. Sharpe goes up.
Paleologo proves a bound:
SR ≥ √n × (avg orthogonal alpha) / (max idio vol)
Now watch what happens as n gets large.
If average orthogonal alpha per stock stays positive... and max idiosyncratic volatility is bounded... then Sharpe goes to infinity as n -> ∞.
Infinite Sharpe is impossible. Something has to break. [This is the "rough" no arbitrage argument]
If the factor model is right and idio vol is bounded, then orthogonal alpha must be vanishing. It can't stay positive on average across thousands of stocks. If it did, someone would build a diversified portfolio, print infinite Sharpe, and arb it away.
Translation: Pure alpha - returns perpendicular to all systematic factors - cannot persist at scale. The market won't allow it.
------
This implies:
Factor premia (spanned): Real, persistent, but not special. Anyone can harvest them with ETFs. The edge is in implementation, risk management, transaction costs, operational alpha. It's a scale game.
True alpha (orthogonal): Rare, small, fleeting. The √n argument guarantees it gets arbed away. The edge is finding it before others do and harvesting it quickly. Then moving on.
2
@__paleologo I'm expecting the market to clear
sysls@systematicls
There's a level of abstraction for everyone.
The entire internet exists. Every paper. Every dataset. Every insight humanity has published. A search function to find it all.
We don't WANT to read it. Most never go past page 1 of Google.
Enter the weird little chatboxes. A layer of abstraction above the great internet. "EXPLAIN LIKE I'M 5," you bark.
You take what you've learned. Release a 30-minute YouTube deep dive. Educational. Smart. 2k views.
Random account tweets a 5-min summary. 10k likes.
Follow-up account retweets the retweet:
"TLDR: fit tight predict loose hurdur"
50k likes.
There's a level of abstraction for everyone.
The entire internet exists. Every paper. Every dataset. Every insight humanity has published. A search function to find it all.
We don't WANT to read it. Most never go past page 1 of Google.
Enter the weird little chatboxes. A layer of abstraction above the great internet. "EXPLAIN LIKE I'M 5," you bark.
You take what you've learned. Release a 30-minute YouTube deep dive. Educational. Smart. 2k views.
Random account tweets a 5-min summary. 10k likes.
Follow-up account retweets the retweet:
"TLDR: fit tight predict loose hurdur"
50k likes.
There's a level of abstraction for everyone.
3
@__paleologo If you like this and don't follow me, I will be hiding under your bed tonight.
4
Lots of questions following-up on alpha spanned: why doesn't beta "absorb" the spanned part when you run a regression?
-----
Beta captures sensitivity. Not expected return.
When you run a factor regression, you're asking: "When the market goes up 1%, how much does this stock go up?" That's beta. It measures how your stock moves with the factor.
But here's the thing: beta multiplies factor *fluctuations*. It tells you how you move WITH the factor on any given day. It doesn't tell you anything about average returns.
Alpha spanned is an expected return component. It's saying: "On average, I expect extra return in the direction of factors." That's a statement about means, not about day-to-day comovement.
The regression doesn't know to put expected returns into beta. It just sees: "here's sensitivity, here's an intercept." The intercept catches everything the sensitivity term doesn't explain - including expected returns that happen to point toward factors.
Think of it this way:
Beta asks: "How correlated are we?"
Alpha (regression intercept) asks: "What's left over after accounting for that correlation?"
The spanned vs orthogonal question is different. It asks: "Does this leftover point in the same direction as the factors?"
The regression isn't trying to answer that question. It doesn't impose any constraint forcing alpha to be perpendicular to factor space. It just gives you whatever intercept fits the data.
So your regression alpha will generically have both components:
- Orthogonal alpha (truly perpendicular to factors)
- Spanned alpha (expected return that happens to point toward factors)
To separate them, you need a second step: project your alpha onto the orthogonal complement of factor space.
The regression won't do this for you. It's a separate operation you have to choose to do.
-----
Why does alpha have a spanned component at all?
Because "pointing exactly perpendicular to all factors" is an extremely specific condition. It's like asking a random arrow in 3D space to land exactly horizontal. Almost never happens by accident.
Unless you deliberately construct your model so alpha is orthogonal by definition (by shifting factor means to absorb the spanned part), your alpha will have both pieces. That's the default state. Nothing wrong with it - you just need to know it's there.
-----
Beta captures sensitivity. Not expected return.
When you run a factor regression, you're asking: "When the market goes up 1%, how much does this stock go up?" That's beta. It measures how your stock moves with the factor.
But here's the thing: beta multiplies factor *fluctuations*. It tells you how you move WITH the factor on any given day. It doesn't tell you anything about average returns.
Alpha spanned is an expected return component. It's saying: "On average, I expect extra return in the direction of factors." That's a statement about means, not about day-to-day comovement.
The regression doesn't know to put expected returns into beta. It just sees: "here's sensitivity, here's an intercept." The intercept catches everything the sensitivity term doesn't explain - including expected returns that happen to point toward factors.
Think of it this way:
Beta asks: "How correlated are we?"
Alpha (regression intercept) asks: "What's left over after accounting for that correlation?"
The spanned vs orthogonal question is different. It asks: "Does this leftover point in the same direction as the factors?"
The regression isn't trying to answer that question. It doesn't impose any constraint forcing alpha to be perpendicular to factor space. It just gives you whatever intercept fits the data.
So your regression alpha will generically have both components:
- Orthogonal alpha (truly perpendicular to factors)
- Spanned alpha (expected return that happens to point toward factors)
To separate them, you need a second step: project your alpha onto the orthogonal complement of factor space.
The regression won't do this for you. It's a separate operation you have to choose to do.
-----
Why does alpha have a spanned component at all?
Because "pointing exactly perpendicular to all factors" is an extremely specific condition. It's like asking a random arrow in 3D space to land exactly horizontal. Almost never happens by accident.
Unless you deliberately construct your model so alpha is orthogonal by definition (by shifting factor means to absorb the spanned part), your alpha will have both pieces. That's the default state. Nothing wrong with it - you just need to know it's there.
5
@__paleologo It's so weird that the main post doesn't show up on my profile. Got dm'ed about this.
Why did this post get shadow banned? @nikitabier
Why did this post get shadow banned? @nikitabier
6
@__paleologo @nikitabier See, where'd you go
Mystery post
I miss you so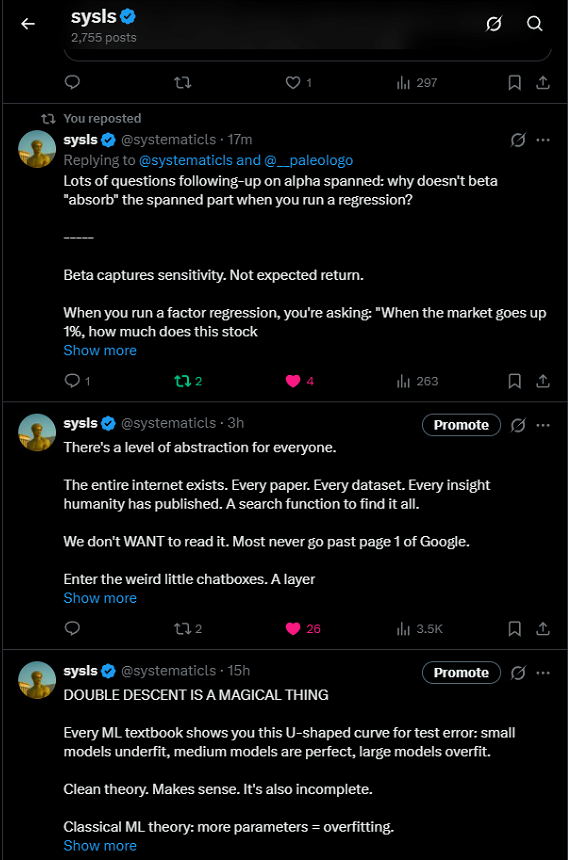
Mystery post
I miss you so


