New paper called SPRINT. Improvement over TREAD SPRINT: SPARSE-...

sway@SwayStar123
34 views
Oct 29, 2025
~1 min read
Advertisement
1
New paper called SPRINT. Improvement over TREAD
SPRINT: SPARSE-DENSE RESIDUAL FUSION FOR EFFICIENT DIFFUSION TRANSFORMERS
Diffusion Transformers (DiTs) deliver state-of-the-art generative performance but their quadratic training cost with sequence length makes large-scale pretraining prohibitively expensive. Token dropping can reduce training cost, yet naïve strategies degrade representations, and existing methods are either parameter-heavy or fail at high drop ratios. We present SPRINT, Sparse–Dense Residual Fusion for Efficient Diffusion Transformers, a simple method that enables aggressive token dropping (up to 75%) while preserving quality. SPRINT leverages the complementary roles of shallow and deep layers: early layers process all tokens to capture local detail, deeper layers operate on a sparse subset to cut computation, and their outputs are fused through residual connections. Training follows a two-stage schedule: long masked pre-training for efficiency followed by short full-token fine-tuning to close the train–inference gap. On ImageNet-1K 2562 , SPRINT achieves 9.8× training savings with comparable FID/FDD, and at inference, its Path-Drop Guidance (PDG) nearly halves FLOPs while improving quality. These results establish SPRINT as a simple, effective, and general solution for efficient DiT training.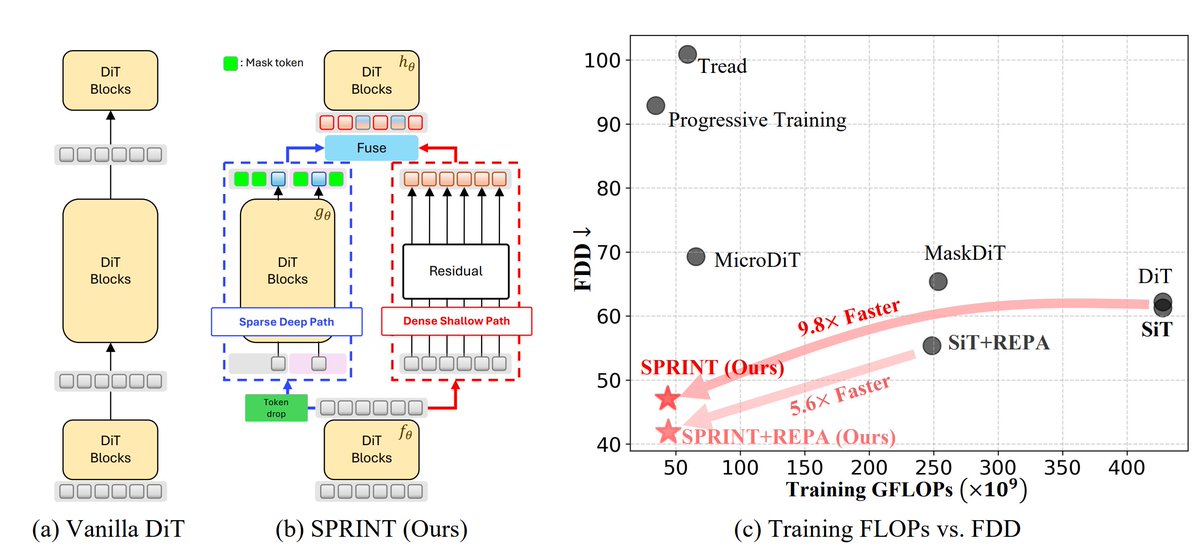
SPRINT: SPARSE-DENSE RESIDUAL FUSION FOR EFFICIENT DIFFUSION TRANSFORMERS
Diffusion Transformers (DiTs) deliver state-of-the-art generative performance but their quadratic training cost with sequence length makes large-scale pretraining prohibitively expensive. Token dropping can reduce training cost, yet naïve strategies degrade representations, and existing methods are either parameter-heavy or fail at high drop ratios. We present SPRINT, Sparse–Dense Residual Fusion for Efficient Diffusion Transformers, a simple method that enables aggressive token dropping (up to 75%) while preserving quality. SPRINT leverages the complementary roles of shallow and deep layers: early layers process all tokens to capture local detail, deeper layers operate on a sparse subset to cut computation, and their outputs are fused through residual connections. Training follows a two-stage schedule: long masked pre-training for efficiency followed by short full-token fine-tuning to close the train–inference gap. On ImageNet-1K 2562 , SPRINT achieves 9.8× training savings with comparable FID/FDD, and at inference, its Path-Drop Guidance (PDG) nearly halves FLOPs while improving quality. These results establish SPRINT as a simple, effective, and general solution for efficient DiT training.