🚀 We just set a new SOTA for LLM inference acceleration with...

Yu-Xiang Wang@yuxiangw_cs
13 views
Oct 26, 2025
~2 min read
Advertisement
1
🚀 We just set a new SOTA for LLM inference acceleration with speculative decoding. By corralling a band of specialist drafters, we got 4.99× on Llama-3.1-8B-Instruct, 4.93× on Qwen-32B — beating EAGLE3 by nearly 2x. No gimmicks. Just careful math + solid engineering. 🧵1/

2
This is led by my summer intern Hongyi Liu (@aladinggit) at AWS, in collaboration with other awesome people: @JiajiHuang, Zhen Jia, @YoungsukP. Super excited that it's finally out. arXiv link: arxiv.org/abs/2510.20064 2/
So how does it work? Let's start with some intuition.
So how does it work? Let's start with some intuition.
3
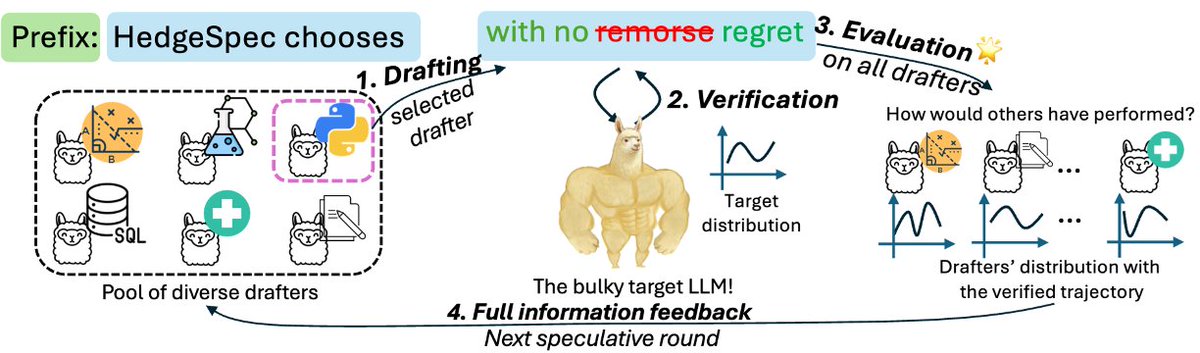
LLMs receive diverse set of requests: math, coding, sciences, essay writings, etc. EAGLE3 drafter is a generalist that tries to do well overall. But a specialist would be better in each domain. Our method -- HedgeSpec -- nearly matches the best specialist for each query! 3/

4
Our key innovation: We add an evaluation phase after each speculative decoding round in which we "replay" the generated tokens on those drafters that we did not choose. This allows us to update our "bets" on the fly. The best drafter often stands out within a few rounds. 4/
5
A natural alternative idea is to use bandits algorithms. That's exactly what @zhuoran_yang at Yale and Vincent Tan et al at NUS did. BanditSpec balances "Exploration" and "Exploitation". Our insight is that "Exploration" is actually unnecessary, hence allows faster learning. 5/

6
HedgeSpec enjoys provable regret guarantees. And it beats BanditSpec exponentially in the # of specialists. (see the regret figure below). There are technical details and nuances that require us to handle "delayed feedback", which I encourage people to read the paper for. 6/

7
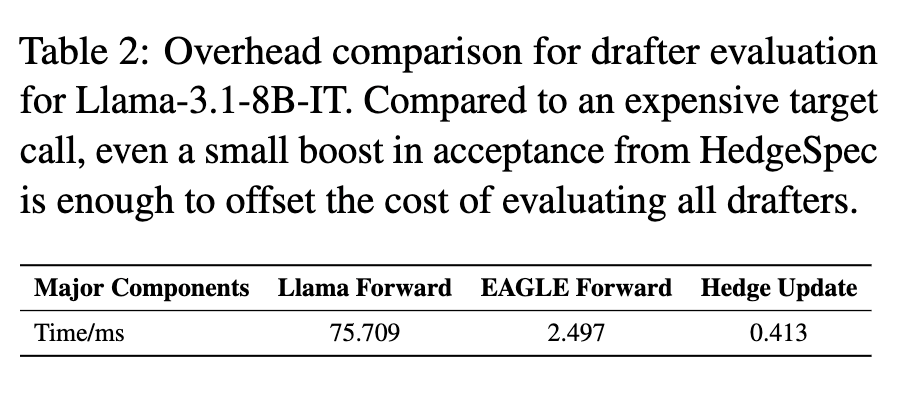
The only remaining hurdle is the engineering challenge to implement the evaluation phase for all experts with low overhead. I will leave hackers to read the code. All I can say is that @aladinggit is very creative and hardcore. 7/
8
The end results? Across 7 domains we tested, HedgeSpec dominates in every one of them.
Why restrict to 7 domains? Why not train even more specialist drafters? We totally should --- but the community can do them better. There are many low-hanging fruits within reach. 8/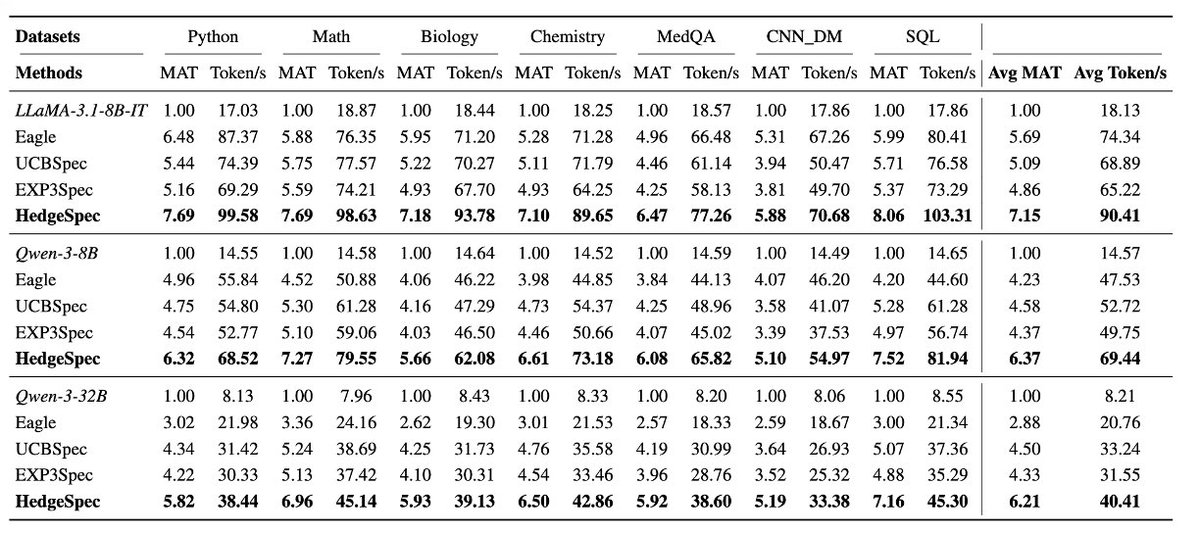
Why restrict to 7 domains? Why not train even more specialist drafters? We totally should --- but the community can do them better. There are many low-hanging fruits within reach. 8/
9
Overall, this is a highly satisfying project where rigorous online learning theory meets LLM practice -- giving rise to a brand new mode of test-time learning.
Co-authors: @aladinggit, @JiajiHuang, Zhen Jia, @YoungsukP ArXiv: arxiv.org/abs/2510.20064
Comments are welcome!
Co-authors: @aladinggit, @JiajiHuang, Zhen Jia, @YoungsukP ArXiv: arxiv.org/abs/2510.20064
Comments are welcome!