🚨 Holy shit...Meta just rewrote how Transformers think. They built...

Robert Youssef@rryssf
136 views
Oct 23, 2025
~2 min read
Advertisement
1
🚨 Holy shit...Meta just rewrote how Transformers think.
They built something called The Free Transformer and it breaks the core rule every GPT model has lived by since 2017.
For 8 years, Transformers have been blindfolded forced to guess the next token one at a time, no inner plan, no latent thought.
Meta gave it one.
They added random latent variables inside the decoder so the model can secretly decide how it wants to generate before it starts talking.
It’s like giving GPT a hidden mind.
Result:
🧠 Smarter reasoning
⚡️ 3% compute overhead
📈 Outperforms larger baselines on GSM8K, MMLU, and HumanEval
It’s the first Transformer that doesn’t just predict it intends.
Full paper: arxiv. org/abs/2510.17558v1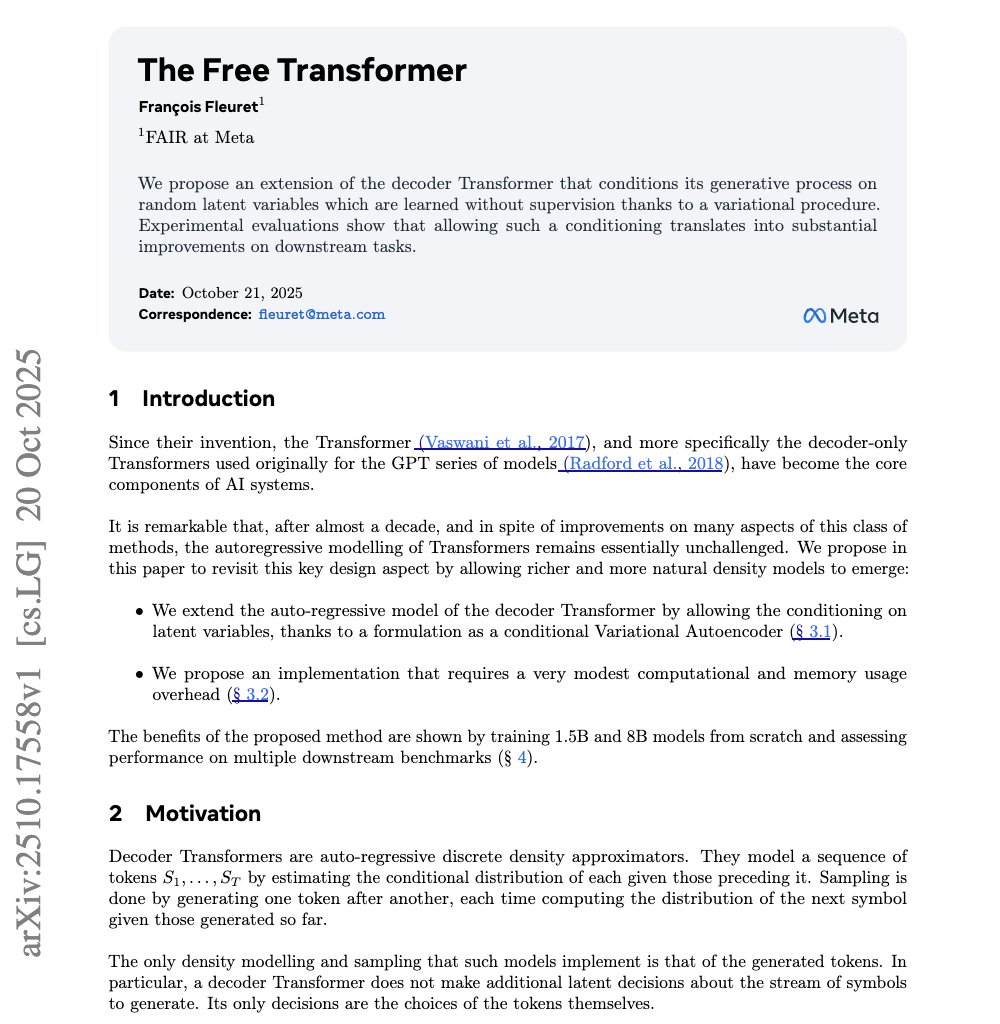
They built something called The Free Transformer and it breaks the core rule every GPT model has lived by since 2017.
For 8 years, Transformers have been blindfolded forced to guess the next token one at a time, no inner plan, no latent thought.
Meta gave it one.
They added random latent variables inside the decoder so the model can secretly decide how it wants to generate before it starts talking.
It’s like giving GPT a hidden mind.
Result:
🧠 Smarter reasoning
⚡️ 3% compute overhead
📈 Outperforms larger baselines on GSM8K, MMLU, and HumanEval
It’s the first Transformer that doesn’t just predict it intends.
Full paper: arxiv. org/abs/2510.17558v1
2
Meta added latent random variables (Z) into the decoder.
Think of it like a subconscious layer before generating text, the model samples internal “choices” that guide the style or structure of the whole sequence.
Technically, this is done using a Conditional Variational Autoencoder (VAE) built inside the Transformer itself.
They call it the Free Transformer.
Think of it like a subconscious layer before generating text, the model samples internal “choices” that guide the style or structure of the whole sequence.
Technically, this is done using a Conditional Variational Autoencoder (VAE) built inside the Transformer itself.
They call it the Free Transformer.
3
They inject the latent Z halfway through the decoder.
So half the blocks act like a shared encoder, and the rest decode with that latent context.
This design slashes compute overhead only ~3–4% extra FLOPs compared to a standard model.
So half the blocks act like a shared encoder, and the rest decode with that latent context.
This design slashes compute overhead only ~3–4% extra FLOPs compared to a standard model.
4
It’s trained with the classic VAE objective:
Cross-entropy loss + KL divergence penalty between the encoder distribution Q(Z|S) and prior P(Z).
They use a free-bits threshold (κ) to prevent collapse only adding KL loss if divergence > κ.
This lets Z encode useful structure (like topic, sentiment, or pattern position) without overfitting.
Cross-entropy loss + KL divergence penalty between the encoder distribution Q(Z|S) and prior P(Z).
They use a free-bits threshold (κ) to prevent collapse only adding KL loss if divergence > κ.
This lets Z encode useful structure (like topic, sentiment, or pattern position) without overfitting.
5
The Results
They trained 1.5B and 8B models.
Performance on reasoning-heavy benchmarks like GSM8K, HumanEval+, and MMLU jumps significantly.
Example gains (1.5B model):
+44% on HumanEval+
+35% on MBPP
+30% on GSM8K
All with just 3–4% compute overhead.
And the model stays stable no training collapse or weird spikes.
They trained 1.5B and 8B models.
Performance on reasoning-heavy benchmarks like GSM8K, HumanEval+, and MMLU jumps significantly.
Example gains (1.5B model):
+44% on HumanEval+
+35% on MBPP
+30% on GSM8K
All with just 3–4% compute overhead.
And the model stays stable no training collapse or weird spikes.
6
The Free Transformer adds a stochastic “hidden mind” to the architecture.
Instead of just predicting it decides, then predicts.
This could be the start of the post-autoregressive era.
Transformers that plan. Not just parrot.
Instead of just predicting it decides, then predicts.
This could be the start of the post-autoregressive era.
Transformers that plan. Not just parrot.
7
Stop wasting hours writing prompts
→ 10,000+ ready-to-use prompts
→ Create your own in seconds
→ Lifetime access. One-time payment.
Claim your copy 👇
godofprompt.ai/pricing
→ 10,000+ ready-to-use prompts
→ Create your own in seconds
→ Lifetime access. One-time payment.
Claim your copy 👇
godofprompt.ai/pricing