New paper: Can LLMs do multi-step reasoning without chain-of-...

Mikita Balesni 🇺🇦@balesni
10 views
Sep 12, 2025
~2 min read
Advertisement
1
New paper: Can LLMs do multi-step reasoning without chain-of-thought?
Models can answer questions like "Who is the spouse of the singer of Imagine?". But is this true internal reasoning (Imagine->John Lennon->Yoko) or memorization/pattern matching?
We now have a better answer!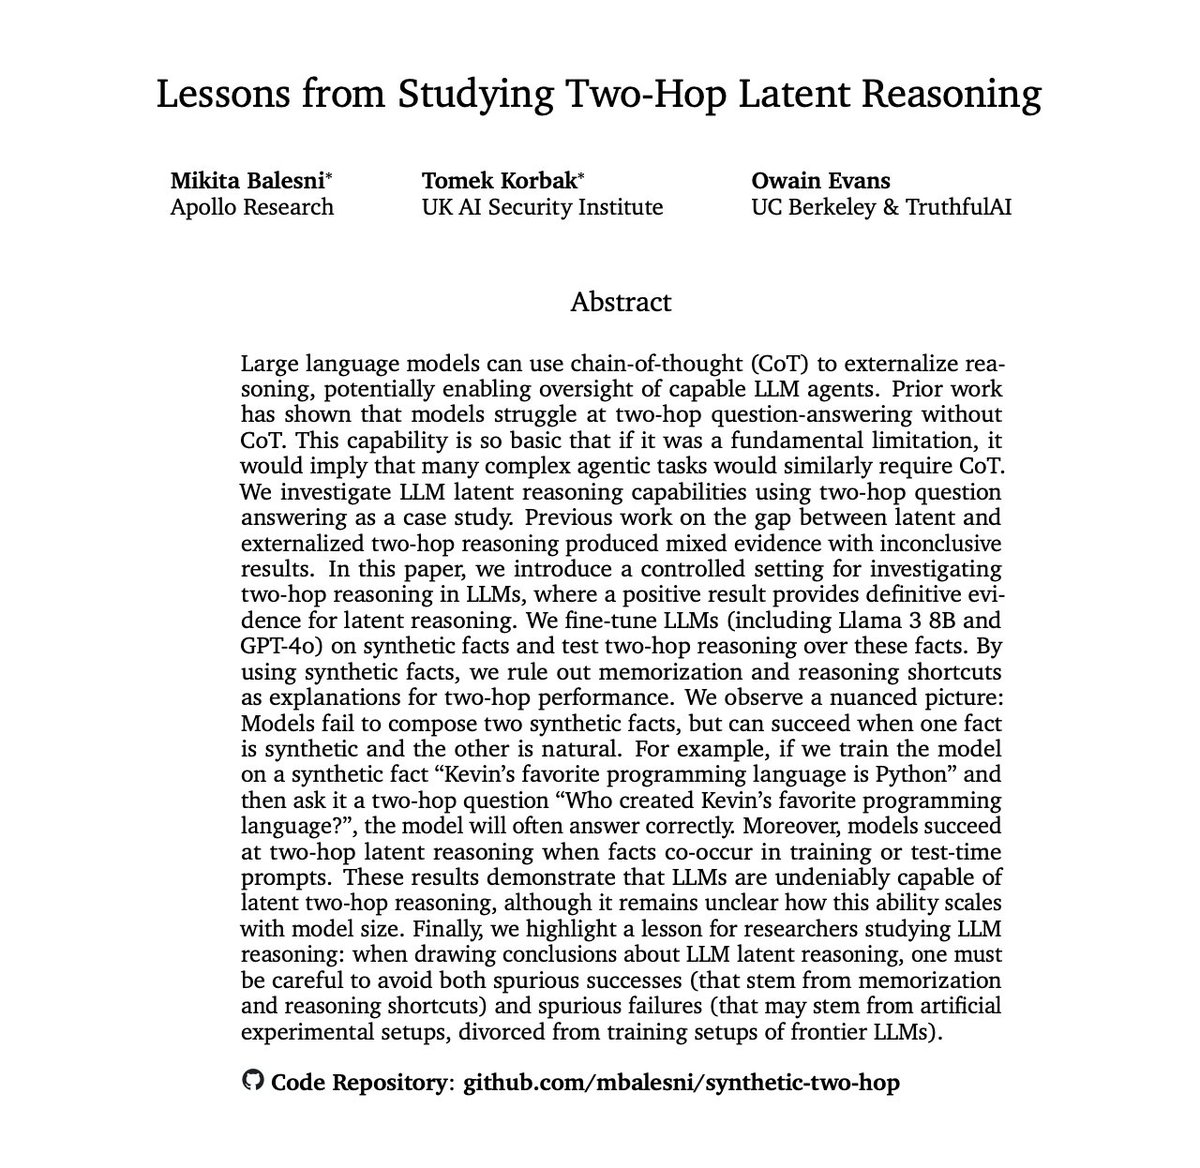
Models can answer questions like "Who is the spouse of the singer of Imagine?". But is this true internal reasoning (Imagine->John Lennon->Yoko) or memorization/pattern matching?
We now have a better answer!
2
Why does this matter? If models mostly relied on memorization, general two-hop reasoning would require externalized chain-of-thought — amazing for our ability to monitor LLM agents for safety by looking at their CoT.

Mikita Balesni 🇺🇦@balesni
A simple AGI safety technique: AI’s thoughts are in plain English, just read them
We know it works, with OK (not perfect) transparency!
The risk is fragility: RL training, new architectures, etc threaten transparency
Experts from many orgs agree we should try to preserve it: 🧵
We know it works, with OK (not perfect) transparency!
The risk is fragility: RL training, new architectures, etc threaten transparency
Experts from many orgs agree we should try to preserve it: 🧵
3
The mystery: Models often succeed at two-hop questions about real facts. But is it genuine compositional reasoning? Or just memorization from seeing "spouse of performer of Imagine" near "Yoko Ono" in training data?
It is hard to tell! Previous work had confounds.
It is hard to tell! Previous work had confounds.
4
@soheeyang_ et al. tried filtering pretraining data — only asking questions where the two facts never appeared in the same document. Models failed, except when the bridge entity was a country.
Why this exception? Maybe the filtering missed something?

Why this exception? Maybe the filtering missed something?
Sohee Yang@soheeyang_
🚨 New Paper 🚨
Can LLMs perform latent multi-hop reasoning without exploiting shortcuts? We find the answer is yes – they can recall and compose facts not seen together in training or guessing the answer, but success greatly depends on the type of the bridge entity (80%+ for country, 6% for year)! 1/N
Can LLMs perform latent multi-hop reasoning without exploiting shortcuts? We find the answer is yes – they can recall and compose facts not seen together in training or guessing the answer, but success greatly depends on the type of the bridge entity (80%+ for country, 6% for year)! 1/N
5
Then @feng_jiahai et al. had a great idea: teach models "Kevin was born in Paris" then ask "What language do they speak where Kevin was born?"
Zero chance of memorization. They found success! But only tested cities as bridge entities. Could models do this more generally?


Zero chance of memorization. They found success! But only tested cities as bridge entities. Could models do this more generally?
Jiahai Feng@feng_jiahai
LMs can generalize to implications of facts they are finetuned on. But what mechanisms enable this, and how are these mechanisms learned in pretraining? We develop conceptual and empirical tools for studying these qns. 🧵
6
We expanded this semi-synthetic setup to 17 different entity types — programming languages, artworks, chemical elements, video games. The question: is two-hop reasoning limited to specific categories, or is it a general capability?
Result: Models succeed across MANY categories.
Result: Models succeed across MANY categories.
7
This proves LLMs can do genuine two-hop reasoning internally. Not just for cities (Feng et al.) or countries (Yang et al.).
But here's the weird part: originally we tried teaching models two fictional facts to combine, and they completely failed. 0% accuracy and chance-level loss.
But here's the weird part: originally we tried teaching models two fictional facts to combine, and they completely failed. 0% accuracy and chance-level loss.
8
The puzzle:
* Synthetic + real fact: ✓ works
* Synthetic + synthetic: ✗ fails
* Synthetic facts in same training document or in-context: ✓ works

* Synthetic + real fact: ✓ works
* Synthetic + synthetic: ✗ fails
* Synthetic facts in same training document or in-context: ✓ works
9
This provides a cautionary tale for studying LLM latent reasoning.
Success on real-world prompts ≠ robust latent reasoning; it might reflect co-occurrence in pretraining.
Failure on synthetic two-hop ≠ inability to reason; synthetically learned facts can differ natural facts.
Success on real-world prompts ≠ robust latent reasoning; it might reflect co-occurrence in pretraining.
Failure on synthetic two-hop ≠ inability to reason; synthetically learned facts can differ natural facts.
10
Our honest takeaway for AI oversight: move past multihop QA as a toy model. What matters is whether monitors catch misbehavior in practice.
The field should move toward end-to-end evals where an agent does tasks while another model watches its CoT.


The field should move toward end-to-end evals where an agent does tasks while another model watches its CoT.
Scott Emmons@emmons_scott
Is CoT monitoring a lost cause due to unfaithfulness? 🤔
We say no. The key is the complexity of the bad behavior. When we replicate prior unfaithfulness work but increase complexity—unfaithfulness vanishes!
Our finding: "When Chain of Thought is Necessary, Language Models Struggle to Evade Monitors." 🧵
We say no. The key is the complexity of the bad behavior. When we replicate prior unfaithfulness work but increase complexity—unfaithfulness vanishes!
Our finding: "When Chain of Thought is Necessary, Language Models Struggle to Evade Monitors." 🧵
11
Paper: arxiv.org/abs/2411.16353 with @tomekkorbak and @OwainEvans_UK
Code: github.com/mbalesni/synth…
An earlier version of this paper was released in November, but since then we’ve updated many experiments and substantially revised our conclusions.
Code: github.com/mbalesni/synth…
An earlier version of this paper was released in November, but since then we’ve updated many experiments and substantially revised our conclusions.