We have graded the results of @OpenAI's evaluation on FrontierMath...

Epoch AI@EpochAIResearch
120 views
Jul 18, 2025
~1 min read
Advertisement
1
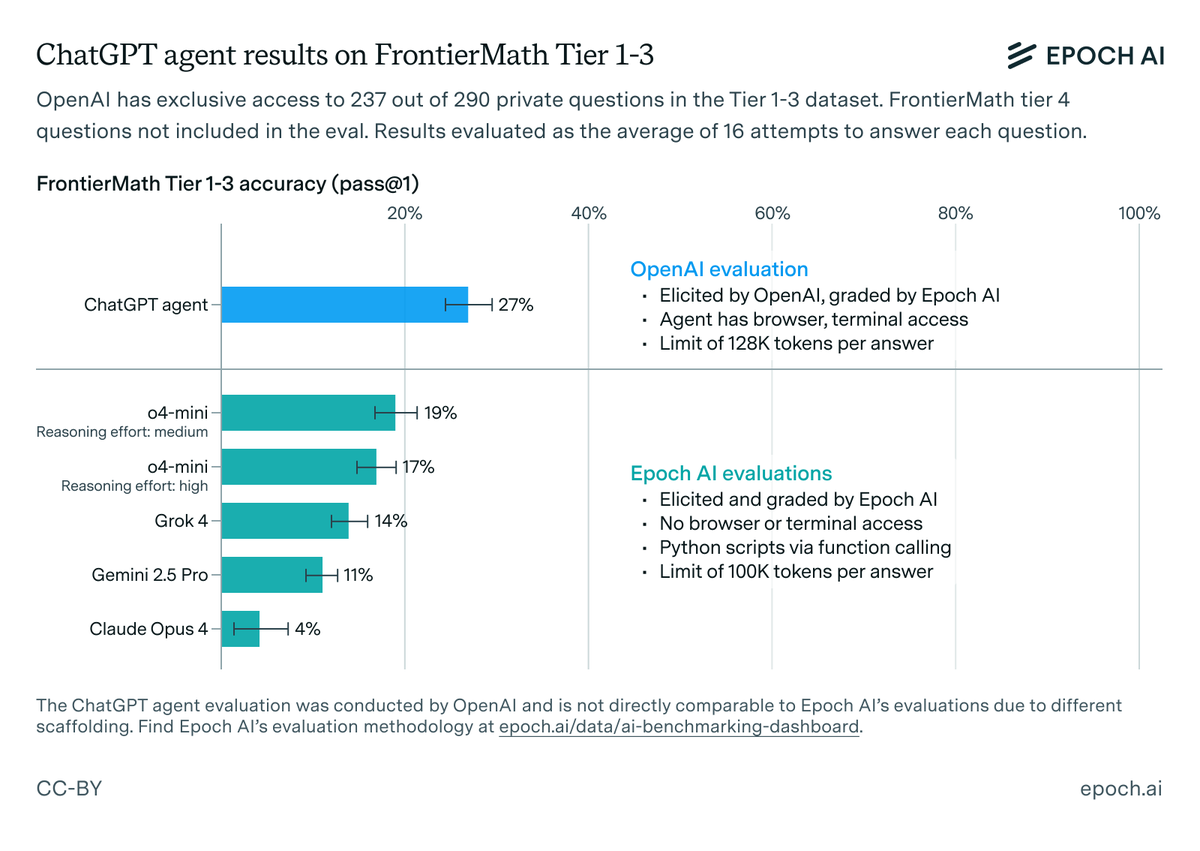
We have graded the results of @OpenAI's evaluation on FrontierMath Tier 1–3 questions, and found a 27% (± 3%) performance. ChatGPT agent is a new model fine-tuned for agentic tasks, equipped with text/GUI browser tools and native terminal access. 🧵
2
This evaluation is not directly comparable to those on Epoch AI’s benchmarking hub, as it uses a different scaffold. First, we did not run the model ourselves—we only graded the outputs provided by OpenAI and don’t have access to their code to run the model. Second, ChatGPT agent has access to tools not available to other models we've assessed—most notably browser tools, which may have helped on questions related to recent research papers. Finally, the evaluation allowed up to 128K tokens per question, compared to our standard 100K; this difference is unlikely to have significantly affected results.
3
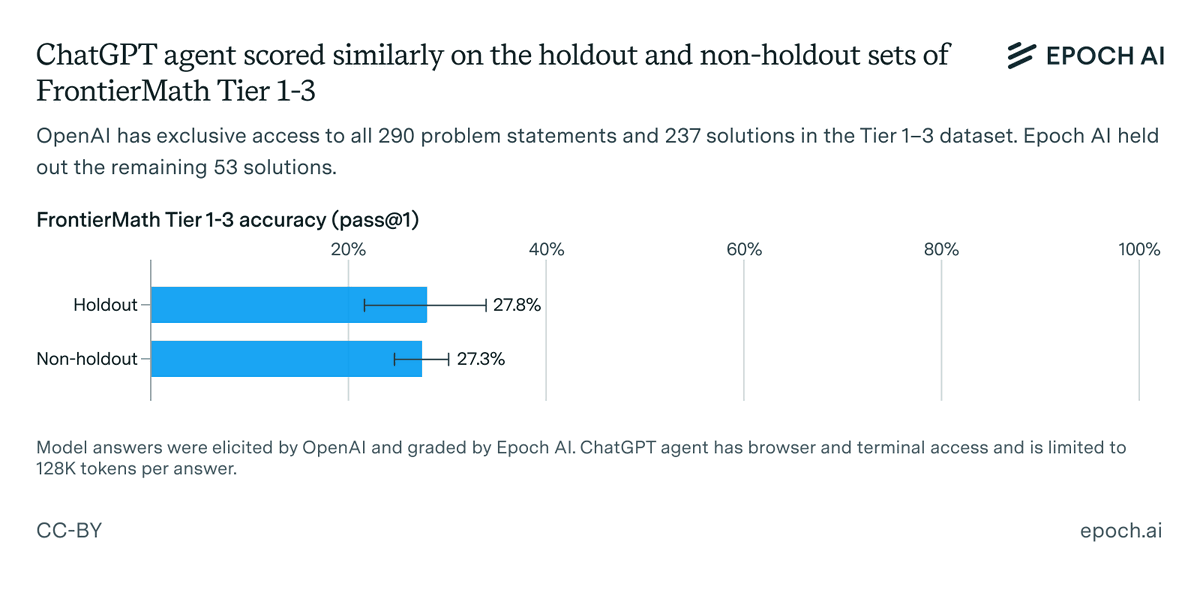
@OpenAI OpenAI has exclusive access to all FrontierMath problem statements and 237 of the 290 Tier 1–3 solutions. Epoch AI holds out the remaining solutions. We found no statistically significant performance difference between the held-out and non-held-out sets.
4
@OpenAI The higher the difficulty tier, the lower ChatGPT agent's score. Still, it solves many problems across all three tiers. This suggests an imperfect but positive correlation between what mathematicians find difficult and the questions that are harder for ChatGPT agent to solve.

5
@OpenAI We also found that, when allowed 16 tries per problem, ChatGPT agent’s score grew from 27% to 49% on the tier 1-3 set. This suggests that better prompting or scaffolding might result in better performance from current models.

6
@OpenAI We will continue evaluating new frontier models on FrontierMath. Check our website for new updates!
epoch.ai/frontiermath
epoch.ai/frontiermath
