LLM RL code does not need to be complicated! Here is a minimal...

Kevin Frans@kvfrans
11 views
Jul 10, 2025
~1 min read
Advertisement
1
LLM RL code does not need to be complicated! Here is a minimal implementation of GRPO/PPO on Qwen3, from-scratch in JAX in around 400 core lines of code.
The repo is designed to be hackable and prioritize ease-of-understanding for research: github.com/kvfrans/lmpo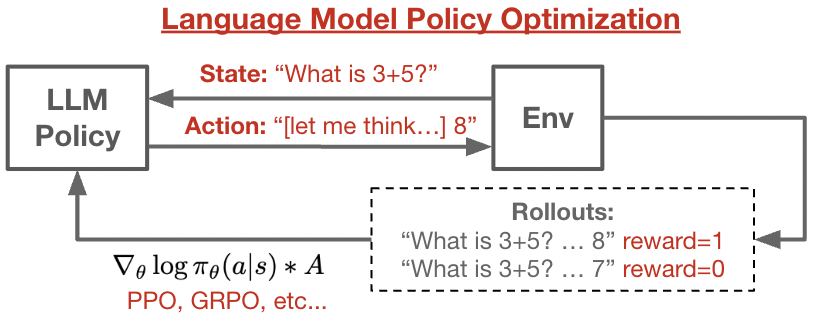
The repo is designed to be hackable and prioritize ease-of-understanding for research: github.com/kvfrans/lmpo
2
The main goal here was to minimize external dependencies, so the model + sampling code is all there to read.
The only thing I couldn't figure out how to replicate is the HF tokenizer, if anyone knows how, please let me know...
The only thing I couldn't figure out how to replicate is the HF tokenizer, if anyone knows how, please let me know...
3
- Everything is JIT compiled, so training is decently fast, but probably not quite as efficient as e.g. vllm sampling backend.
- Multi-host and FSDP sharding works out of the box (single-host works fine too)
- Only bandit environments for now.
- Multi-host and FSDP sharding works out of the box (single-host works fine too)
- Only bandit environments for now.
4
There's a small section in the README giving an overview of typical LLM RL systems. In general, it's the same as a classical RL loop, except we need to put extra care about policy sampling since that's the main compute bottleneck