How much do LLMs memorize? Meta and collaborators suggest that they...

elvis@omarsar0
26 views
Jun 08, 2025
~2 min read
Advertisement
1
How much do LLMs memorize?
Meta and collaborators suggest that they can estimate model capacity by measuring memorization.
"Models in the GPT family have an approximate capacity of 3.6 bits-per-parameter."
Once capacity fills, generalization begins!
More in my notes below:
Meta and collaborators suggest that they can estimate model capacity by measuring memorization.
"Models in the GPT family have an approximate capacity of 3.6 bits-per-parameter."
Once capacity fills, generalization begins!
More in my notes below:
2
Paper Overview
It introduces a novel framework to quantify how much information an LLM memorizes about individual datapoints, separate from generalization.
They define model capacity in terms of bits-per-parameter and present a method to measure unintended memorization.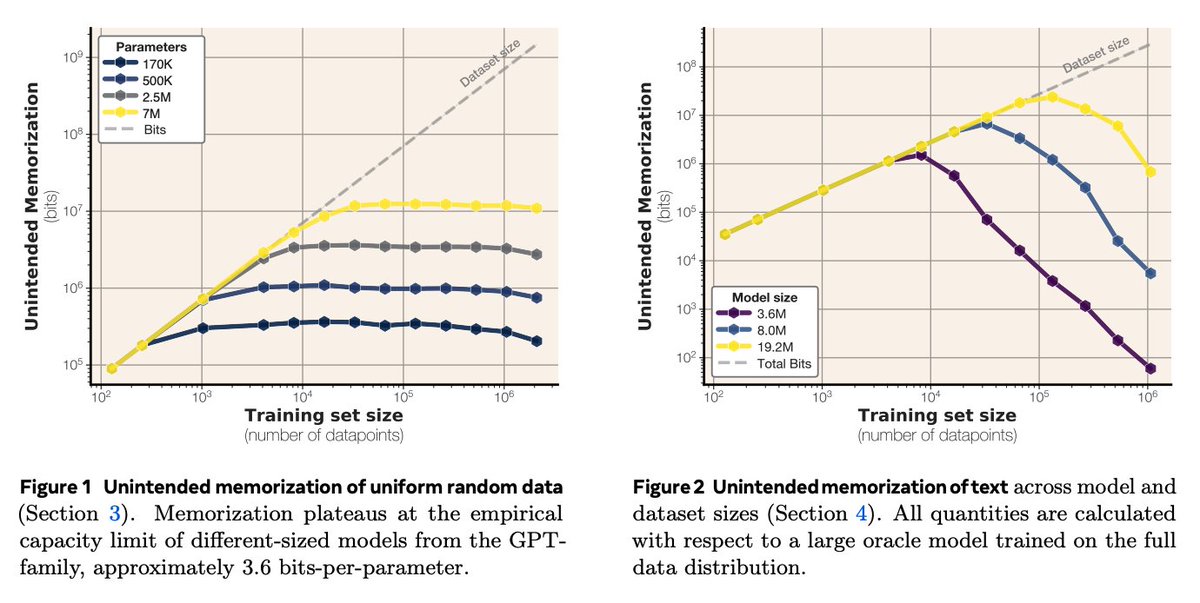
It introduces a novel framework to quantify how much information an LLM memorizes about individual datapoints, separate from generalization.
They define model capacity in terms of bits-per-parameter and present a method to measure unintended memorization.
3
Two-part decomposition of memorization
The paper formalizes unintended memorization (data-specific info) vs. generalization (distribution-level knowledge), and introduces a Kolmogorov-inspired compression-based metric to distinguish them.
The paper formalizes unintended memorization (data-specific info) vs. generalization (distribution-level knowledge), and introduces a Kolmogorov-inspired compression-based metric to distinguish them.
4
GPT capacity = 3.6 bits/parameter
Through training on synthetic datasets with known entropy, the authors determine that GPT-style models trained in bfloat16 consistently memorize 3.5–3.6 bits per parameter, which increases slightly with fp32 precision.
Their results show that GPT-family models can store about 3.6 bits-per-parameter, and propose scaling laws to predict memorization and membership inference.
Through training on synthetic datasets with known entropy, the authors determine that GPT-style models trained in bfloat16 consistently memorize 3.5–3.6 bits per parameter, which increases slightly with fp32 precision.
Their results show that GPT-family models can store about 3.6 bits-per-parameter, and propose scaling laws to predict memorization and membership inference.
5
Double descent and grokking
As training data exceeds model capacity, models stop memorizing and begin to generalize, a transition coinciding with double descent in test loss.
This supports the idea that generalization kicks in once memorization saturates.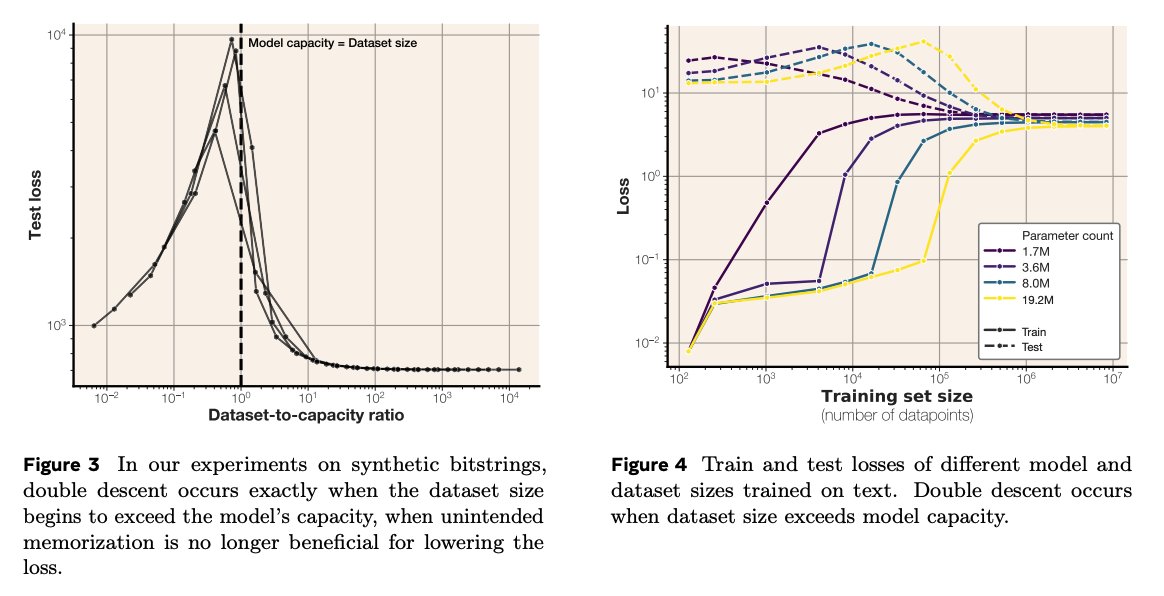
As training data exceeds model capacity, models stop memorizing and begin to generalize, a transition coinciding with double descent in test loss.
This supports the idea that generalization kicks in once memorization saturates.
6
Scaling laws for membership inference
The authors empirically derive a sigmoidal scaling law for membership inference performance as a function of capacity-to-data ratio.
As the dataset size grows, inference accuracy drops to chance (F1 ~ 0.5), explaining why large models trained on huge corpora are resilient to this attack.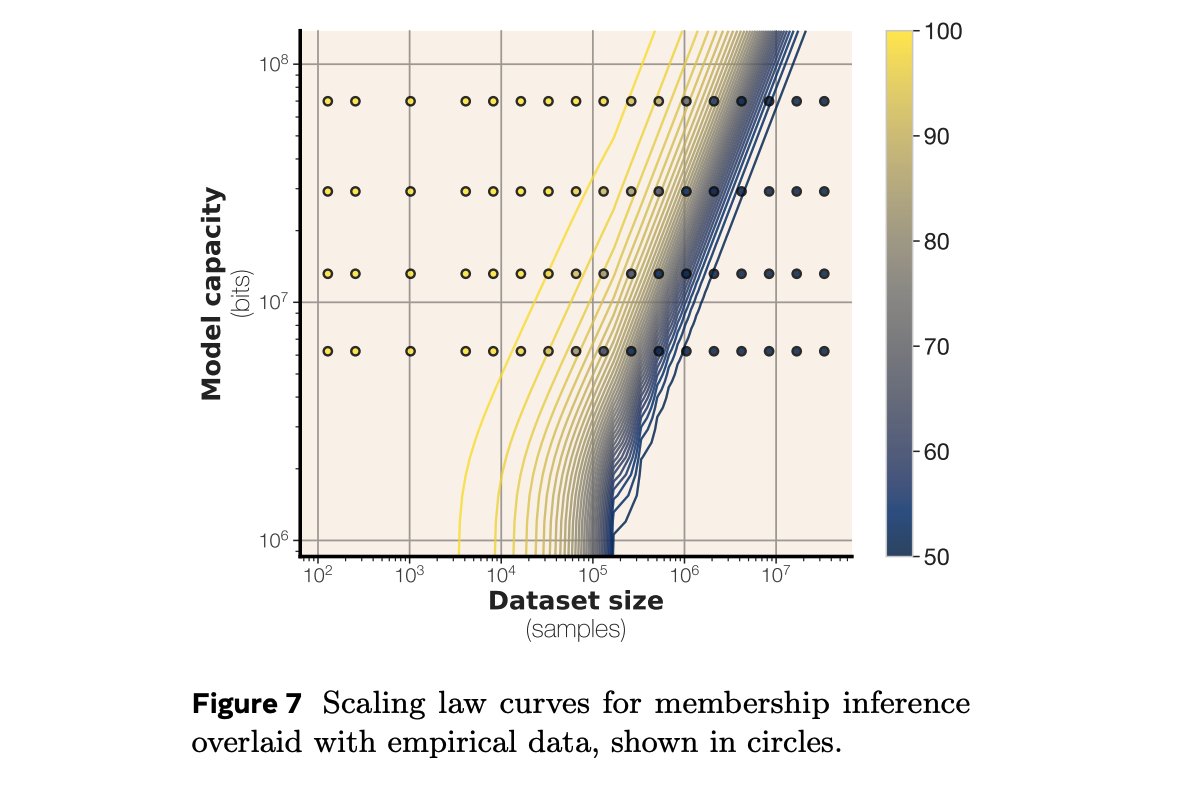
The authors empirically derive a sigmoidal scaling law for membership inference performance as a function of capacity-to-data ratio.
As the dataset size grows, inference accuracy drops to chance (F1 ~ 0.5), explaining why large models trained on huge corpora are resilient to this attack.
7
Rare tokens correlate with memorization
On real text, highly memorized datapoints often contain rare words or languages (e.g., Japanese, Hebrew).
This was measured using TF-IDF vs. memorization scores, indicating models are more likely to memorize outliers in the dataset.
On real text, highly memorized datapoints often contain rare words or languages (e.g., Japanese, Hebrew).
This was measured using TF-IDF vs. memorization scores, indicating models are more likely to memorize outliers in the dataset.
8
Membership inference is easier than extraction
Even when extraction fails, models can still exhibit detectable membership bias via loss differences, especially when trained on small datasets.
The paper also shows that extraction success converges to test-level generalization as datasets grow large.
Overall, the authors measured the capacity of modern transformer language models and analyzed how measurements such as extraction and F1 score scale with model and dataset size.
Paper: arxiv.org/abs/2505.24832
Even when extraction fails, models can still exhibit detectable membership bias via loss differences, especially when trained on small datasets.
The paper also shows that extraction success converges to test-level generalization as datasets grow large.
Overall, the authors measured the capacity of modern transformer language models and analyzed how measurements such as extraction and F1 score scale with model and dataset size.
Paper: arxiv.org/abs/2505.24832