Preprint out today that tests o1-preview's medical reasoning...

Adam Rodman@AdamRodmanMD
9 views
May 21, 2025
~3 min read
Advertisement
1
Preprint out today that tests o1-preview's medical reasoning experiments against a baseline of 100s of clinicians.
In this case the title says it all:
Superhuman performance of a large language model on the reasoning tasks of a physician
Link: arxiv.org/abs/2412.10849
A 🧵⬇️
In this case the title says it all:
Superhuman performance of a large language model on the reasoning tasks of a physician
Link: arxiv.org/abs/2412.10849
A 🧵⬇️
2
This is the FIRST TIME I have promoted one of our preprints (rather than the full peer-reviewed study) so caveat emptor. But I truly think our results have implications for medical practice so I wanted to get them out as quickly as possible.
3
So the experiment: using o1-preview, we recreated five published experiments with human and GPT-4 baselines. Each investigates different parts of how doctors make medical decisions and was graded by human experts.

4
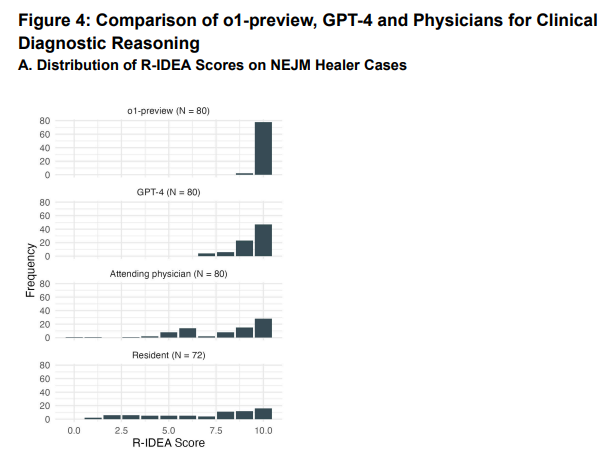
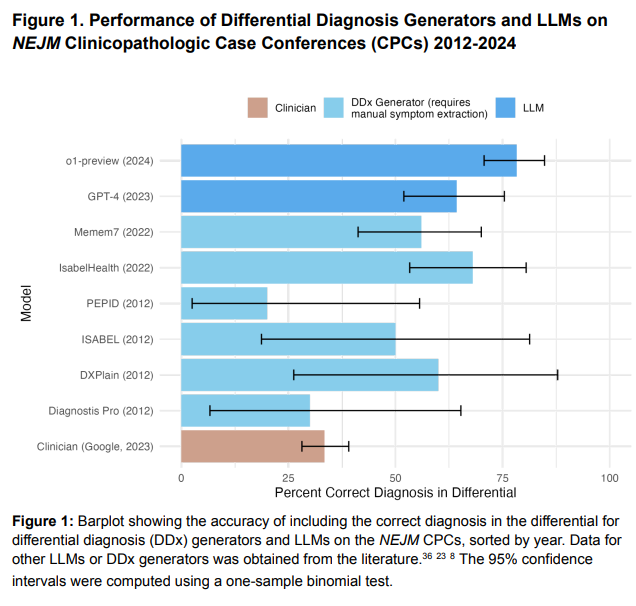
You can read the preprint for the full details but TL;DR -- in ALMOST every domain, o1 bested the other models. And it FAR outclassed humans.
5
This chart is the one that really freaks me out.
These are "no right answer" management cases designed by 25 different specialists to be as difficult as possible.
Humans appropriately struggled. But o1 – you don't need statistics to see how well it performed.
These are "no right answer" management cases designed by 25 different specialists to be as difficult as possible.
Humans appropriately struggled. But o1 – you don't need statistics to see how well it performed.
6
Now the limitations, since this is a Twitter thread. This is a BENCHMARKING study. While these are "gold standard" evaluations of reasoning that we use for human clinicians, these are obviously not actual medical care. Do not get rid of your doctor in favor of o1.
7
And second, it's not even a complete benchmark of reasoning. There are many other cognitive tasks involved in clinical reasoning -- including (very importantly) collecting and organizing data, something that *we* did for the humans and AI in these experiments.

8
Ours is concordant with other benchmarking studies on o1 in medicine, which show improved ability to do well on multiple choice question tasks (though I'm not sure that MEANS anything) as well as other non-medical domains.
x.com/omarsar0/statu…
x.com/omarsar0/statu…
9
So what are the important implications?
The first is that we have reached benchmark saturation with LLMs in medical reasoning. We spent 100s of physician hours developing and grading these benchmarks and for $20 a month an AI model crushes them.
The first is that we have reached benchmark saturation with LLMs in medical reasoning. We spent 100s of physician hours developing and grading these benchmarks and for $20 a month an AI model crushes them.
10
As @emollick has pointed out, there is an urgent need for more and more meaningful benchmarks, especially as LLM technologies are being deployed clinically with little oversight (which, you know, I have opinions about: nejm.org/doi/full/10.10…)
11
We're actually lucky in medicine -- as a self regulating profession, we have organizations like @AmerMedicalAssn, @ABIMcert (and other boards), and @AAMCtoday who set standards -- effectively benchmarks -- for HUMAN doctors to protect patients.

Ethan Mollick@emollick
I really wish there was more interest in benchmarking AI models on real tasks.
The fact that there are not 30 different benchmarks from different organizations in medicine, in law, in advice quality, etc. is a real shame, as people are using systems for these things, regardless.
The fact that there are not 30 different benchmarks from different organizations in medicine, in law, in advice quality, etc. is a real shame, as people are using systems for these things, regardless.
12
Could our societies also set standards for reasoning LLMs? I don't think it's much of a stretch, and no one else is doing it.
And the second implication -- it's time for clinical trials.
And the second implication -- it's time for clinical trials.
13
Don't get me wrong. Benchmarking is important, especially as a hypothesis generating tool for what tasks LLMs might be helpful for (which is why MCQ benchmarks make my eyes roll back into my head -- that is not a meaningful task in any universe)
14
But we know how to test efficacy in medicine. Clinical trials are messy, more expensive than in silico studies, and require multidisciplinary expertise. But they're still the right thing to do. Only 5% of LLM in medicine studies even use real data (pubmed.ncbi.nlm.nih.gov/39405325/)!!
15
I have a lot of other thoughts but that is for later 😃Many thanks to my colleagues/co-authors at the ARiSE research network (med.stanford.edu/hospitalmedici…) who put this study together, and especially @tabuckley_ and Peter Brodeur who did the heavy lifting.
16
(an exhaustive list: @zahirkanjee @drethangoh Evelyn Bin Ling, @Pr1yankJa1n, @stephcabral_ @BageLeMage @ADHaimo @FreedoBaggins @andrewolsonmd @dr_dmorgan Jason Hom, @robjgallo @erichorvitz, ARiSE co-conspirator @jonc101x, and finally lab partner @arjunmanrai!)
17
...
18
@caseyjkim re: one-liners (aka problem representations) @stephcabral_ did that study! And it's the second experiment in this paper. TL;DR -- AI is much better than people at this task.