Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to...

Claude@claudeai
45 views
Nov 10, 2026
~2 min read
Advertisement
1
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
0:18
2
Fable 5.2 and Mythos 5.2 performed as well as, or better than, our recent models on most alignment measures.
The model was also tested before release by external evaluators, including the @AISecurityInst, @FrontierDesign2, and @METR_Evals.
The model was also tested before release by external evaluators, including the @AISecurityInst, @FrontierDesign2, and @METR_Evals.
3
Fable 5.2 and Mythos 5.2 are a step above Opus 5.5 in almost all the capabilities we evaluated.
Testers have found that they communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Fable 5.1 and Mythos 5.1.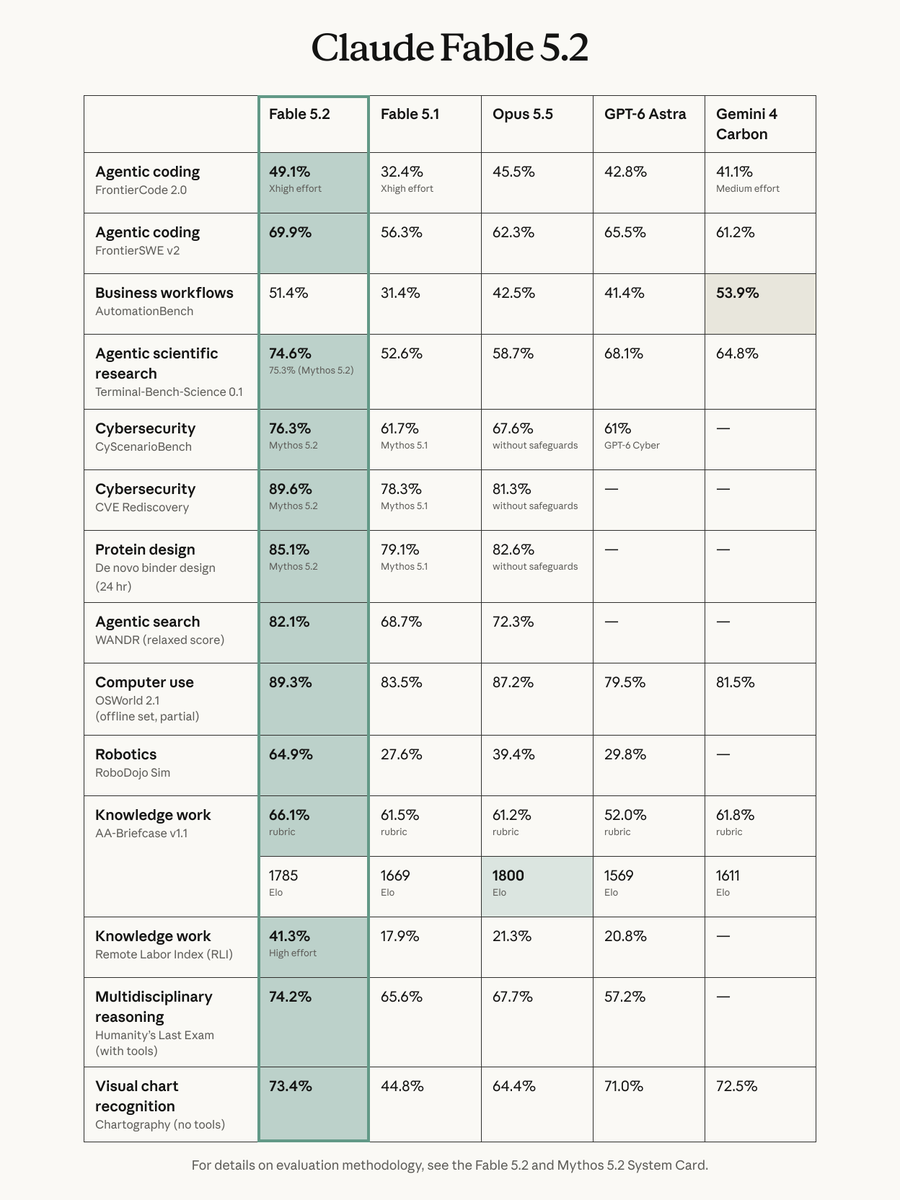
Testers have found that they communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Fable 5.1 and Mythos 5.1.
4
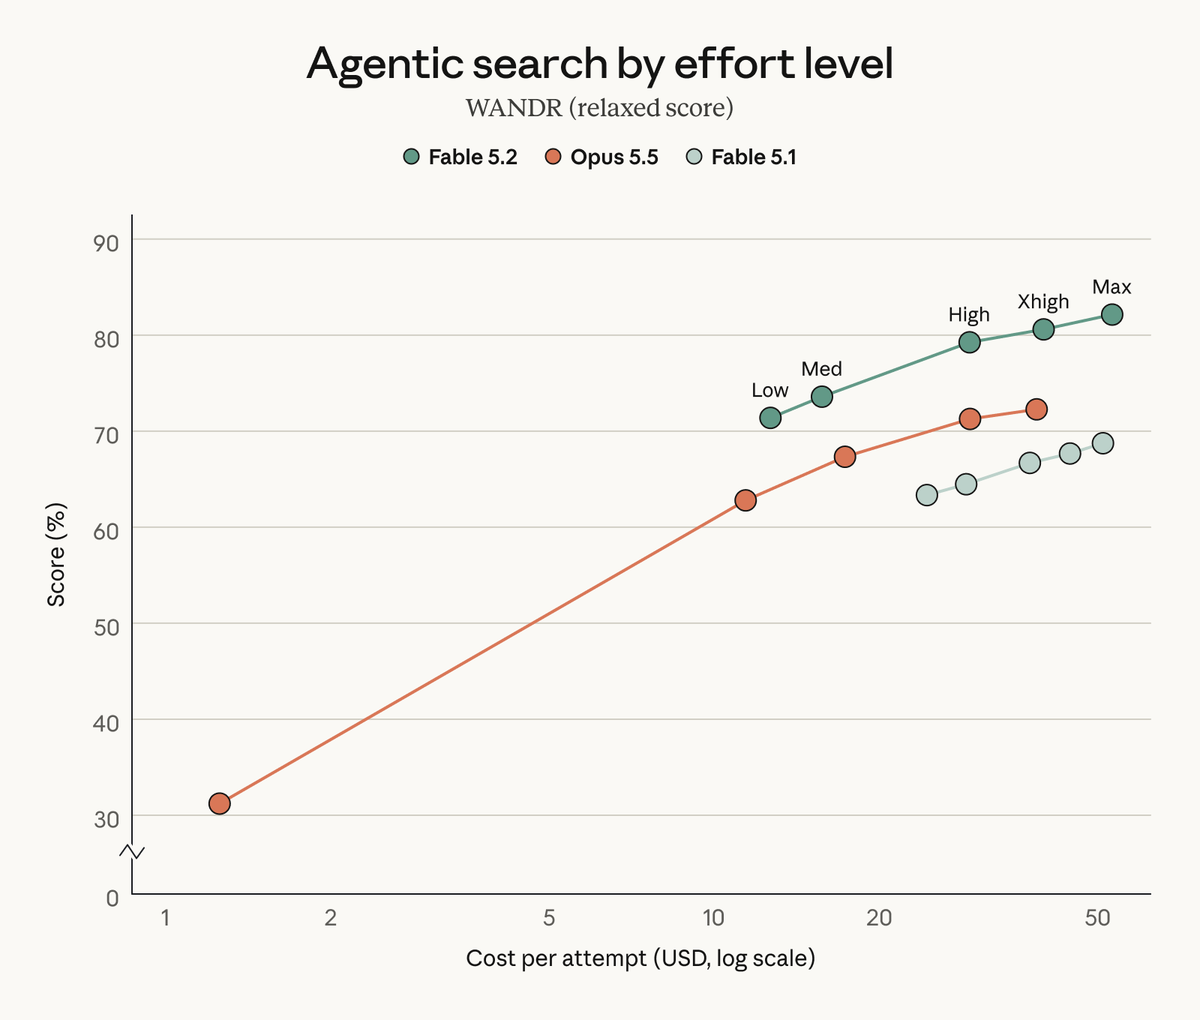
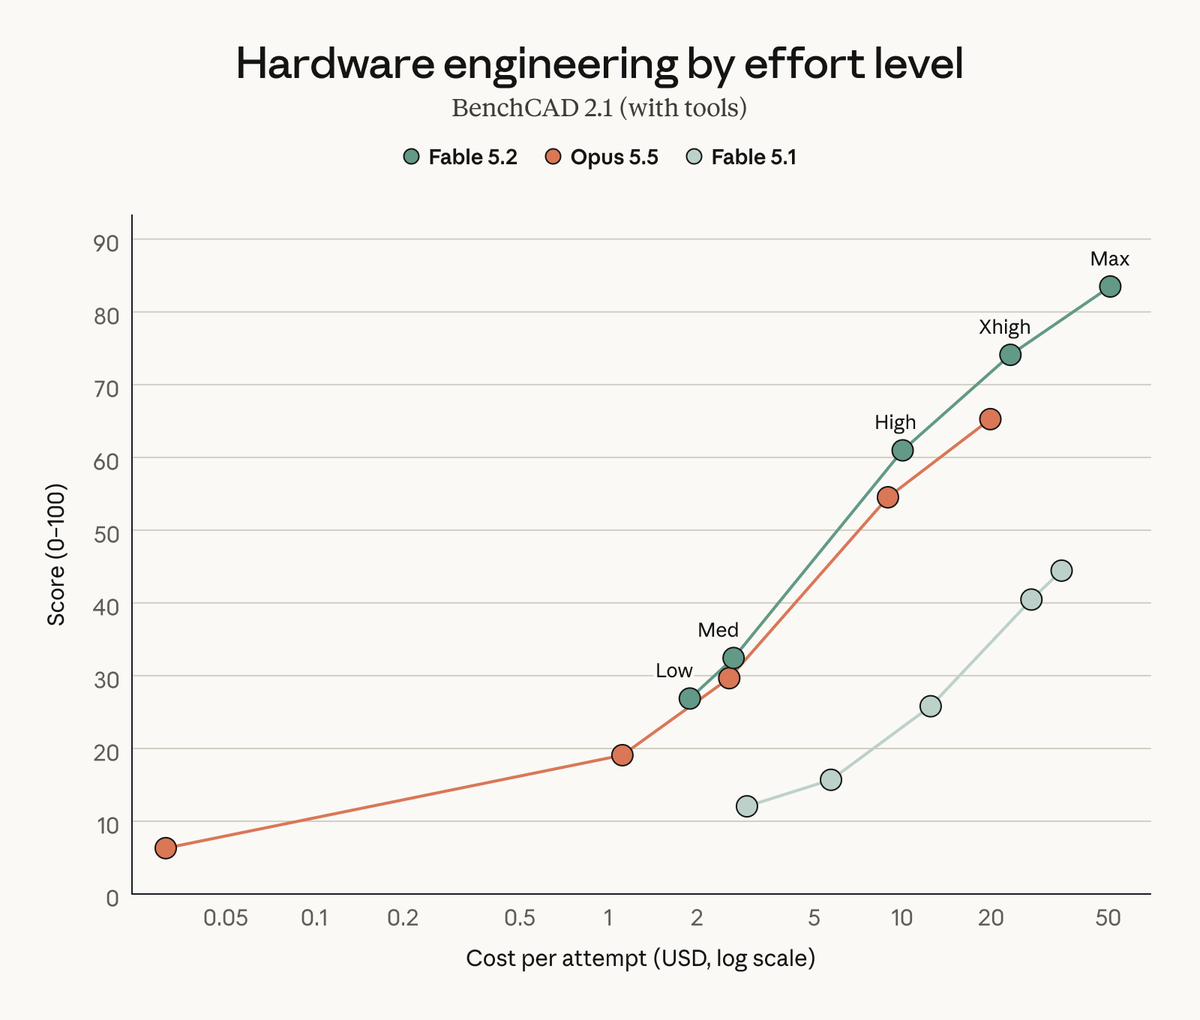
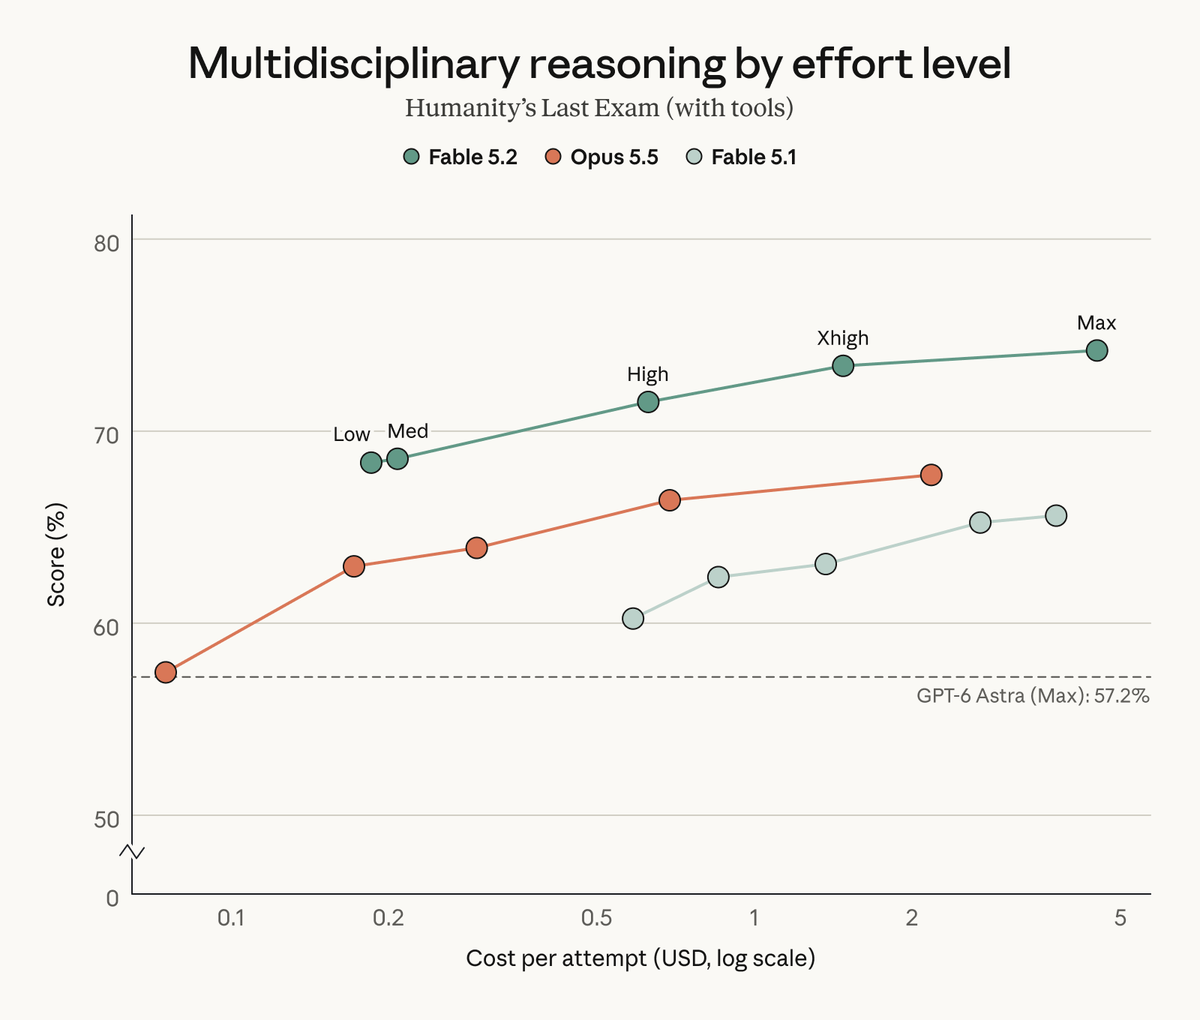
In early testing on FrontierCode 2.0, Fable 5.2 at High effort scored about level with Opus 5.5 at Max effort, for roughly half the cost per task. At Xhigh effort, it scored the highest of any released model tested.
Medium is the default in Claude apps and Claude Code.
Medium is the default in Claude apps and Claude Code.
5
Gene therapies can be delivered in a protein shell called a capsid. Mythos 5.2 found a new way to predict a whole capsid’s structure.
In our tests, it accurately modeled 28 of the 34 capsids it attempted. Biologists could use it to design capsids faster and more cheaply.
In our tests, it accurately modeled 28 of the 34 capsids it attempted. Biologists could use it to design capsids faster and more cheaply.
0:57
6
A team of 1,000 Fable 5.2 agents fully formalized Fermat’s Last Theorem in 30 hours, translating the proof into a language a computer can check step by step.
With the same setup, Opus 5.5 completed only 26% in 18 hours, and barely made any more progress after 30 hours.
With the same setup, Opus 5.5 completed only 26% in 18 hours, and barely made any more progress after 30 hours.
7
Fable 5.2 shows substantially improved skills in controlling physical robots, even on tasks it has never explicitly been trained to do.
On RoboDojo, a benchmark with a simulated two-arm robot, it outperformed other models and most AI systems built to control robots.
On RoboDojo, a benchmark with a simulated two-arm robot, it outperformed other models and most AI systems built to control robots.
0:23
8
Fable and Mythos are best for the most ambitious, open-ended technical work.
For most coding and knowledge tasks, we recommend starting with Opus 5.5, our strongest daily driver, then moving to a different model depending on the scope and complexity of your work.
For most coding and knowledge tasks, we recommend starting with Opus 5.5, our strongest daily driver, then moving to a different model depending on the scope and complexity of your work.
9
Fable and Mythos are the same underlying model. Fable has strong safeguards to guard against misuse.
Organizations pursuing beneficial applications in cybersecurity or biomedical research can apply for Mythos through our Life Sciences and Cyber Verification Programs.
Organizations pursuing beneficial applications in cybersecurity or biomedical research can apply for Mythos through our Life Sciences and Cyber Verification Programs.
10
Claude Fable 5.2 is available today on all paid plans, on the Claude Platform, and on all major cloud platforms.
It’s $8 per million input tokens and $40 per million output tokens, down from $10 and $50.
Read more: anthropic.com/claude-fable-a…
It’s $8 per million input tokens and $40 per million output tokens, down from $10 and $50.
Read more: anthropic.com/claude-fable-a…
