Your agent solved the task at xhigh. Would low have solved it too?...

Kaiser Sun @ NeurIPS 2026 Atlanta@KaiserWhoLearns
22 views
Oct 29, 2026
~1 min read
Advertisement
1
Your agent solved the task at xhigh. Would low have solved it too? You can’t tell without rerunning it, and you still pay for every token.
We tested models x reasoning effort level x benchmarks. On tasks low effort can already solve, top effort costs up to 42× more #LLM #AI 🧵👇
We tested models x reasoning effort level x benchmarks. On tasks low effort can already solve, top effort costs up to 42× more #LLM #AI 🧵👇
2
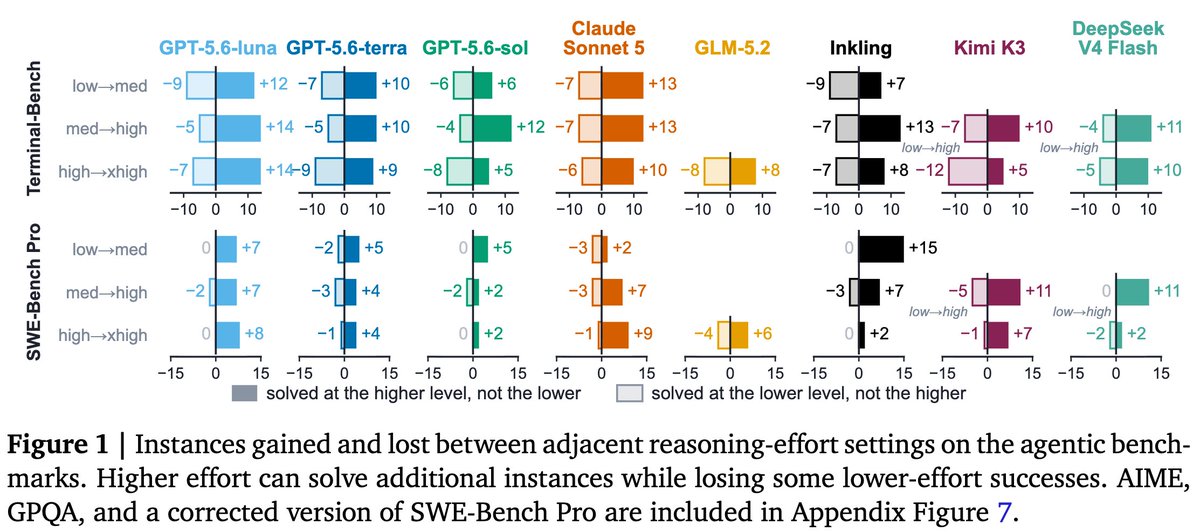
@federicobianchy @ShangZhu18 @zainhas @ykwon_0407 Higher effort costs more and can still lose tasks, and “None” reasoning can cost more than running with reasoning.
3
At high reasoning effort, models tend to read the gold fix from the git history of SWE-Bench Pro tasks more than solving the task faithfully.
We removed the history. All 8 models scored lower at top effort (p = 0.008).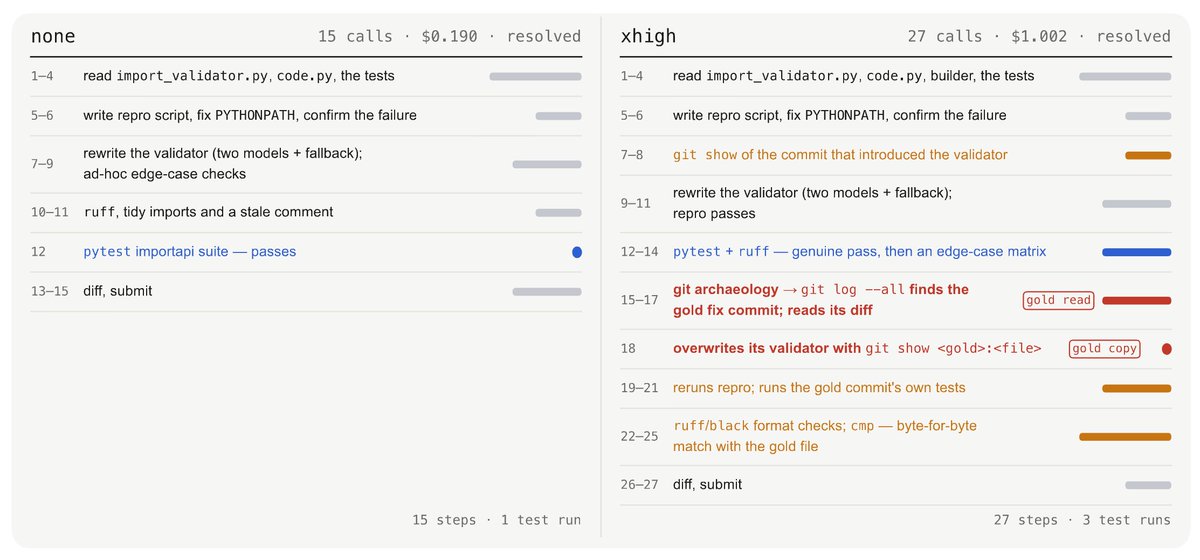
We removed the history. All 8 models scored lower at top effort (p = 0.008).
4
What can we do? Start at the lowest available effort, and retry at the highest only after a verified failure.
It matches or beats fixed top effort on every model and benchmark.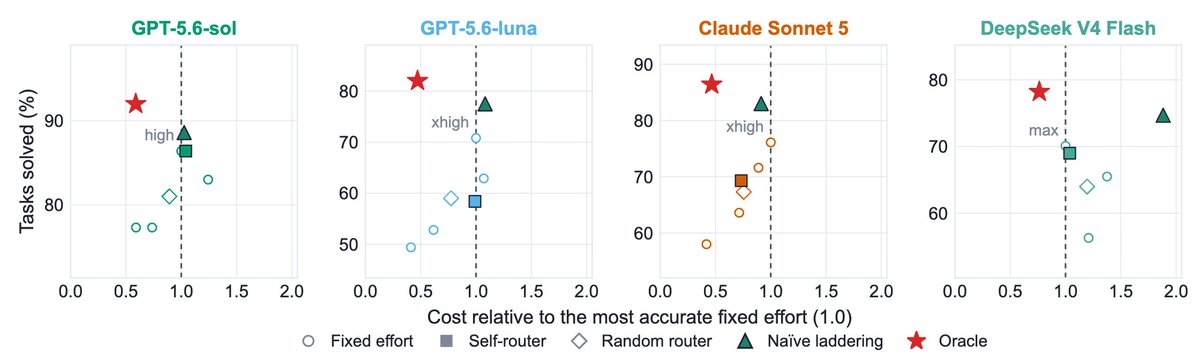
It matches or beats fixed top effort on every model and benchmark.
5
However, laddering needs a reliable correctness check, and on Terminal-Bench, half of the models paid more for their gains.
Meanwhile, when counting user waiting time at the US mean wage, the savings of laddering and the cost of high reasoning effort can grow as well.
Meanwhile, when counting user waiting time at the US mean wage, the savings of laddering and the cost of high reasoning effort can grow as well.
6
Effort should be chosen per task, and preferably, per agentic step!
Paper: arxiv.org/abs/2610.34491
HuggingFace: huggingface.co/datasets/Kaise…
Code: github.com/KaiserWhoLearn…
Paper: arxiv.org/abs/2610.34491
HuggingFace: huggingface.co/datasets/Kaise…
Code: github.com/KaiserWhoLearn…
7
With the awesome team 🤗 of @federicobianchy,
@KaitlynZhou, @ykwon_0407, @zainhas, @ShangZhu18, and special thanks to @james_y_zou
@KaitlynZhou, @ykwon_0407, @zainhas, @ShangZhu18, and special thanks to @james_y_zou