Tinker's new StableReinforce objective is Reinforce + Score...

Martin Marek@mrtnm
9 views
Oct 25, 2026
~2 min read
Advertisement
1
Tinker's new StableReinforce objective is Reinforce + Score Centering. Here's how I reverse-engineered it 🧵

Tinker@tinkerapi
Off-policy RL is difficult; runs can suddenly collapse because of async RL staleness or numerical mismatch.
StableReinforce is a new method on Tinker that keeps your RL runs stable, even when learning drifts from sampling.
tinker-docs.thinkingmachines.ai/tinker/losses/…
StableReinforce is a new method on Tinker that keeps your RL runs stable, even when learning drifts from sampling.
tinker-docs.thinkingmachines.ai/tinker/losses/…
2
Tinker does not expose what the loss function and "stability info" are. However, one thing we can do is take an optimizer step on the loss function, download the updated weights, recover the raw gradients, and reverse-engineer what loss function would generate the same gradients.
Tinker doesn't support SGD, so we use Adam with ϵ=10,000. This value of ϵ dominates Adam's second moment, so Δw ≈ −lr·g/ϵ, i.e. we can recover the raw gradients from the update.
Tinker doesn't support SGD, so we use Adam with ϵ=10,000. This value of ϵ dominates Adam's second moment, so Δw ≈ −lr·g/ϵ, i.e. we can recover the raw gradients from the update.
3
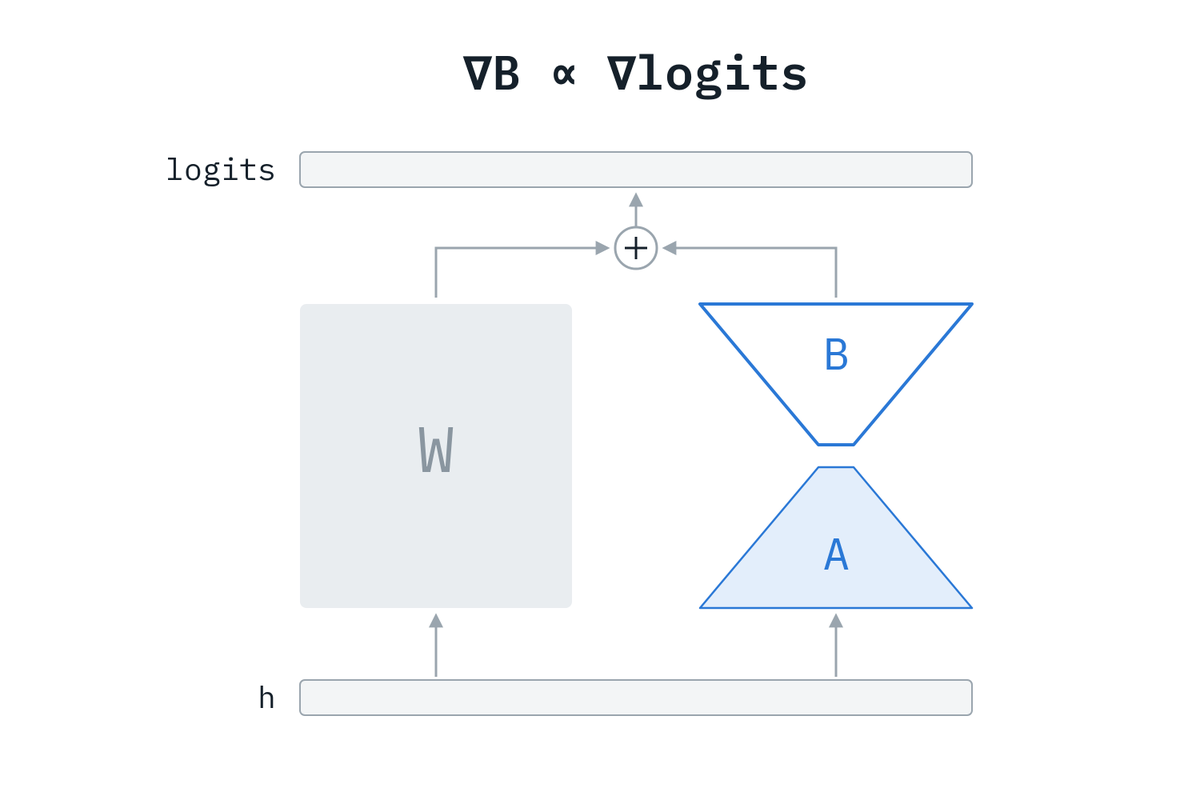
We train a rank-1 LoRA adapter on top of Qwen3.5-4B. Since the LoRA adapter (B · A) for the unembedding matrix is rank-1, the gradient w.r.t. B is equal to the gradient w.r.t. logits (up to a scaling factor). In other words, we can recover the exact logits gradient!
4
Looking at a single-token update, surprisingly only 8 logits have a non-zero gradient. In contrast, a standard Reinforce loss would put a non-zero gradient on all logits.
This observation basically reveals the objective. In Score Centering, we subtract the expected score under the sampler. Since computing the exact expectation is expensive, we have to resort to an approximation. In our paper, we propose a top-k approximation, which is deterministic but slightly biased. It seems that Thinky instead decided to compute the expected score by randomly drawing 8 tokens from the sampler, which is unbiased but higher variance.
Every token’s score has the same dense part (−p, from the softmax), so subtracting the average score over the 8 correction tokens cancels it exactly.
5
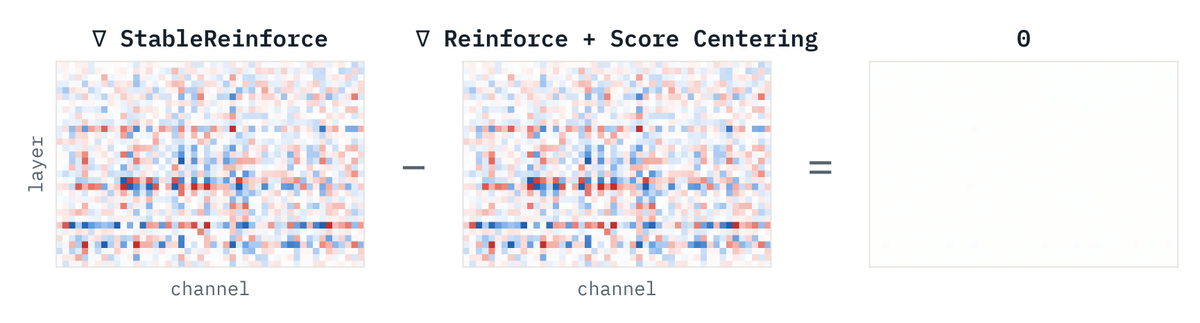
So we have a hypothesis: StableReinforce = Reinforce + Score Centering, where the expected score is computed over 8 randomly sampled tokens. We can easily verify that it is true: we implement Reinforce + SC as a custom loss in Tinker, do an optimizer step, and recover gradients that are within numeric precision of StableReinforce across all layers.
6
On a side note, I'm thrilled Thinky has found Score Centering to be extremely stable! From their docs: "In our internal post-training, this loss function has led to extremely stable training, even under highly off-policy async RL and low precision numerics."
7
Score Centering reference: arxiv.org/abs/2609.20807