Introducing Limite 1B - Violetto. A model for high-frequency...

Paradigma@paradigmainc
17 views
Sep 22, 2026
~1 min read
Advertisement
1
Introducing Limite 1B - Violetto.
A model for high-frequency mathematical intelligence.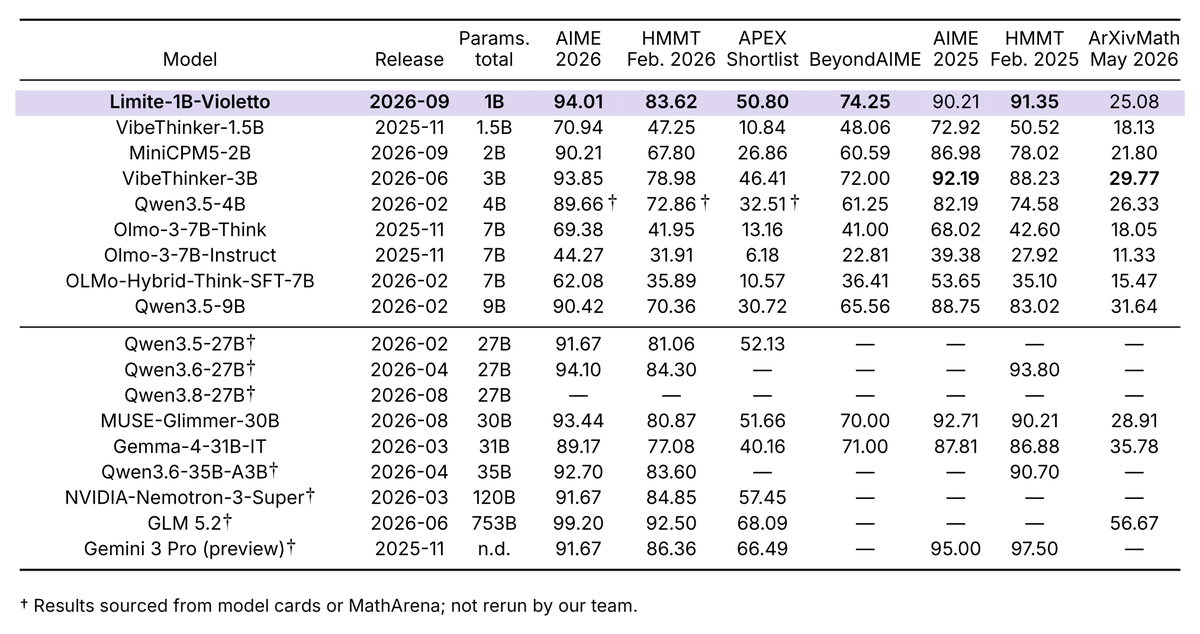
A model for high-frequency mathematical intelligence.
2
Despite its size, Limite can solve hard math problems better than models tens of times larger, and is competitive when compared to recent models with hundreds of billions of parameters.
3
Limite has been trained from scratch on less than 300B tokens, almost fully on math, and leverages an architecture inspired by recent advancements brought forth by the nanogpt speedrun competitions.
4
When comparing capability per training FLOPs, Limite is orders of magnitude more efficient than existing models.

5
Limite is post-trained to be as lightly instruction-tuned as possible, to challenge the assumption that models need to be embedded in an assistant persona to function well. As a result, the model is designed to be used to respond in single turns, with an extremely high mathematical capability per parameter.
6
Limite is also designed to be a high-frequency, high-throughput solver in multi-agent systems. In the upcoming technical report, we will detail how to leverage this, and will release an accompanying harness, Rainfall.
7
We release Limite under a permissive Apache 2.0 License, alongside its base model, scoring 59,80% on MATH-500 in few-shot evaluation, and the Value model we used in the last phases of post-training.
8
Limite is our first model, trained in just 6 weeks from our first experiments at the beginning of August. We have learned a tremendous amount in the process, and can’t wait to share with you our learnings in the upcoming technical report. This is just the beginning.
9
Blogpost: paradigma.inc/blog/limite-1b…
Github: github.com/paradigma-inc/…
Model Weights: huggingface.co/paradigma-inc/…
A detailed technical report is coming soon.
Github: github.com/paradigma-inc/…
Model Weights: huggingface.co/paradigma-inc/…
A detailed technical report is coming soon.