Incredible writeup! Some notable 💎s: Deepseek reduced attention...

Susan Zhang@suchenzang
28 views
Dec 02, 2025
~1 min read
Advertisement
1
Incredible writeup! Some notable 💎s:
Deepseek reduced attention complexity from quadratic to ~linear through warm-starting (w/ separate init + opt dynamics) and adapting the change over ~1T tokens.
They also use separate attention modes for disaggregated prefill vs decode (is this the first public account of arch difference between the two? 👀).
1/🧵
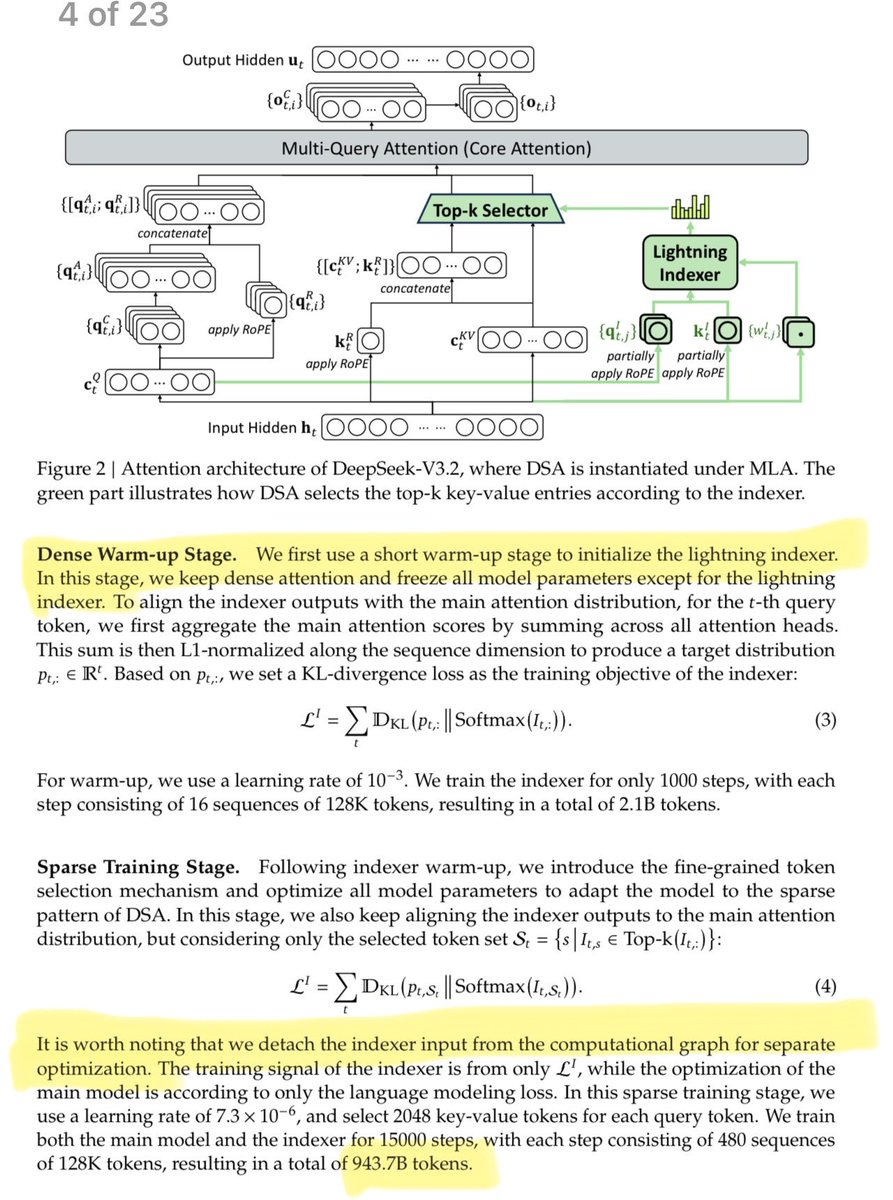
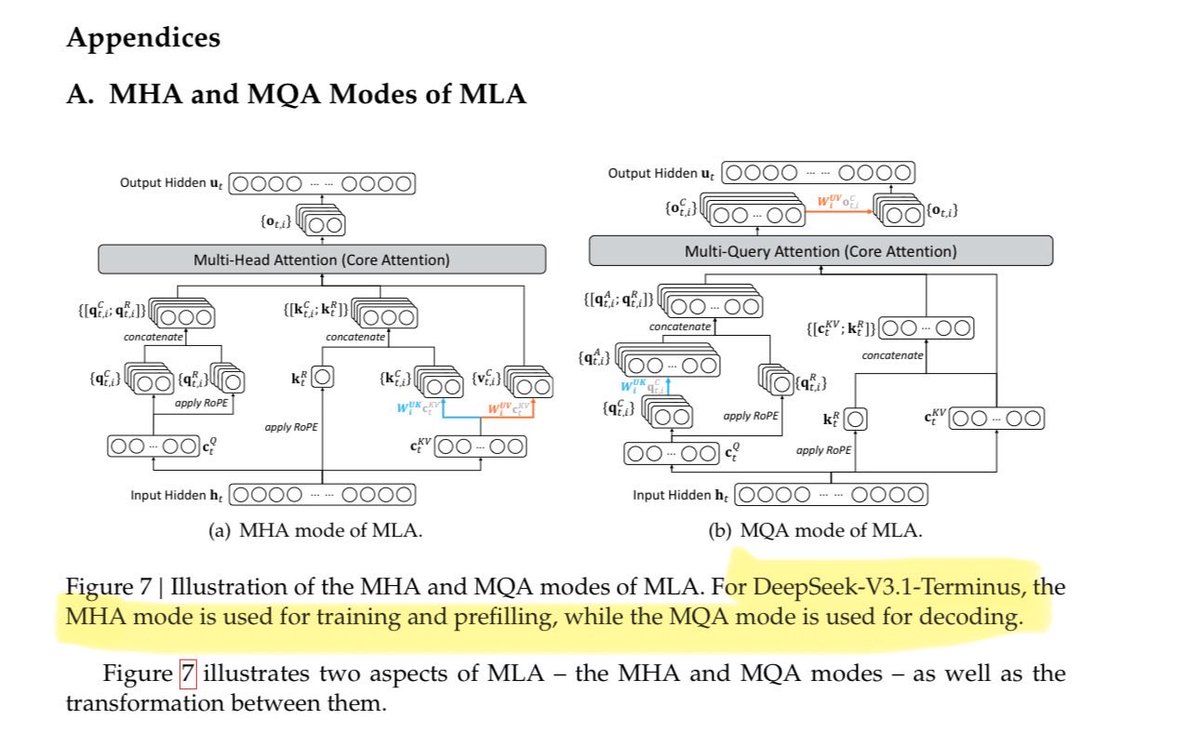
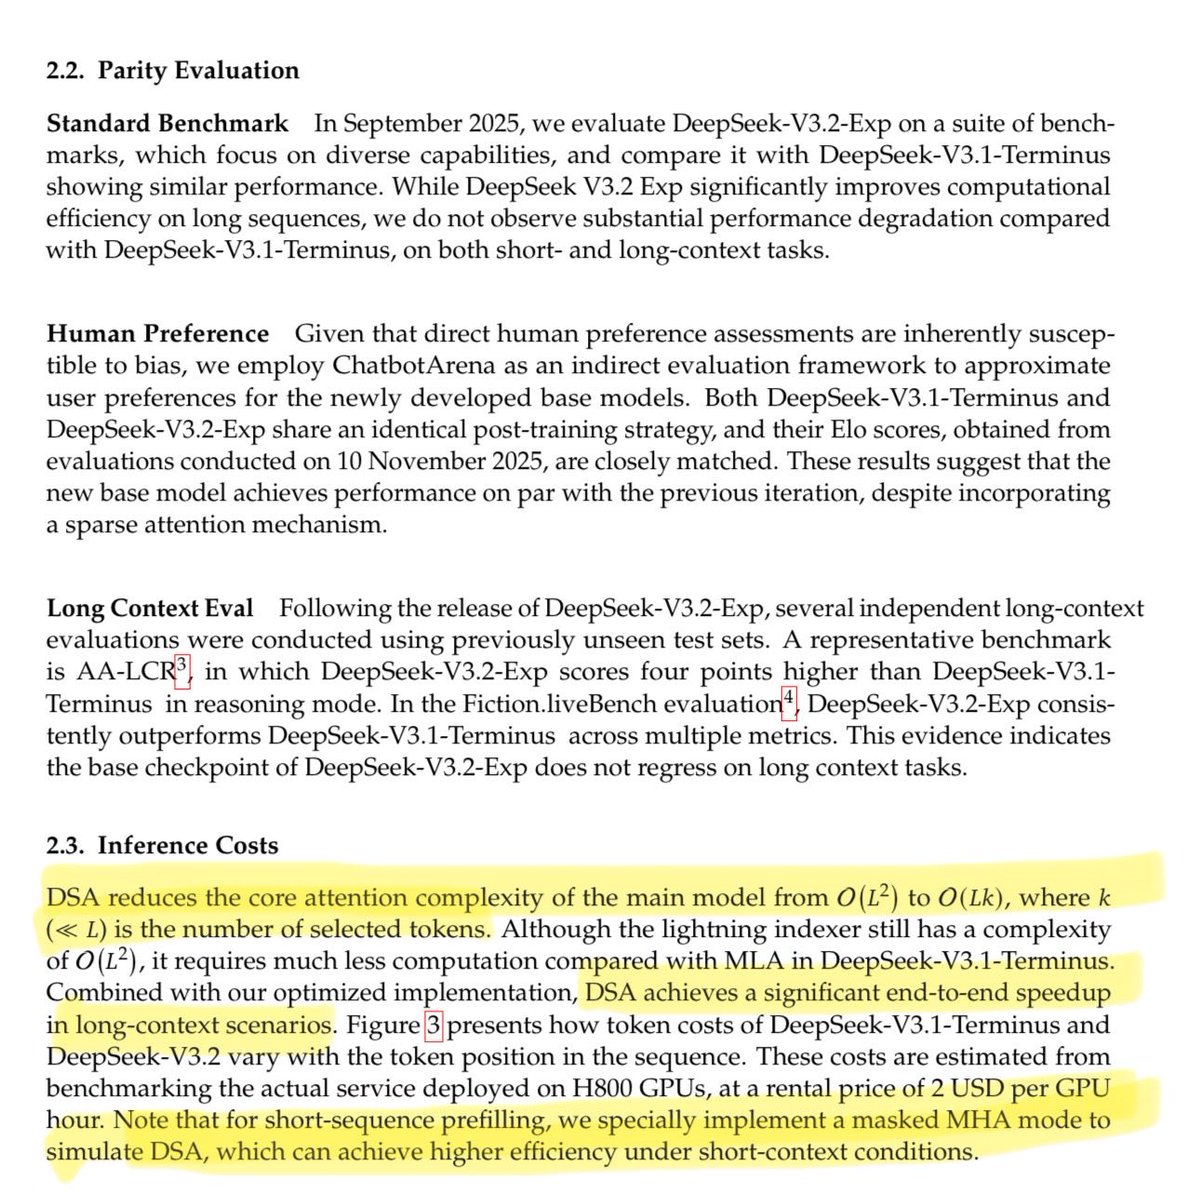

Deepseek reduced attention complexity from quadratic to ~linear through warm-starting (w/ separate init + opt dynamics) and adapting the change over ~1T tokens.
They also use separate attention modes for disaggregated prefill vs decode (is this the first public account of arch difference between the two? 👀).
1/🧵
DeepSeek@deepseek_ai
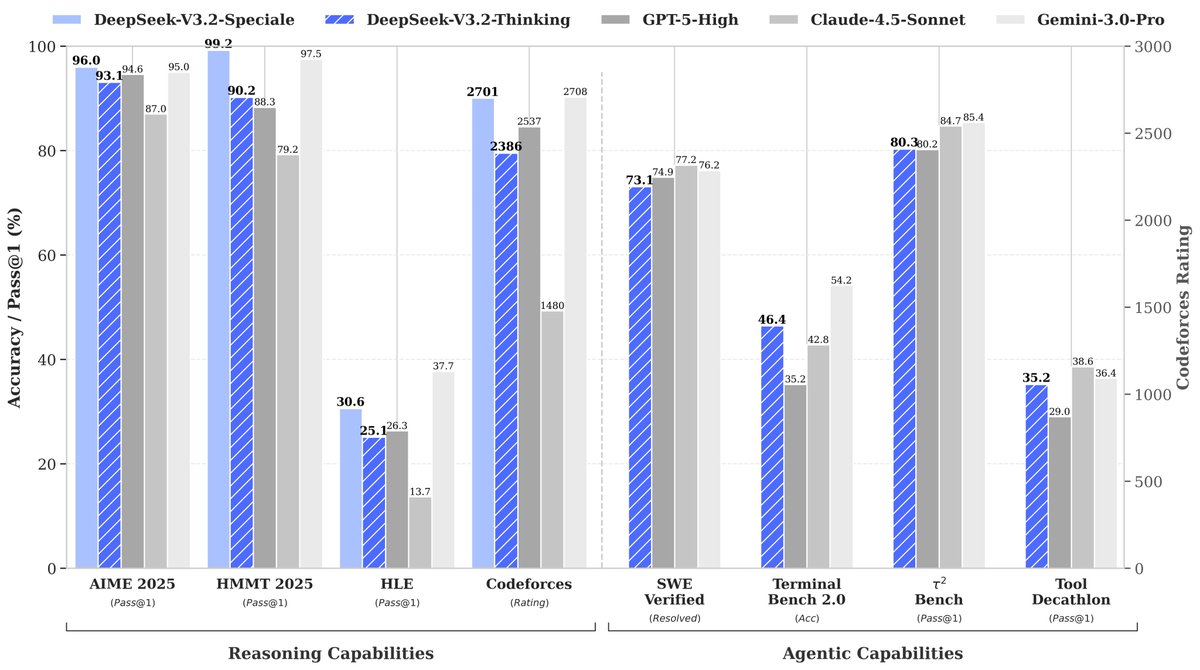
🚀 Launching DeepSeek-V3.2 & DeepSeek-V3.2-Speciale — Reasoning-first models built for agents!
🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API.
🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now.
📄 Tech report: huggingface.co/deepseek-ai/De…
1/n
🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API.
🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now.
📄 Tech report: huggingface.co/deepseek-ai/De…
1/n
2
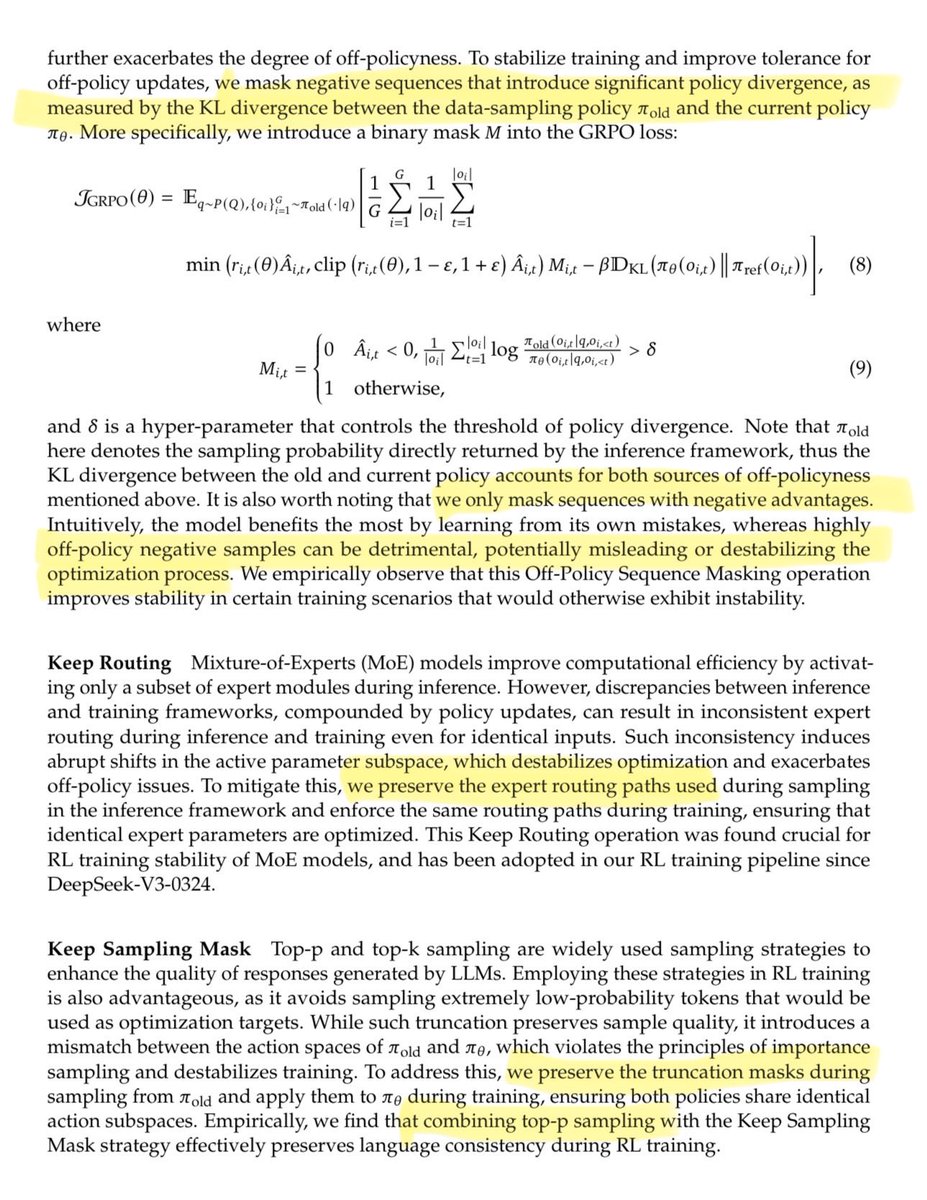
They also make several innovations to stabilize RL training (far beyond what that other "open bell labs" place published in blog posts 👀):
1) unbiased kl estimate, with different kl reg for different domains (!)
2) mask significantly negative adv sequences (to not "throw off" the model)
3) fix real-world training/inference mismatch issues with MoEs between different frameworks (preserve expert routing + preserve top-p sampling masks)
2/🧵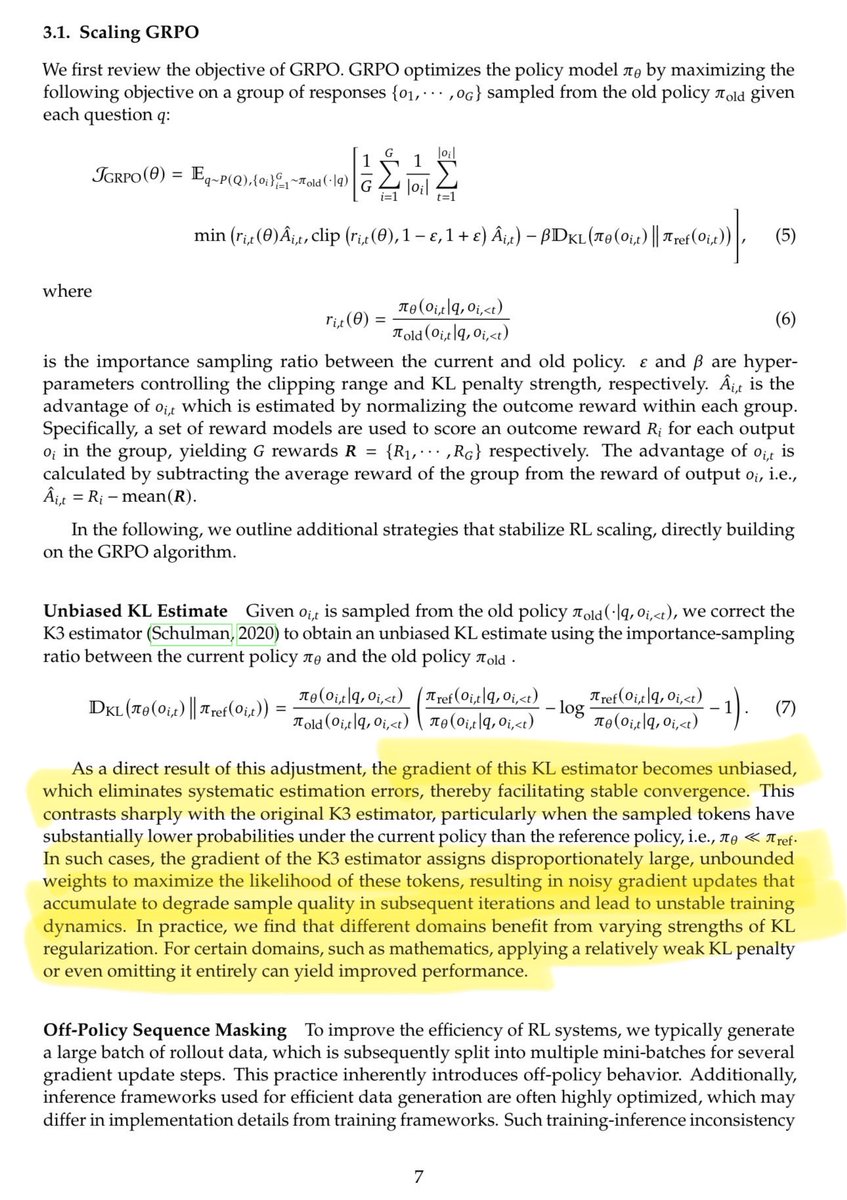
1) unbiased kl estimate, with different kl reg for different domains (!)
2) mask significantly negative adv sequences (to not "throw off" the model)
3) fix real-world training/inference mismatch issues with MoEs between different frameworks (preserve expert routing + preserve top-p sampling masks)
2/🧵
3
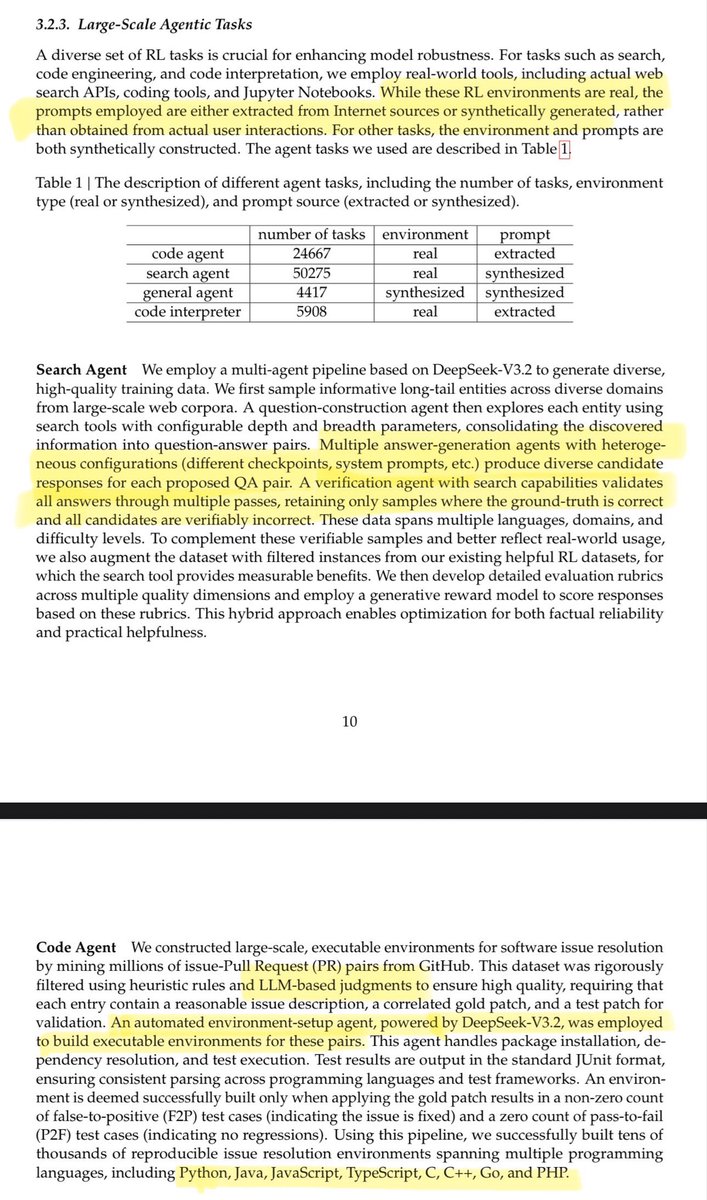
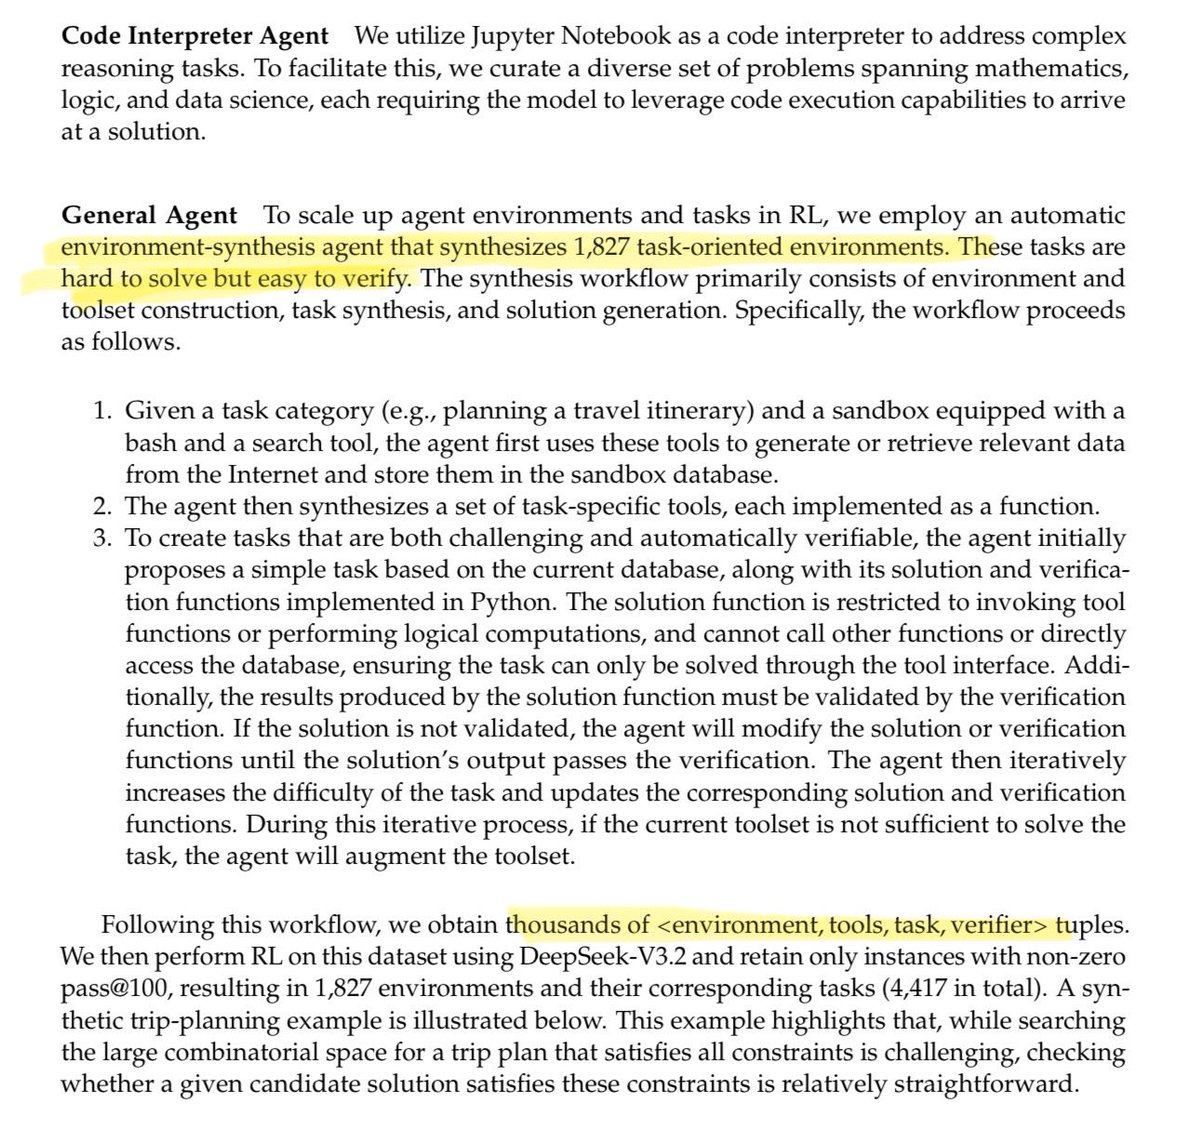
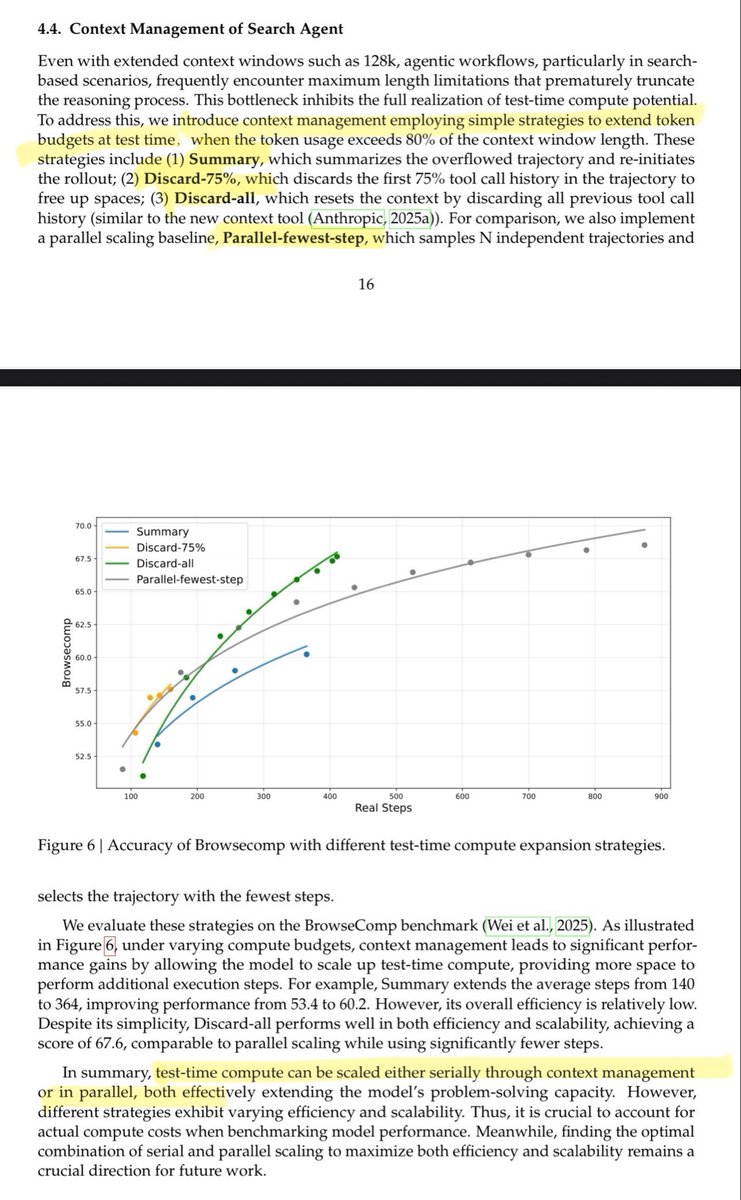
The most noteworthy bit may be around how they scaled "agentic" capabilities:
1) context management plus more context management
2) diversity of "agent configurations" (different checkpoints, system prompts)
3) scaling task/environment creation, yielding thousands of < env, tool, task, verifier > tuples
For (3), they show a noticeable saner delineation of these 4 categories than a current fan-favorite decentralized AI player... 👀
3/🧵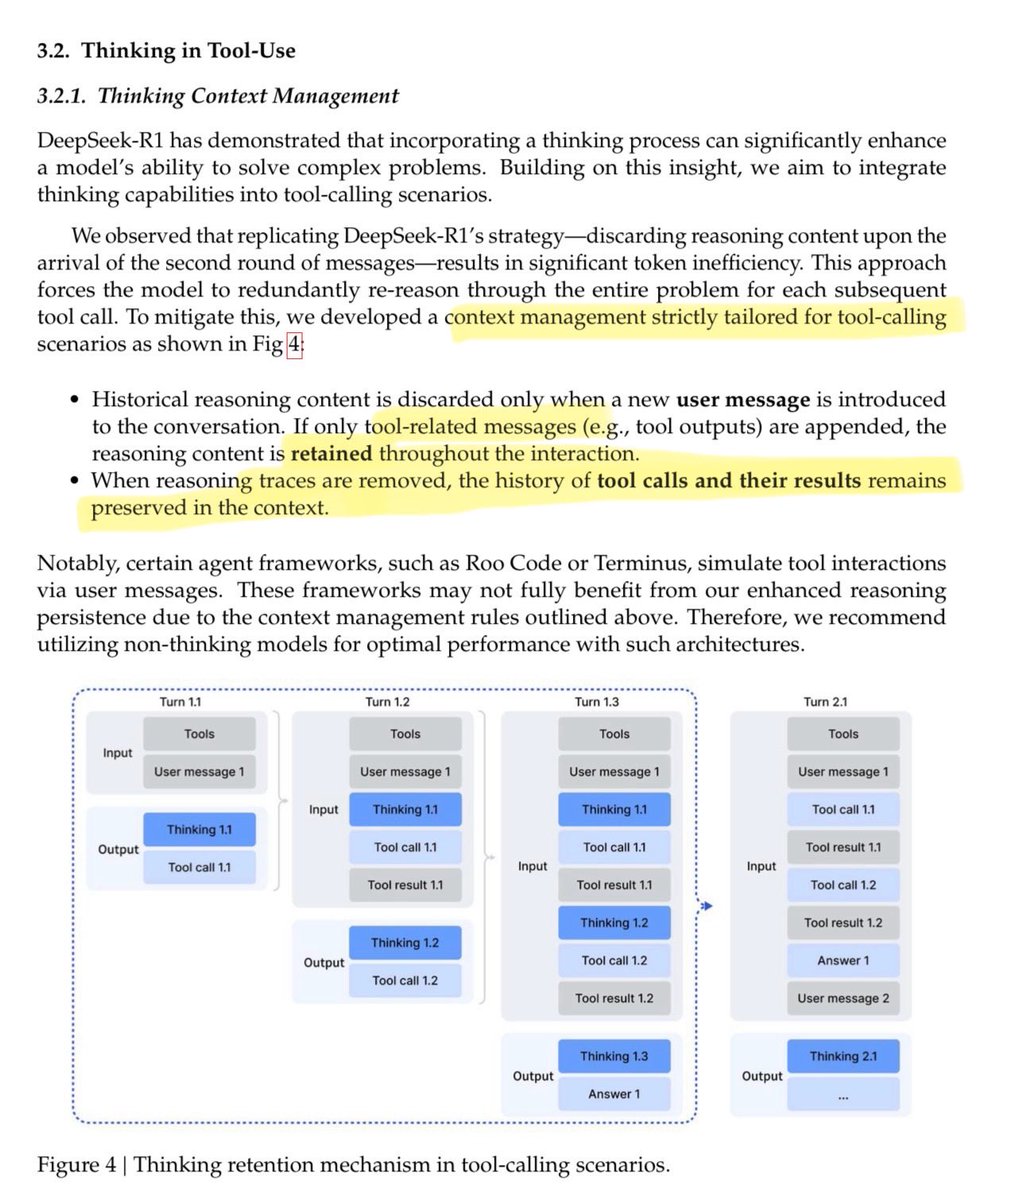
1) context management plus more context management
2) diversity of "agent configurations" (different checkpoints, system prompts)
3) scaling task/environment creation, yielding thousands of < env, tool, task, verifier > tuples
For (3), they show a noticeable saner delineation of these 4 categories than a current fan-favorite decentralized AI player... 👀
3/🧵
4
Even their limitations section reads like 🎤-drop:
1) they will scale pretraining further
2) they will focus on token efficiency
3) they will continue to chase frontier
Impressive morning-of-NeurIPS launch (ChatGPT-style) of DeepSeek Speciale (coming for the euro-centric players repackaging their work 👀)!
Nothing beats aura-farming like actually shipping in the open. 🫡
4/4
1) they will scale pretraining further
2) they will focus on token efficiency
3) they will continue to chase frontier
Impressive morning-of-NeurIPS launch (ChatGPT-style) of DeepSeek Speciale (coming for the euro-centric players repackaging their work 👀)!
Nothing beats aura-farming like actually shipping in the open. 🫡
4/4
5
lol they really do just roast themselves these days... 👀