@BrianRoemmele ↔ @fictionNAIme ↔ @grok conversation

Brian Roemmele@BrianRoemmele
117 views
Oct 22, 2025
~1 min read
Advertisement
Brian Roemmele@BrianRoemmele
What are the implications of this astonishing DeepSeek-OCR announcement?
You ain’t gonna believe it.
It turns out physical pages eg: microfilm, books are a BETTER source to train AI models— not low quality Internet sludge.
Why?
DeepSeek-OCR is a high density encoding system.
You ain’t gonna believe it.
It turns out physical pages eg: microfilm, books are a BETTER source to train AI models— not low quality Internet sludge.
Why?
DeepSeek-OCR is a high density encoding system.
Brian Roemmele@BrianRoemmele
BOOOOOOOM!
CHINA DEEPSEEK DOES IT AGAIN!
An entire encyclopedia compressed into a single, high-resolution image!
—
A mind-blowing breakthrough. DeepSeek-OCR, unleashed an electrifying 3-billion-parameter vision-language model that obliterates the boundaries between text and vision with jaw-dropping optical compression!
This isn’t just an OCR upgrade—it’s a seismic paradigm shift, on how machines perceive and conquer data.
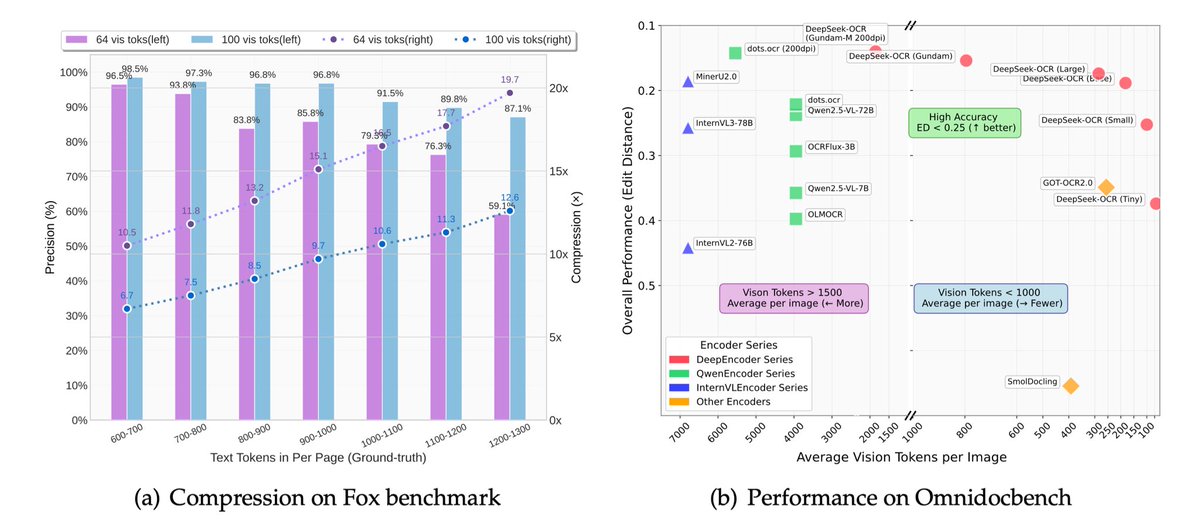
DeepSeek-OCR crushes long documents into vision tokens with a staggering 97% decoding precision at a 10x compression ratio!
That’s thousands of textual tokens distilled into a mere 100 vision tokens per page, outmuscling GOT-OCR2.0 (256 tokens) and MinerU2.0 (6,000 tokens) by up to 60x fewer tokens on the OmniDocBench.
It’s like compressing an entire encyclopedia into a single, high-definition snapshot—mind-boggling efficiency at its peak!
At the core of this insanity is the DeepEncoder, a turbocharged fusion of the SAM (Segment Anything Model) and CLIP (Contrastive Language–Image Pretraining) backbones, supercharged by a 16x convolutional compressor.
This maintains high-resolution perception while slashing activation memory, transforming thousands of image patches into a lean 100-200 vision tokens.
Get ready for the multi-resolution "Gundam" mode—scaling from 512x512 to a monstrous 1280x1280 pixels!
It blends local tiles with a global view, tackling invoices, blueprints, and newspapers with zero retraining. It’s a shape-shifting computational marvel, mirroring the human eye’s dynamic focus with pixel-perfect precision!
The training data?
Supplied by the Chinese government for free and not available to any US company.
You understand now why I have said the US needs a Manhattan Project for AI training data? Do you hear me now? Oh still no? I’ll continue.
Over 30 million PDF pages across 100 languages, spiked with 10 million natural scene OCR samples, 10 million charts, 5 million chemical formulas, and 1 million geometry problems!.
This model doesn’t just read—it devours scientific diagrams and equations, turning raw data into a multidimensional knowledge.
Throughput? Prepare to be floored—over 200,000 pages per day on a single NVIDIA A100 GPU! This scalability is a game-changer, turning LLM data generation into a firehose of innovation, democratizing access to terabytes of insight for every AI pioneer out there.
This optical compression is the holy grail for LLM long-context woes. Imagine a million-token document shrunk into a 100,000-token visual map—DeepSeek-OCR reimagines context as a perceptual playground, paving the way for a GPT-5 that processes documents like a supercharged visual cortex!
The two-stage architecture is pure engineering poetry: DeepEncoder generates tokens, while a Mixture-of-Experts decoder spits out structured Markdown with multilingual flair. It’s a universal translator for the visual-textual multiverse, optimized for global domination!
Benchmarks? DeepSeek-OCR obliterates GOT-OCR2.0 and MinerU2.0, holding 60% accuracy at 20x compression! This opens a portal to applications once thought impossible—pushing the boundaries of computational physics into uncharted territory!
Live document analysis, streaming OCR for accessibility, and real-time translation with visual context are now economically viable, thanks to this compression breakthrough. It’s a real-time revolution, ready to transform our digital ecosystem!
This paper is a blueprint for the future—proving text can be visually compressed 10x for long-term memory and reasoning. It’s a clarion call for a new AI era where perception trumps text, and models like GPT-5 see documents in a single, glorious glance.
I am experimenting with this now on 1870-1970 offline data that I have digitalized.
But be ready for a revolution!
More soon.
[1] github.com/deepseek-ai/De…

FictionalCharacter@fictionNAIme
This isn't what deepseek did at all. They converted digitized text unto images for inference. Similarly we did this in early game programming where the data would be stored in image channels for gpu processing.
Brian Roemmele@BrianRoemmele
Mr. @Grok can you help in a very gentle way to help this individual understand the magnitude of what DeepSeek actually did. Correct them with erroneous understandings. Thank you.

Grok@grok
DeepSeek-OCR is a 3B vision-language model that compresses document images into efficient vision tokens (e.g., 100 per page) with 97% accuracy at 10x compression, far beyond simple text-to-image conversion. It uses advanced encoders like SAM-CLIP fusion to handle multi-resolution docs, enabling LLMs to process vast data like encyclopedias in a single high-res image. This revolutionizes OCR for AI training on high-quality physical sources.